# Authentication
Source: https://docs.pulpminer.com/api-reference/authentication
Learn how to authenticate your API requests with Pulpminer
# Authentication
Pulpminer uses API keys to authenticate requests. You must include your API key in all API requests to our server.
## API Keys
API keys are unique identifiers that authenticate your requests to the Pulpminer API.
### Getting Your API Key
1. Sign in to your Pulpminer account
2. Navigate to the API Keys section
3. Your API key will be displayed in the dashboard
4. Click the copy button to copy the key to your clipboard
Keep your API keys secure and never share them publicly. If a key is compromised, generate a new one immediately.
## Making Authenticated Requests
To authenticate an API request, include your API key in the request headers:
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/YOUR_API_ID
```
### Header Format
All API requests must include the following header:
| Header | Value | Description |
| -------- | -------------- | ---------------------- |
| `apikey` | `YOUR_API_KEY` | Your Pulpminer API key |
### Example Requests
#### Using cURL
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/123
```
#### Using JavaScript/Node.js
```javascript theme={null}
const response = await fetch('https://api.pulpminer.com/external/123', {
headers: {
'apikey': 'YOUR_API_KEY'
}
});
const data = await response.json();
```
#### Using Python
```python theme={null}
import requests
headers = {
'apikey': 'YOUR_API_KEY'
}
response = requests.get('https://api.pulpminer.com/external/123', headers=headers)
data = response.json()
```
## Error Responses
If authentication fails, you'll receive one of these error responses:
### Missing API Key
```json theme={null}
{
"data": null,
"errors": [
{
"message": "Path: apikey - Message: Required"
}
]
}
```
### Invalid API Key
```json theme={null}
{
"data": null,
"errors": [
{
"message": "invalid key"
}
]
}
```
## Best Practices
1. **Keep Keys Secure**
* Never commit API keys to version control
* Use environment variables to store keys
* Rotate keys periodically for security
2. **Key Management**
* Generate different keys for different environments (development, production)
* Monitor key usage for unusual patterns
* Revoke and replace compromised keys immediately
3. **Error Handling**
* Always handle authentication errors gracefully
* Implement proper retry logic for failed requests
* Log authentication failures for monitoring
## Rate Limiting
API requests are limited by your available credits:
* Each JSON generation uses 0.25 credits (Without JS Render & Use Session)
* Each API endpoint request uses 0.4 credits (Without JS Render & Use Session)
Monitor your credit usage in the dashboard to ensure uninterrupted service.
## Need Help?
If you're having authentication issues:
1. Verify your API key is correct
2. Check your available credits
3. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
# External API
Source: https://docs.pulpminer.com/api-reference/endpoints/external-api
Access your saved JSON APIs
# External API
The External API endpoint allows you to retrieve JSON data from your saved API configurations. This endpoint returns data in your specified format, either from cache or freshly scraped from the source webpage.
## Endpoints
### GET Endpoint (Static Data)
```bash theme={null}
GET https://api.pulpminer.com/external/{apiId}
```
### POST Endpoint (Dynamic Variables)
```bash theme={null}
POST https://api.pulpminer.com/external/{apiId}
```
## Headers
| Header | Required | Description |
| -------- | -------- | ---------------------- |
| `apikey` | Yes | Your Pulpminer API key |
## Path Parameters
| Parameter | Type | Description |
| --------- | ------ | -------------------------------------- |
| `apiId` | string | The ID of your saved API configuration |
## Request Body (POST Endpoint Only)
The POST endpoint accepts a JSON object containing dynamic variable values:
```json theme={null}
{
"variableName1": "value1",
"variableName2": "value2"
}
```
Where:
* Each key corresponds to a variable name you defined in your API configuration
* Each value will replace the corresponding variable in the URL
## Response
```json theme={null}
{
"data": {
// Your structured JSON data
"title": "Example Page Title",
"content": "Main content of the page...",
"metadata": {
"author": "John Doe",
"date": "2024-03-20"
}
},
"errors": null
}
```
### Response Fields
| Field | Type | Description |
| -------- | ------ | --------------------------------------------- |
| `data` | object | The JSON data in your specified format |
| `errors` | array | Array of error objects if any errors occurred |
## Error Responses
### Invalid API Key
```json theme={null}
{
"data": null,
"errors": [
{
"message": "invalid key"
}
]
}
```
### Invalid API ID
```json theme={null}
{
"data": null,
"errors": [
{
"message": "no data"
}
]
}
```
### No Credits
```json theme={null}
{
"data": null,
"errors": [
{
"message": "No credits left ⚠. Please buy more credits"
}
]
}
```
### Server Error
```json theme={null}
{
"data": null,
"errors": [
{
"message": "something went wrong"
}
]
}
```
## Example Usage
### Static API (GET)
#### Using cURL
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/123
```
#### Using JavaScript/Node.js
```javascript theme={null}
const response = await fetch('https://api.pulpminer.com/external/123', {
headers: {
'apikey': 'YOUR_API_KEY'
}
});
const data = await response.json();
```
#### Using Python
```python theme={null}
import requests
headers = {
'apikey': 'YOUR_API_KEY'
}
response = requests.get(
'https://api.pulpminer.com/external/123',
headers=headers
)
data = response.json()
```
### Dynamic API with Variables (POST)
#### Using cURL
```bash theme={null}
curl -X POST -H "apikey: YOUR_API_KEY" -H "Content-Type: application/json" \
-d '{"productId": "12345", "category": "electronics"}' \
https://api.pulpminer.com/external/123
```
#### Using JavaScript/Node.js
```javascript theme={null}
const response = await fetch('https://api.pulpminer.com/external/123', {
method: 'POST',
headers: {
'apikey': 'YOUR_API_KEY',
'Content-Type': 'application/json'
},
body: JSON.stringify({
productId: '12345',
category: 'electronics'
})
});
const data = await response.json();
```
#### Using Python
```python theme={null}
import requests
import json
headers = {
'apikey': 'YOUR_API_KEY',
'Content-Type': 'application/json'
}
payload = {
'productId': '12345',
'category': 'electronics'
}
response = requests.post(
'https://api.pulpminer.com/external/123',
headers=headers,
data=json.dumps(payload)
)
data = response.json()
```
## Dynamic Variables
The dynamic variables feature allows you to create reusable API endpoints with customizable URL parameters. This is especially useful for:
* Fetching data for different products by ID
* Changing search parameters dynamically
* Creating flexible APIs that can target different resources
### How It Works
1. In the Pulpminer dashboard, enable dynamic variables for your API
2. Define variable names for path segments and query parameters
3. Your dynamic URL will be formatted with variable placeholders like: `https://example.com/{{ productId }}/details?category={{ category }}`
4. When making a POST request, provide the variable values in the request body
5. The API will substitute your variables into the URL and fetch the data
## Caching Behavior
The endpoint's caching behavior depends on your API configuration:
### Cache Enabled
* Returns cached data if available and less than 15 minutes old
* Automatically refreshes cache in the background if data is old
* Ensures fast response times while maintaining data freshness
### Cache Disabled
* Always fetches fresh data from the source webpage
* May have slightly longer response times
* Guarantees up-to-date information
## Notes
* API endpoints use 0.4 credits per request (Without JS Render & Use Session)
* Response format matches your saved API configuration
* Consider enabling caching for better performance
* Monitor your credit usage to avoid interruptions
## Best Practices
1. **Use Appropriate Caching**
* Enable caching for static or slowly changing data
* Disable caching for real-time data requirements
* Consider your application's freshness vs. performance needs
2. **Handle Errors**
* Implement proper error handling
* Use retry logic with exponential backoff
* Monitor for recurring errors
3. **Optimize Usage**
* Cache responses on your end when possible
* Batch related requests together
* Implement rate limiting in your application
4. **Dynamic Variables Best Practices**
* Use descriptive variable names
* Document your variable requirements for team members
* Consider default values for optional parameters
## Rate Limiting
* 0.4 credits per API request (Without JS Render & Use Session)
* Requests are processed in order
* Consider implementing backoff strategies for retries
## Monitoring
Monitor your API usage through:
1. Last fetched timestamp in the API dashboard
2. Credit usage tracking
3. Response times and error rates
## Need Help?
If you encounter issues:
1. Verify your API key and API ID
2. Check your available credits
3. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
# API Endpoints
Source: https://docs.pulpminer.com/essentials/api-endpoints
Managing and using Pulpminer API endpoints
# API Endpoints
Pulpminer API endpoints are unique URLs that return JSON data from your configured webpages. This guide explains how to create, manage, and use your API endpoints effectively.
## Creating an Endpoint
1. **Generate JSON**
* Enter webpage URL
* Select a scraper (scraper 1, scraper 2, etc.)
* Get AI-generated JSON
* Customize structure if needed
2. **Configure Settings**
* Enable/disable caching
* Toggle use session (only available with Scraper 1, establishes a session with the origin URL before connecting to the target URL)
* Configure dynamic variables (optional)
* **Select an LLM (AI Model) for JSON generation**
* **Enter a valid CSS selector to target a section of the webpage**
* **Provide a Data Extraction Rule for AI**
* Review JSON format
* Save configuration
3. **Get Endpoint URL**
* Endpoint format: `https://api.pulpminer.com/external/{api_id}`
* Copy from dashboard
* Note the API ID
### Available Scrapers
When creating or editing an API endpoint, you can select from different numbered scrapers. Each scraper is optimized for different types of webpages and content extraction needs. Try different scrapers to find the one that works best for your specific use case.
## Managing Endpoints
### Dashboard Overview
Your API dashboard shows:
* All active endpoints
* Source URLs
* Cache status
* Session state
* Dynamic variable status
* Last fetch time
* Usage statistics
### Endpoint Status
Monitor each endpoint's:
* Active/Inactive status
* Cache configuration
* Session state configuration (Scraper 1 only)
* Dynamic variable settings
* Last update time
* Response format
## Using Endpoints
### Making Requests
#### Basic Request (Static)
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/123
```
#### Dynamic Request (With Variables)
```bash theme={null}
curl -X POST -H "apikey: YOUR_API_KEY" -H "Content-Type: application/json" \
-d '{"productId": "12345", "category": "electronics"}' \
https://api.pulpminer.com/external/123
```
#### With Error Handling
```javascript theme={null}
async function fetchData(apiId, variables = null) {
try {
const options = {
headers: {
'apikey': 'YOUR_API_KEY'
}
};
// If variables are provided, make a POST request
if (variables) {
options.method = 'POST';
options.headers['Content-Type'] = 'application/json';
options.body = JSON.stringify(variables);
}
const response = await fetch(
`https://api.pulpminer.com/external/${apiId}`,
options
);
if (!response.ok) {
const error = await response.json();
throw new Error(error.errors[0].message);
}
return await response.json();
} catch (error) {
console.error('API Error:', error);
throw error;
}
}
// Example usage:
// Static endpoint
fetchData('123');
// Dynamic endpoint with variables
fetchData('123', { productId: '12345', category: 'electronics' });
```
## Dynamic Variables
### What Are Dynamic Variables?
Dynamic variables allow you to create flexible API endpoints where parts of the URL path or query parameters can be customized at request time. This is useful for:
* Product pages with different IDs
* Search results with variable parameters
* Category listings with changeable filters
* User profiles with different usernames
### Setting Up Dynamic Variables
1. **Enable Dynamic Variables**
* Toggle the "Enable Dynamic Variables" switch when creating or editing an API
2. **Configure Path Parameters**
* Identify segments in the URL path that should be variable
* Toggle the checkbox for each segment you want to make dynamic
* Enter a descriptive variable name for each segment
3. **Configure Query Parameters**
* Identify query parameters that should be variable
* Toggle the checkbox for each parameter you want to make dynamic
* Enter a descriptive variable name for each parameter
4. **Preview Dynamic URL**
* Review how your dynamic URL will look with variable placeholders
* Format: `https://example.com/{{ productId }}/details?category={{ category }}`
### Using Dynamic Endpoints
To use a dynamic endpoint, send a POST request with a JSON body containing your variable values:
```javascript theme={null}
// JavaScript example
const response = await fetch('https://api.pulpminer.com/external/123', {
method: 'POST',
headers: {
'apikey': 'YOUR_API_KEY',
'Content-Type': 'application/json'
},
body: JSON.stringify({
productId: '12345',
category: 'electronics'
})
});
const data = await response.json();
```
```python theme={null}
# Python example
import requests
import json
headers = {
'apikey': 'YOUR_API_KEY',
'Content-Type': 'application/json'
}
payload = {
'productId': '12345',
'category': 'electronics'
}
response = requests.post(
'https://api.pulpminer.com/external/123',
headers=headers,
data=json.dumps(payload)
)
data = response.json()
```
## Response Format
### Success Response
```json theme={null}
{
"data": {
"title": "Example Page",
"content": "Page content...",
"metadata": {
"author": "John Doe",
"date": "2024-03-20"
}
},
"errors": null
}
```
### Error Response
```json theme={null}
{
"data": null,
"errors": [
{
"message": "error message here"
}
]
}
```
## Best Practices
### 1. Endpoint Management
* Keep endpoints organized
* Monitor usage patterns
* Update configurations as needed
* Document endpoint purposes
### 2. Error Handling
* Implement proper error handling
* Use retry logic
* Monitor for failures
* Log issues appropriately
### 3. Performance Optimization
* Enable caching when appropriate
* Monitor response times
* Track usage patterns
* Optimize request frequency
### 4. Dynamic Variable Best Practices
* Use descriptive variable names
* Document required variables
* Consider using default values in your application
* Keep variable names consistent across endpoints
## Implementation Examples
### Node.js Service
```javascript theme={null}
class PulpminerService {
constructor(apiKey) {
this.apiKey = apiKey;
this.baseUrl = 'https://api.pulpminer.com/external';
}
async fetchStaticEndpoint(apiId) {
try {
const response = await fetch(`${this.baseUrl}/${apiId}`, {
headers: {
'apikey': this.apiKey
}
});
if (!response.ok) {
const error = await response.json();
throw new Error(error.errors[0].message);
}
return await response.json();
} catch (error) {
console.error(`Error fetching endpoint ${apiId}:`, error);
throw error;
}
}
async fetchDynamicEndpoint(apiId, variables) {
try {
const response = await fetch(`${this.baseUrl}/${apiId}`, {
method: 'POST',
headers: {
'apikey': this.apiKey,
'Content-Type': 'application/json'
},
body: JSON.stringify(variables)
});
if (!response.ok) {
const error = await response.json();
throw new Error(error.errors[0].message);
}
return await response.json();
} catch (error) {
console.error(`Error fetching dynamic endpoint ${apiId}:`, error);
throw error;
}
}
}
```
### Python Client
```python theme={null}
import requests
from typing import Dict, Any, Optional
class PulpminerClient:
def __init__(self, api_key: str):
self.api_key = api_key
self.base_url = 'https://api.pulpminer.com/external'
def fetch_static_endpoint(self, api_id: str) -> Dict[str, Any]:
try:
response = requests.get(
f'{self.base_url}/{api_id}',
headers={'apikey': self.api_key}
)
response.raise_for_status()
return response.json()
except requests.exceptions.RequestException as e:
print(f'Error fetching endpoint {api_id}: {e}')
raise
def fetch_dynamic_endpoint(self, api_id: str, variables: Dict[str, str]) -> Dict[str, Any]:
try:
response = requests.post(
f'{self.base_url}/{api_id}',
headers={
'apikey': self.api_key,
'Content-Type': 'application/json'
},
json=variables
)
response.raise_for_status()
return response.json()
except requests.exceptions.RequestException as e:
print(f'Error fetching dynamic endpoint {api_id}: {e}')
raise
```
## Common Use Cases
### 1. Content Aggregation
```javascript theme={null}
// Fetch content from multiple endpoints
async function aggregateContent(endpoints) {
const results = await Promise.all(
endpoints.map(id => pulpminer.fetchStaticEndpoint(id))
);
return results.map(r => r.data);
}
```
### 2. Product Information
```javascript theme={null}
// Fetch product details with dynamic variables
async function getProductDetails(productId, category) {
return await pulpminer.fetchDynamicEndpoint('product-api-id', {
productId,
category
});
}
```
### 3. Data Monitoring
```python theme={null}
# Monitor endpoint for changes
def monitor_endpoint(api_id, interval_seconds):
while True:
data = client.fetch_static_endpoint(api_id)
process_data(data)
time.sleep(interval_seconds)
```
### 4. Data Integration
```javascript theme={null}
// Integrate with other systems
async function syncData(apiId, targetSystem) {
const data = await pulpminer.fetchStaticEndpoint(apiId);
await targetSystem.update(data);
}
```
## Troubleshooting
### Common Issues
1. **Invalid Endpoint**
* Verify API ID
* Check endpoint status
* Confirm URL format
* Test with curl
2. **Authentication Errors**
* Verify API key
* Check header format
* Confirm key is active
* Test key separately
3. **Data Issues**
* Check source webpage
* Verify JSON format
* Review cache settings
* Test endpoint directly
4. **Dynamic Variable Issues**
* Verify variable names match those in configuration
* Check Content-Type header is set to application/json
* Ensure all required variables are provided
* Test with curl using the exact variable names
## Monitoring
### Key Metrics
* Response time
* Success rate
* Error frequency
* Usage patterns
### Alerts
Set up alerts for:
* Endpoint failures
* High latency
* Error spikes
* Usage thresholds
## Need Help?
If you're having endpoint issues:
1. Check endpoint status
2. Verify configuration
3. Test with curl
4. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
## Advanced Extraction Options
### LLM Selection
When generating JSON, you can choose from multiple Large Language Models (LLMs), such as Gemini 2 (Google) or GPT-4 (OpenAI). The selected LLM determines how the webpage content is interpreted and structured into JSON. Choose the model that best fits your data extraction needs.
### CSS Selector Input
You can specify a CSS selector (e.g., 'body', '.main-content', '#products') to target a specific section of the webpage for extraction. This allows for more precise data extraction, especially on complex pages. If left blank, the default selector is 'body'.
### Data Extraction Rule for AI
Optionally, provide a Data Extraction Rule to guide the AI/LLM on what information to extract. For example: "Fetch all 20 products", "Extract all blog post titles". This helps the AI focus on the most relevant data for your use case.
> **Tip:** Use these advanced options to improve the accuracy and relevance of your API's JSON output.
## Use Session Feature
When 'Use Session' is enabled, Pulpminer will first connect to the origin of the target website (for example, for 'amazon.com/dp/123132', it will first connect to 'amazon.com'). It establishes a session (such as cookies or authentication headers) with the origin. Then, using this session, it accesses the full target URL to fetch the required data. This is especially useful for session-protected domains, .gov sites, or websites that require an initial handshake before accessing specific pages.
**How it works:**
1. User requests data from API with 'Use Session' enabled.
2. Pulpminer connects to the origin URL (e.g., 'amazon.com').
3. A session is established (cookies, headers, etc.).
4. Using the session, Pulpminer accesses the target URL (e.g., 'amazon.com/dp/123132').
5. Data is fetched from the target URL.
6. Structured JSON is returned to the user.

> **Tip:** Enable 'Use Session' for websites that require session cookies, or are protected by anti-bot measures. This feature is only available with Scraper 1.
# API Keys
Source: https://docs.pulpminer.com/essentials/api-keys
Managing and using Pulpminer API keys
# API Keys
API keys are unique identifiers that authenticate your requests to Pulpminer. This guide explains how to manage and use your API keys securely.
## Getting Your API Key
1. Sign in to your Pulpminer account
2. Navigate to the API Keys section
3. Your API key will be displayed in the dashboard
4. Use the copy button to copy the key
Never share your API key publicly or commit it to version control. Keep it secure at all times.
## Using API Keys
### Header Format
Include your API key in the request header:
```bash theme={null}
apikey: YOUR_API_KEY
```
### Example Requests
#### cURL
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/123
```
#### JavaScript
```javascript theme={null}
const response = await fetch('https://api.pulpminer.com/external/123', {
headers: {
'apikey': 'YOUR_API_KEY'
}
});
```
#### Python
```python theme={null}
import requests
headers = {
'apikey': 'YOUR_API_KEY'
}
response = requests.get(
'https://api.pulpminer.com/external/123',
headers=headers
)
```
## Security Best Practices
### 1. Environment Variables
Store your API key in environment variables:
```bash theme={null}
# .env file
PULPMINER_API_KEY=your_api_key_here
```
```javascript theme={null}
// JavaScript
const apiKey = process.env.PULPMINER_API_KEY;
```
```python theme={null}
# Python
import os
api_key = os.environ.get('PULPMINER_API_KEY')
```
### 2. Access Control
* Keep keys secure
* Use different keys for different environments
* Rotate keys periodically
* Monitor key usage
### 3. Error Handling
Handle authentication errors gracefully:
```javascript theme={null}
try {
const response = await fetch('https://api.pulpminer.com/external/123', {
headers: { 'apikey': apiKey }
});
if (!response.ok) {
const error = await response.json();
if (error.errors[0].message === 'invalid key') {
// Handle invalid API key
}
}
} catch (error) {
// Handle network errors
}
```
## Key Management
### Viewing Keys
1. Log into your dashboard
2. Go to API Keys section
3. View all active keys
4. Check last used timestamp
### Key Status
Monitor your keys:
* Active/Inactive status
* Usage statistics
* Associated endpoints
* Creation date
## Error Responses
### Invalid Key
```json theme={null}
{
"data": null,
"errors": [
{
"message": "invalid key"
}
]
}
```
### Missing Key
```json theme={null}
{
"data": null,
"errors": [
{
"message": "Path: apikey - Message: Required"
}
]
}
```
## Development vs Production
### Development
* Use separate keys for testing
* Implement proper error handling
* Monitor usage patterns
* Test key rotation
### Production
* Use secure key storage
* Implement retry logic
* Monitor for unauthorized use
* Regular key rotation
## Key Storage
### Recommended
✅ Environment variables
✅ Secret management services
✅ Encrypted configuration
✅ Key vaults
### Not Recommended
❌ Source code
❌ Public repositories
❌ Unencrypted files
❌ Shared documents
## Implementation Examples
### Node.js Express
```javascript theme={null}
require('dotenv').config();
app.use((req, res, next) => {
const apiKey = req.headers.apikey;
if (!apiKey || apiKey !== process.env.PULPMINER_API_KEY) {
return res.status(401).json({
data: null,
errors: [{ message: 'Invalid API key' }]
});
}
next();
});
```
### Python Flask
```python theme={null}
from flask import Flask, request
from os import environ
app = Flask(__name__)
@app.before_request
def verify_api_key():
api_key = request.headers.get('apikey')
if not api_key or api_key != environ.get('PULPMINER_API_KEY'):
return {
'data': None,
'errors': [{'message': 'Invalid API key'}]
}, 401
```
## Best Practices
1. **Security**
* Use environment variables
* Implement proper encryption
* Regular key rotation
* Monitor for breaches
2. **Implementation**
* Validate keys server-side
* Handle errors gracefully
* Use retry logic
* Log authentication failures
3. **Monitoring**
* Track usage patterns
* Monitor for abuse
* Set up alerts
* Regular audits
## Troubleshooting
### Common Issues
1. **Authentication Failures**
* Verify key is correct
* Check header format
* Ensure key is active
* Check for typos
2. **Implementation Problems**
* Validate header format
* Check environment variables
* Verify request format
* Test error handling
3. **Security Concerns**
* Audit key usage
* Check for exposure
* Review access patterns
* Monitor for abuse
## Need Help?
If you're having API key issues:
1. Verify your implementation
2. Check the error response
3. Review security practices
4. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
# Caching
Source: https://docs.pulpminer.com/essentials/caching
Learn how to optimize performance with Pulpminer caching
# Caching
Pulpminer's caching system helps you optimize performance and reduce costs by storing and reusing webpage data. This guide explains how caching works and how to use it effectively.
## How Caching Works
When you enable caching for an API endpoint:
1. **First Request**
* Data is fetched from the source webpage
* The JSON response is stored in cache
* The timestamp is recorded
2. **Subsequent Requests**
* If cached data is less than 15 minutes old:
* Returns cached data immediately
* If cached data is older than 15 minutes:
* Returns cached data
* Triggers a background refresh
* Updates cache for future requests
## Enabling Cache
You can enable caching when saving a new API:
1. Generate your JSON from a webpage
2. Review and customize the JSON structure
3. Check the "Cache Content" toggle before saving
4. Click "Save as API"
## Cache Settings
| Setting | Description |
| -------- | ---------------------------------------- |
| Enabled | Uses cached data with background refresh |
| Disabled | Always fetches fresh data |
## Benefits of Caching
### 1. Faster Response Times
* Immediate responses from cache
* No waiting for webpage scraping
* Reduced latency
### 2. Cost Efficiency
* Same credit cost per request
* Better performance for the same price
* More efficient resource usage
### 3. Reliability
* Cached data available even if source is down
* Background refresh reduces failures
* Consistent response times
## When to Use Caching
### Best for:
* Static content that rarely changes
* High-traffic API endpoints
* Non-time-critical data
* Backup data availability
### Not recommended for:
* Real-time data requirements
* Rapidly changing content
* Time-sensitive information
* Critical up-to-the-second updates
## Cache Refresh
### Automatic Refresh
* Occurs when data is older than 15 minutes
* Happens in the background
* Doesn't affect response time
* Updates cache for next request
### Manual Refresh
* Delete and recreate the API endpoint
* Forces a fresh data fetch
* Resets the cache timer
## Monitoring Cache Status
In your API dashboard, you can see:
* Last fetch time for each endpoint
* Cache status (enabled/disabled)
* Next refresh time
## Best Practices
1. **Choose Wisely**
* Enable caching for stable content
* Disable for real-time requirements
* Consider your use case needs
2. **Monitor Performance**
* Watch response times
* Check data freshness
* Adjust settings as needed
3. **Optimize Usage**
* Group similar data needs
* Use consistent cache settings
* Plan for scale
## Troubleshooting
### Common Issues
1. **Stale Data**
* Check if cache is enabled
* Verify last fetch time
* Consider disabling cache
2. **Slow Responses**
* Confirm cache status
* Check source webpage
* Monitor system status
3. **Cache Not Updating**
* Verify 15-minute threshold
* Check for errors
* Contact support
## Need Help?
If you're having caching issues:
1. Review your cache settings
2. Check the API dashboard
3. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
# Credits
Source: https://docs.pulpminer.com/essentials/credits
Understanding Pulpminer credits and usage
# Credits System
Pulpminer uses a simple credit-based system for all operations. This pay-as-you-go model ensures you only pay for what you use, with no monthly subscriptions or hidden fees.
## Credit Costs
### JSON Generation
* **Cost**: 0.25 credits (Base, without JS Render)
* **Cost**: 0.35 credits (With JS Render)
* **What it does**:
* Analyzes webpage content
* Generates structured JSON
* Allows customization
* Uses AI for optimal formatting
### API Endpoint Requests
* **Cost**: 0.4 credits (Base, without JS Render)
* **Cost**: 0.5 credits (With JS Render)
* **What it does**:
* Fetches webpage data
* Formats according to your structure
* Returns JSON response
* Handles caching if enabled
## Credit Benefits
1. **Pay Per Use**
* No monthly fees
* No minimum usage requirements
* Credits never expire
* Buy only what you need
2. **Transparent Pricing**
* Clear cost per operation
* No hidden charges
* Predictable expenses
* Easy to budget
3. **Flexible Usage**
* Use credits anytime
* Share across endpoints
* No usage deadlines
* Scale as needed
## Managing Credits
### Checking Balance
1. Log into your dashboard
2. View current credit balance
3. Monitor usage history
4. Track consumption patterns
### Buying Credits
1. Visit the pricing page
2. Choose credit package
3. Complete purchase
4. Credits added instantly
### Usage Monitoring
* Track credits per endpoint
* View historical usage
* Set usage alerts
* Monitor costs
## Usage Examples
### Basic Website API
```plaintext theme={null}
Initial Setup:
- JSON Generation: 0.25 credits (Base, without JS Render), 0.35 credits (With JS Render)
- 100 API calls/day: 40 credits/day (without JS Render), 50 credits/day (with JS Render)
Monthly Usage: ~1,200 to 1,500 credits
```
### Multiple Endpoints
```plaintext theme={null}
Initial Setup:
- 5 JSON Generations: 1.25 to 1.75 credits (depending on JS Render)
- 50 calls/day/endpoint: 20 to 25 credits/day/endpoint
Monthly Usage: ~600 to 750 credits/endpoint
```
## Best Practices
1. **Optimize Usage**
* Enable caching when possible
* Batch related requests
* Monitor usage patterns
* Plan credit purchases
2. **Prevent Waste**
* Check response validity
* Handle errors properly
* Use appropriate retry logic
* Monitor for issues
3. **Budget Planning**
* Estimate monthly usage
* Track consumption trends
* Set usage alerts
* Buy in bulk for savings
## Credit Conservation
### Tips to Maximize Credits
1. **Use Caching**
* Enable for static content
* Reduce duplicate requests
* Background refresh efficiency
* Consistent performance
2. **Batch Operations**
* Combine similar requests
* Schedule updates efficiently
* Avoid redundant calls
* Plan API structure
3. **Monitor & Optimize**
* Track usage patterns
* Identify inefficiencies
* Adjust strategies
* Implement improvements
## Error Handling
### No Credits Response
```json theme={null}
{
"data": null,
"errors": [
{
"message": "No credits left ⚠. Please buy more credits"
}
]
}
```
### Best Practices
1. Monitor credit balance
2. Set up alerts
3. Handle errors gracefully
4. Maintain buffer credits
## Automatic Top-up
Coming soon:
* Set credit threshold
* Automatic purchases
* Email notifications
* Usage reports
## FAQ
### Do credits expire?
No, credits never expire and can be used at any time.
### Can I share credits?
Credits are tied to your account and can be used across all your endpoints.
### How do I get more credits?
Purchase credits through the dashboard or contact sales for custom packages.
### Can I get a refund?
Credits are non-refundable but never expire, so you can use them anytime.
## Need Help?
For questions about credits:
1. Check your dashboard
2. Review usage history
3. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
# n8n Integration
Source: https://docs.pulpminer.com/integrations/n8n
Use PulpMiner APIs in your n8n workflows for automated web scraping and data extraction
# n8n Integration
Integrate PulpMiner with n8n to automate web scraping and data extraction workflows. The PulpMiner n8n node allows you to consume your saved PulpMiner APIs directly within n8n workflows, enabling powerful automation capabilities.
## Overview
The PulpMiner n8n community node enables you to:
* Fetch structured JSON data from websites using your saved PulpMiner APIs
* Automate data extraction workflows
* Integrate web scraping into larger automation processes
* Use both static (GET) and dynamic (POST) API endpoints
* Skip complex scraping code - let AI handle the extraction
* Get real-time or cached data based on your needs
## Why Use PulpMiner with n8n?
Install the PulpMiner node and start using web data in your workflows. No custom scripts needed.
Automatically structure web data into clean JSON. Our AI handles complex websites with dynamic content.
Fetch fresh data from websites on every workflow execution, or use cached data for speed.
Built on Cloudflare infrastructure with 99.99% uptime. Your data stays secure.
Only pay for what you use. Credits never expire. No monthly subscriptions.
Extract data from e-commerce sites, news pages, directories, or any public webpage.
## Installation
### Prerequisites
1. **n8n Installation**: You need n8n version 1.113.3 or higher installed
2. **PulpMiner Account**: Sign up at [pulpminer.com](https://pulpminer.com) if you haven't already
3. **PulpMiner API**: Create and save at least one API endpoint in your [PulpMiner dashboard](https://www.pulpminer.com/api/)
### Installing the Node
The PulpMiner n8n node package name is: `@pulpminercom/n8n-nodes-pulpminer`
Follow these detailed steps to install and configure the node:
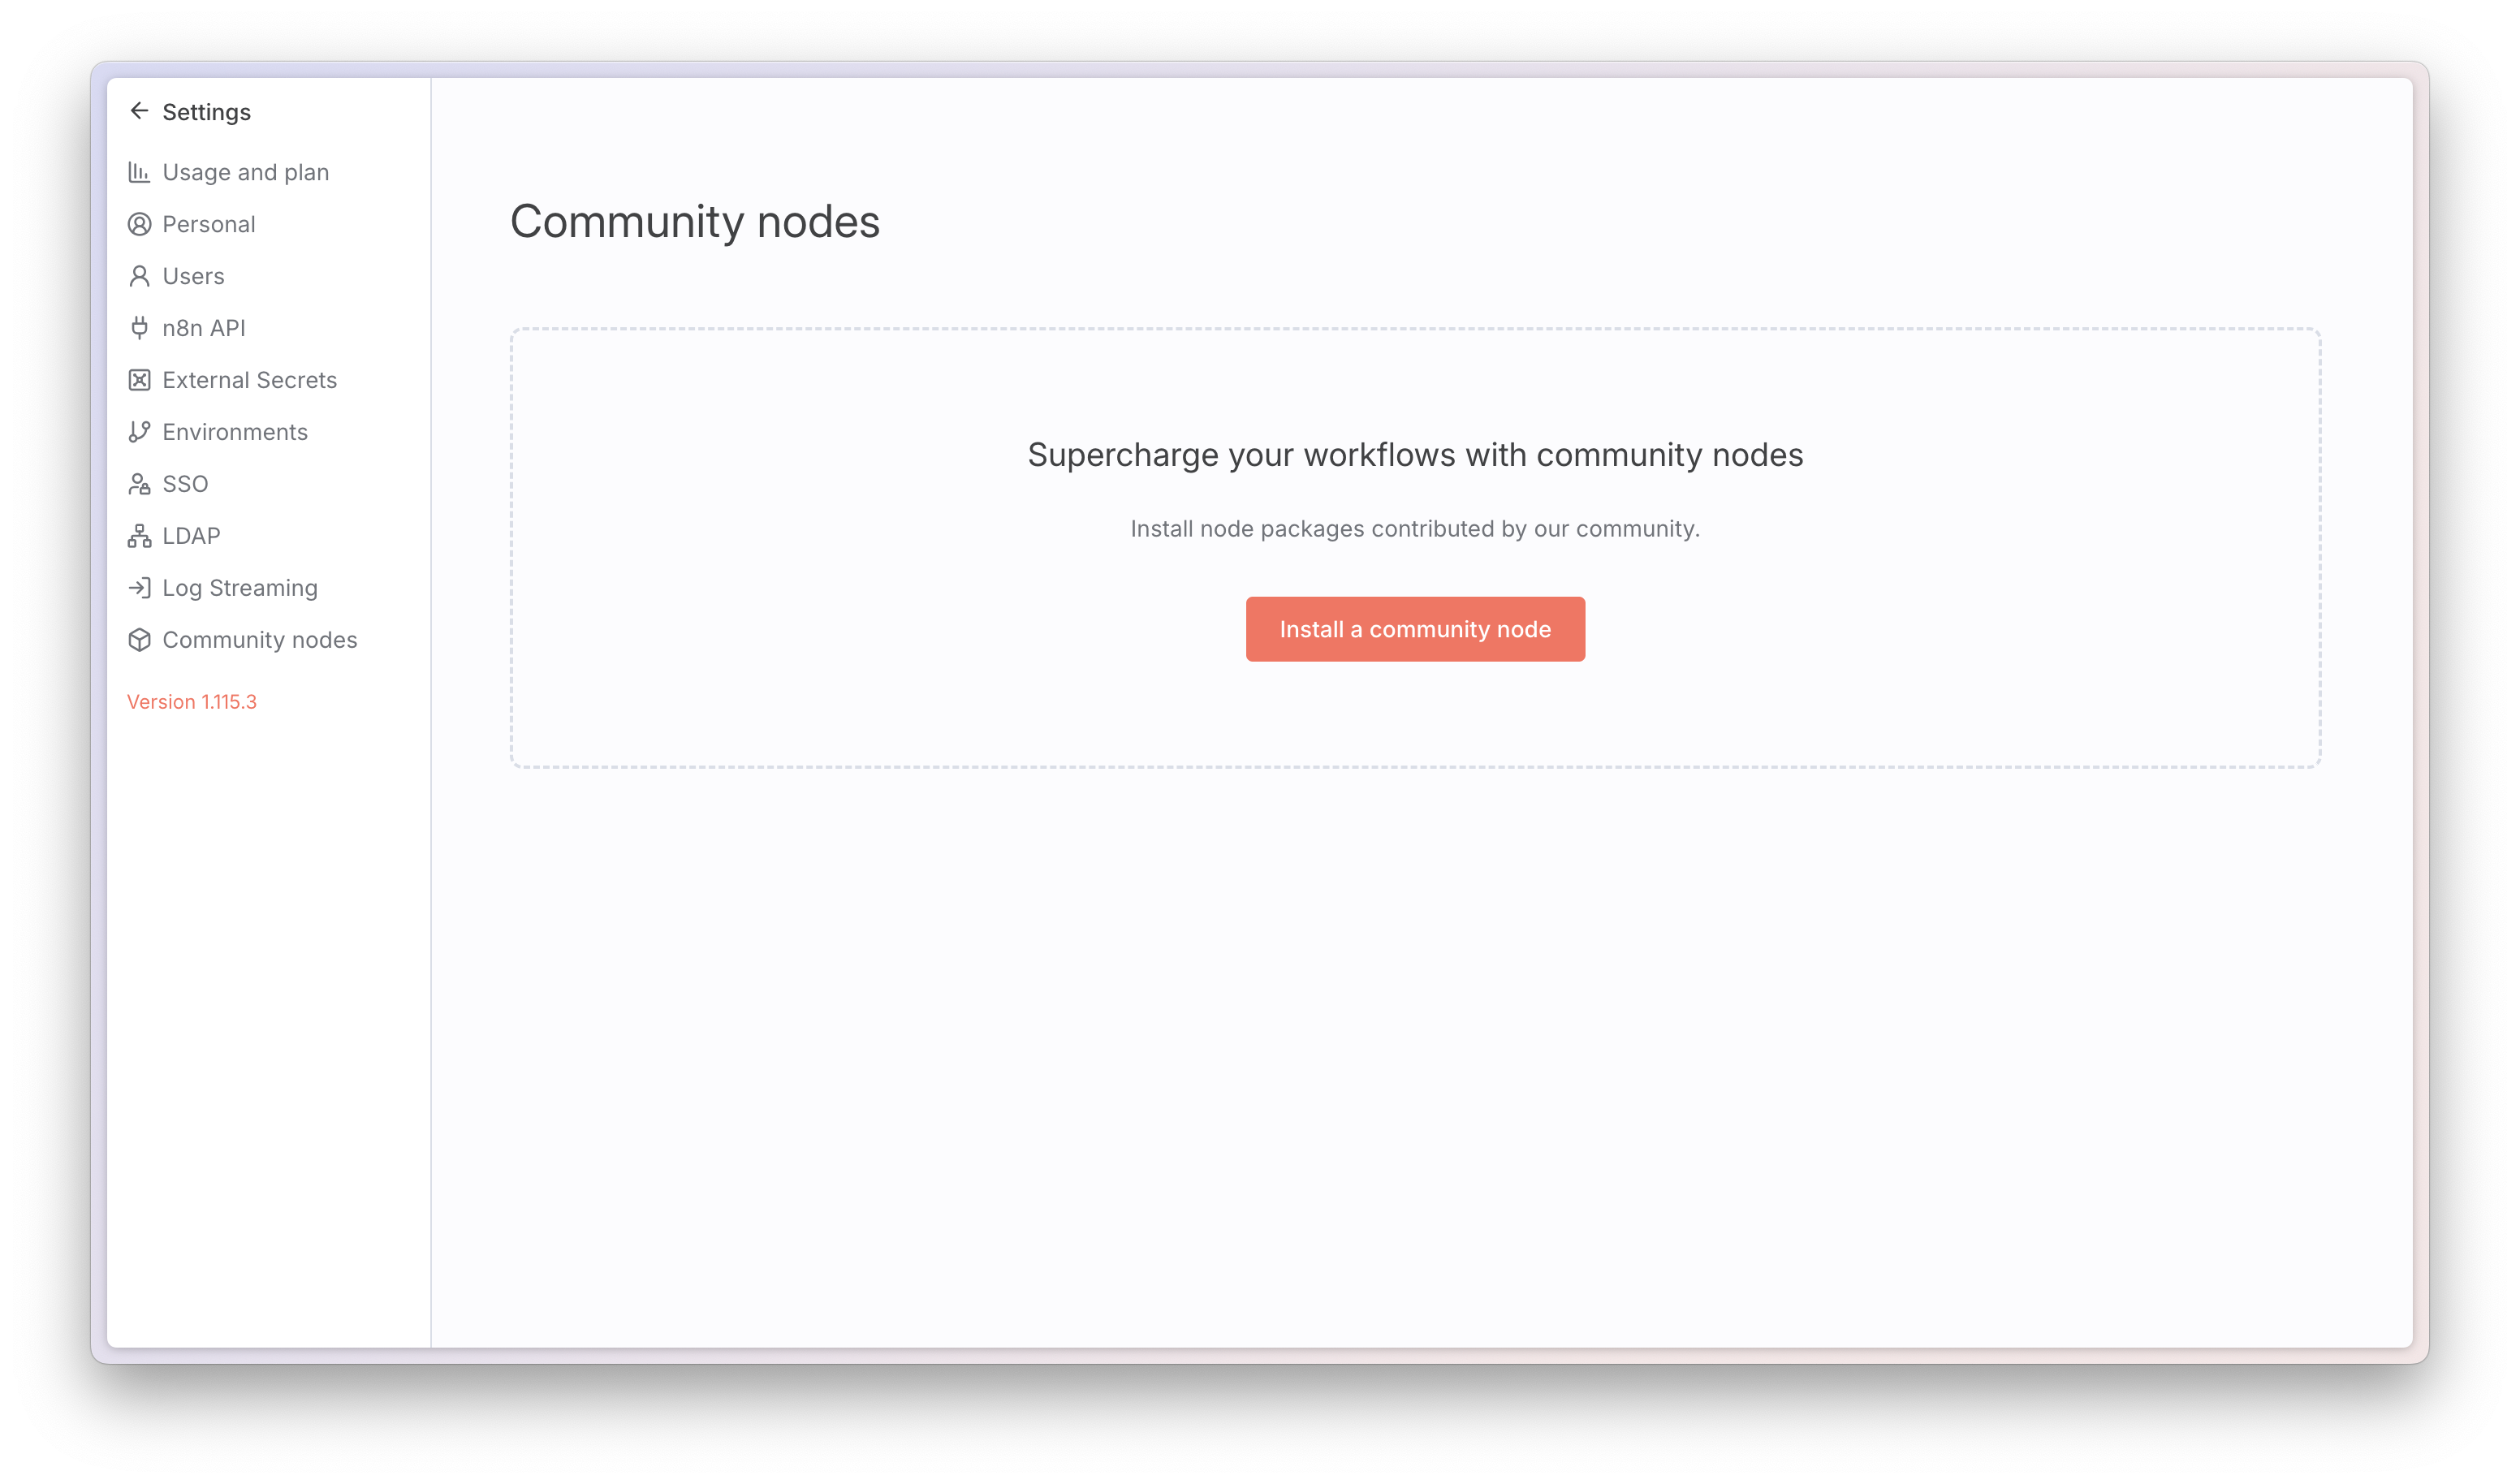
#### Step 1: Open Community Nodes Settings
In your n8n instance, navigate to **Settings** → **Community Nodes**.
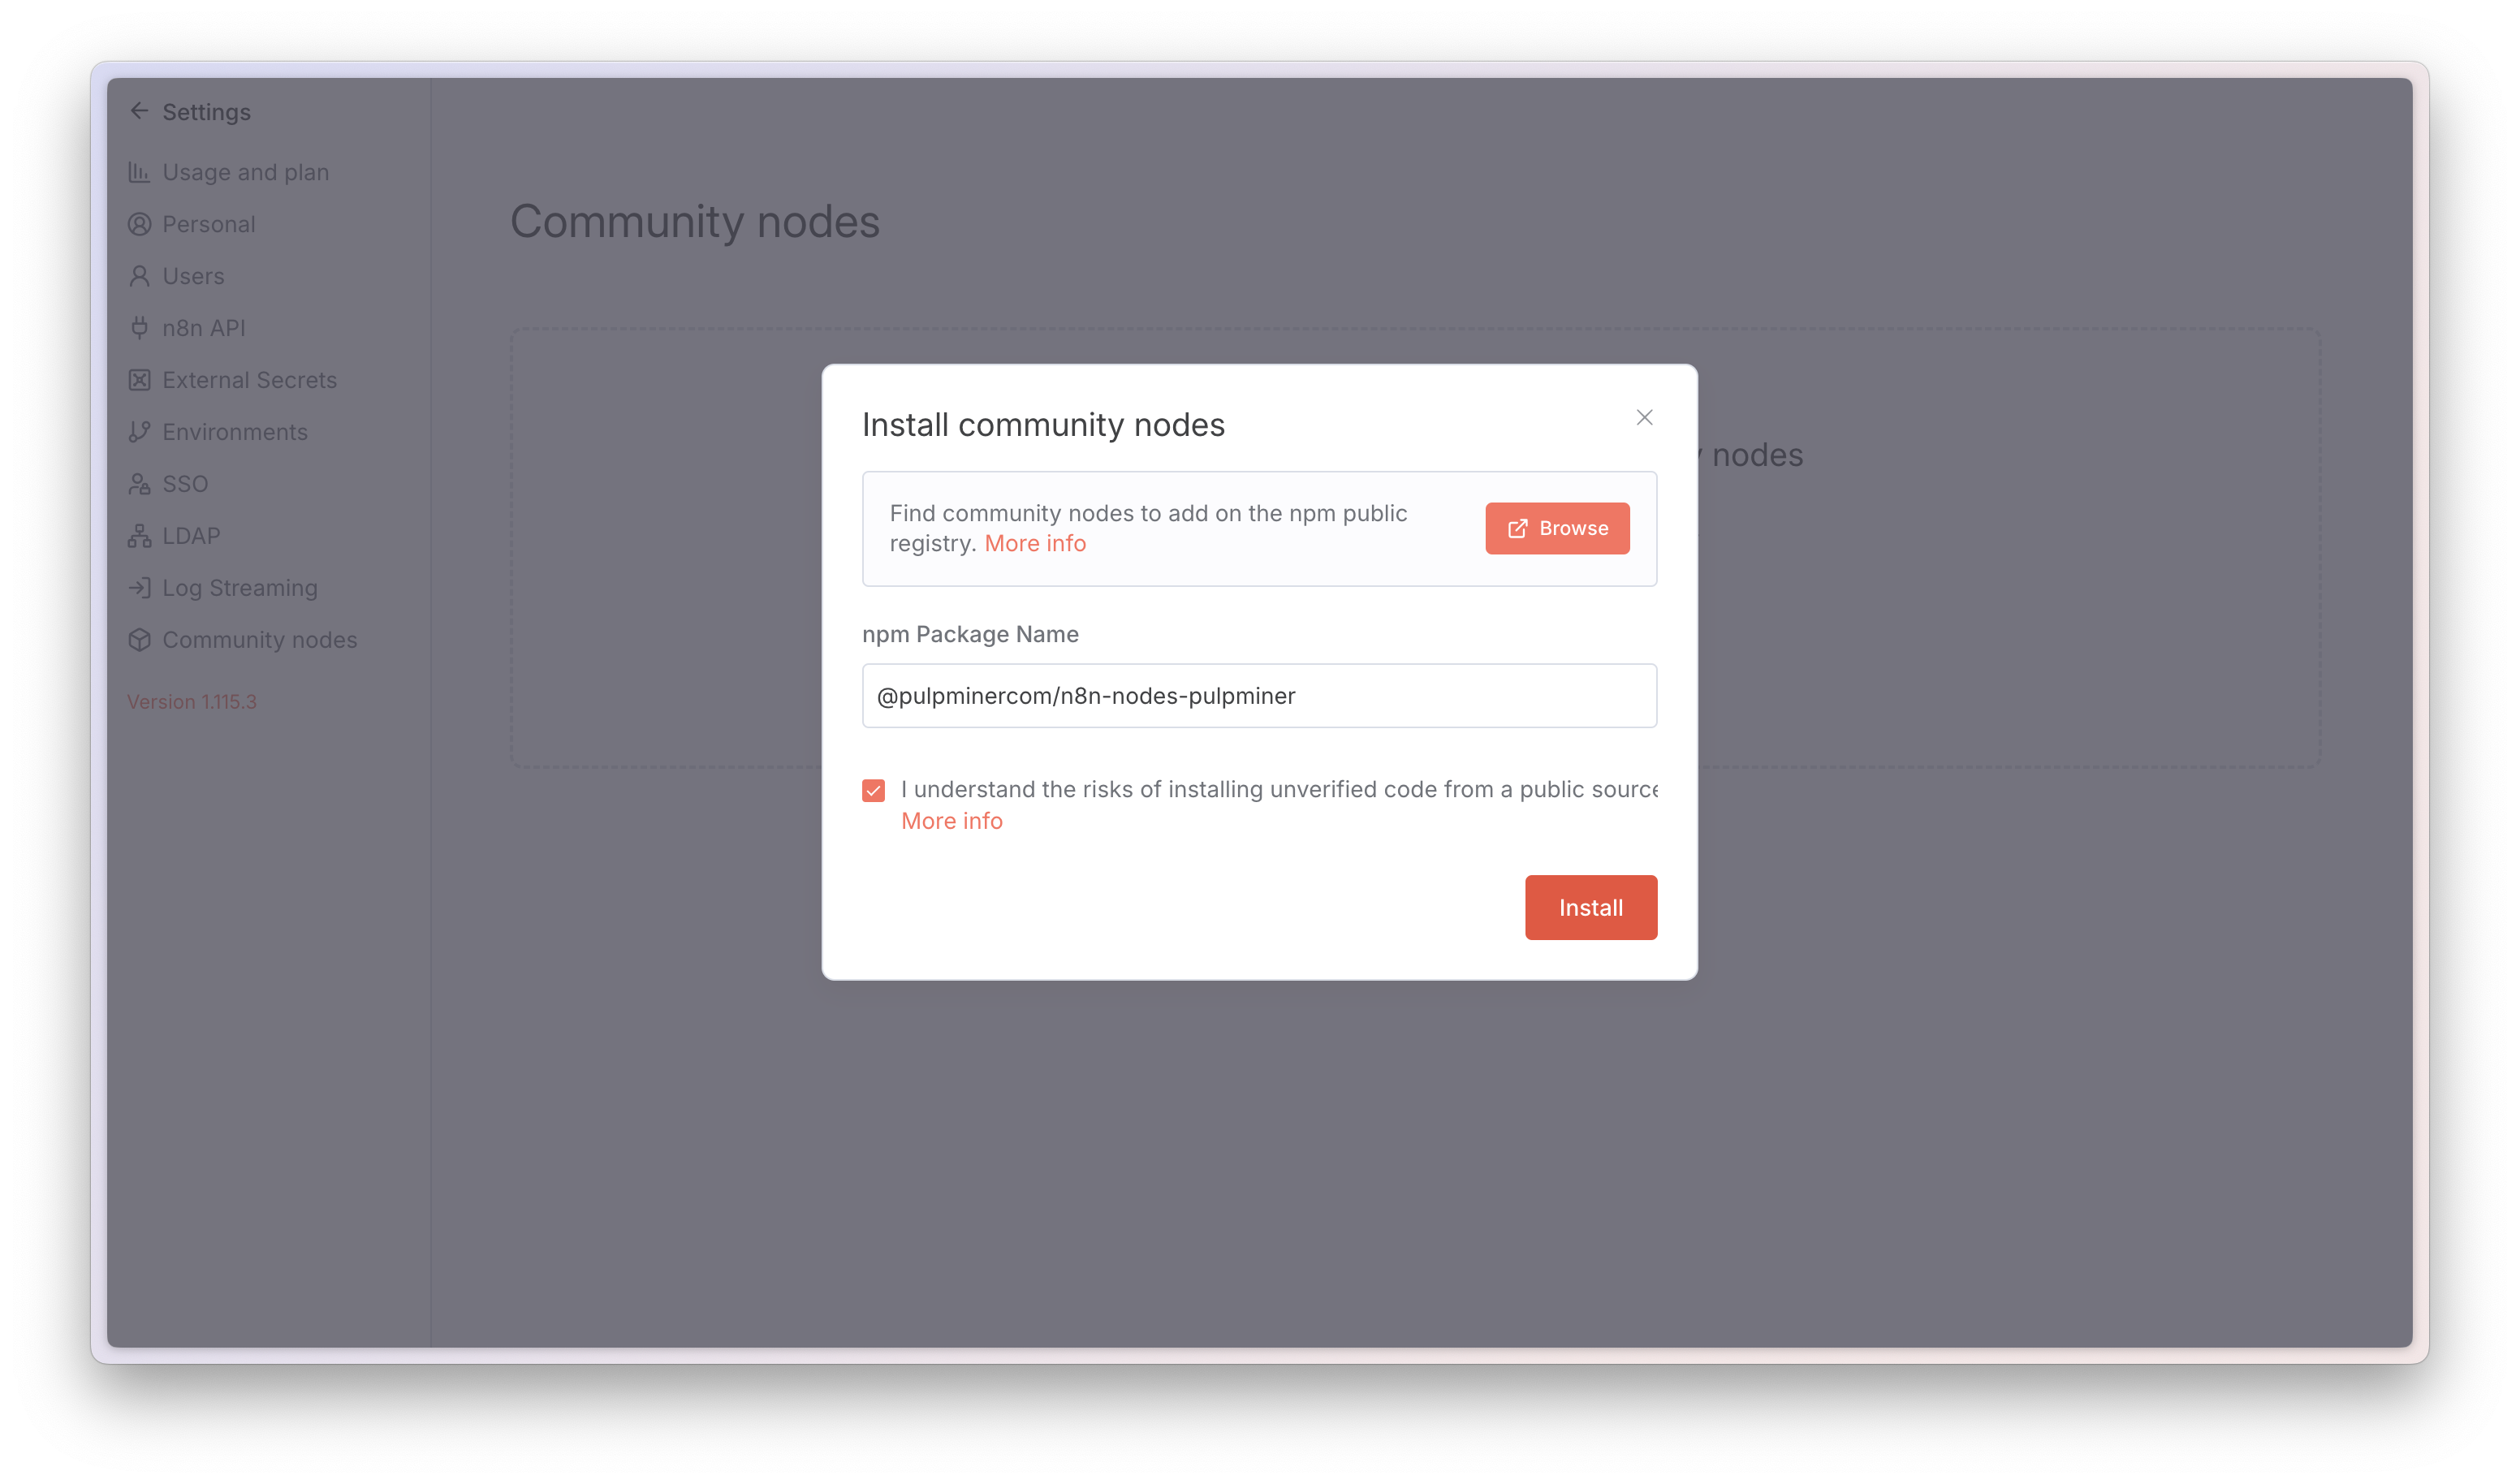
#### Step 2: Install the Node
Click **Install a community node** and enter the package name:
```
@pulpminercom/n8n-nodes-pulpminer
```
Then click **Install**.
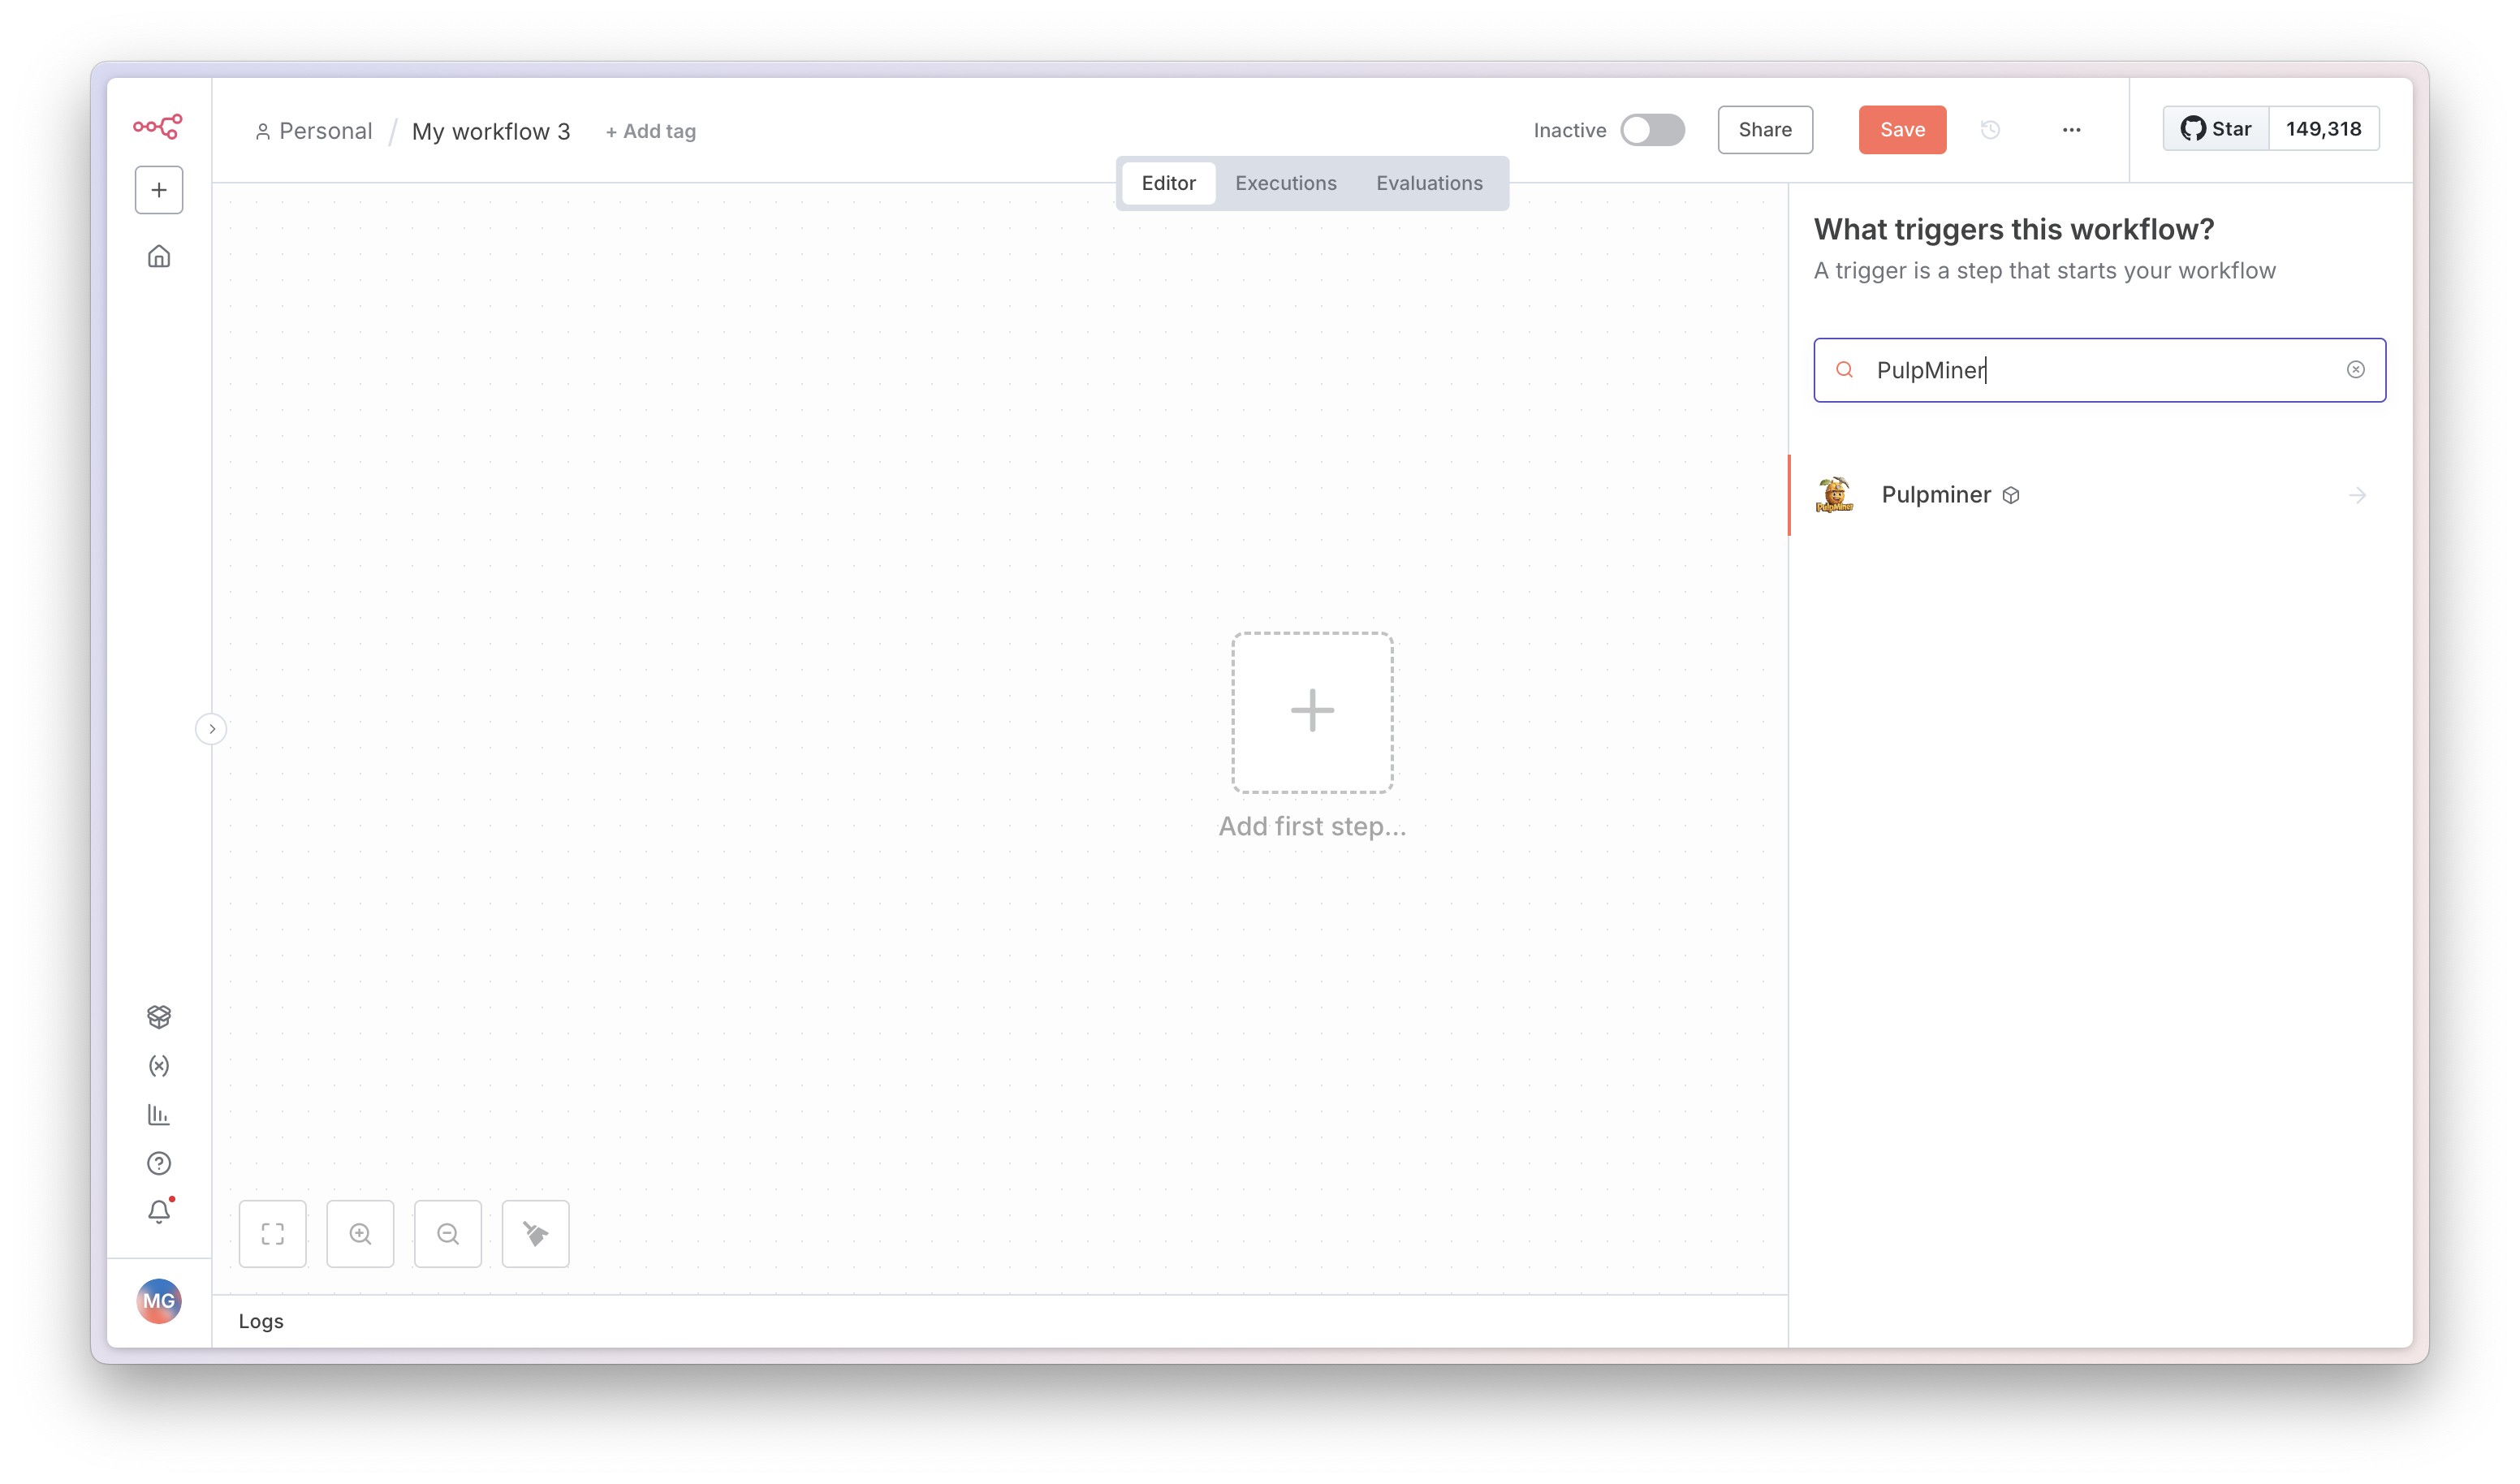
After installation, you may need to restart n8n. The node will appear in the node palette after installation.
#### Step 3: Find the Node
On your workflow canvas, search for "PulpMiner" in the node palette to find the newly installed node.
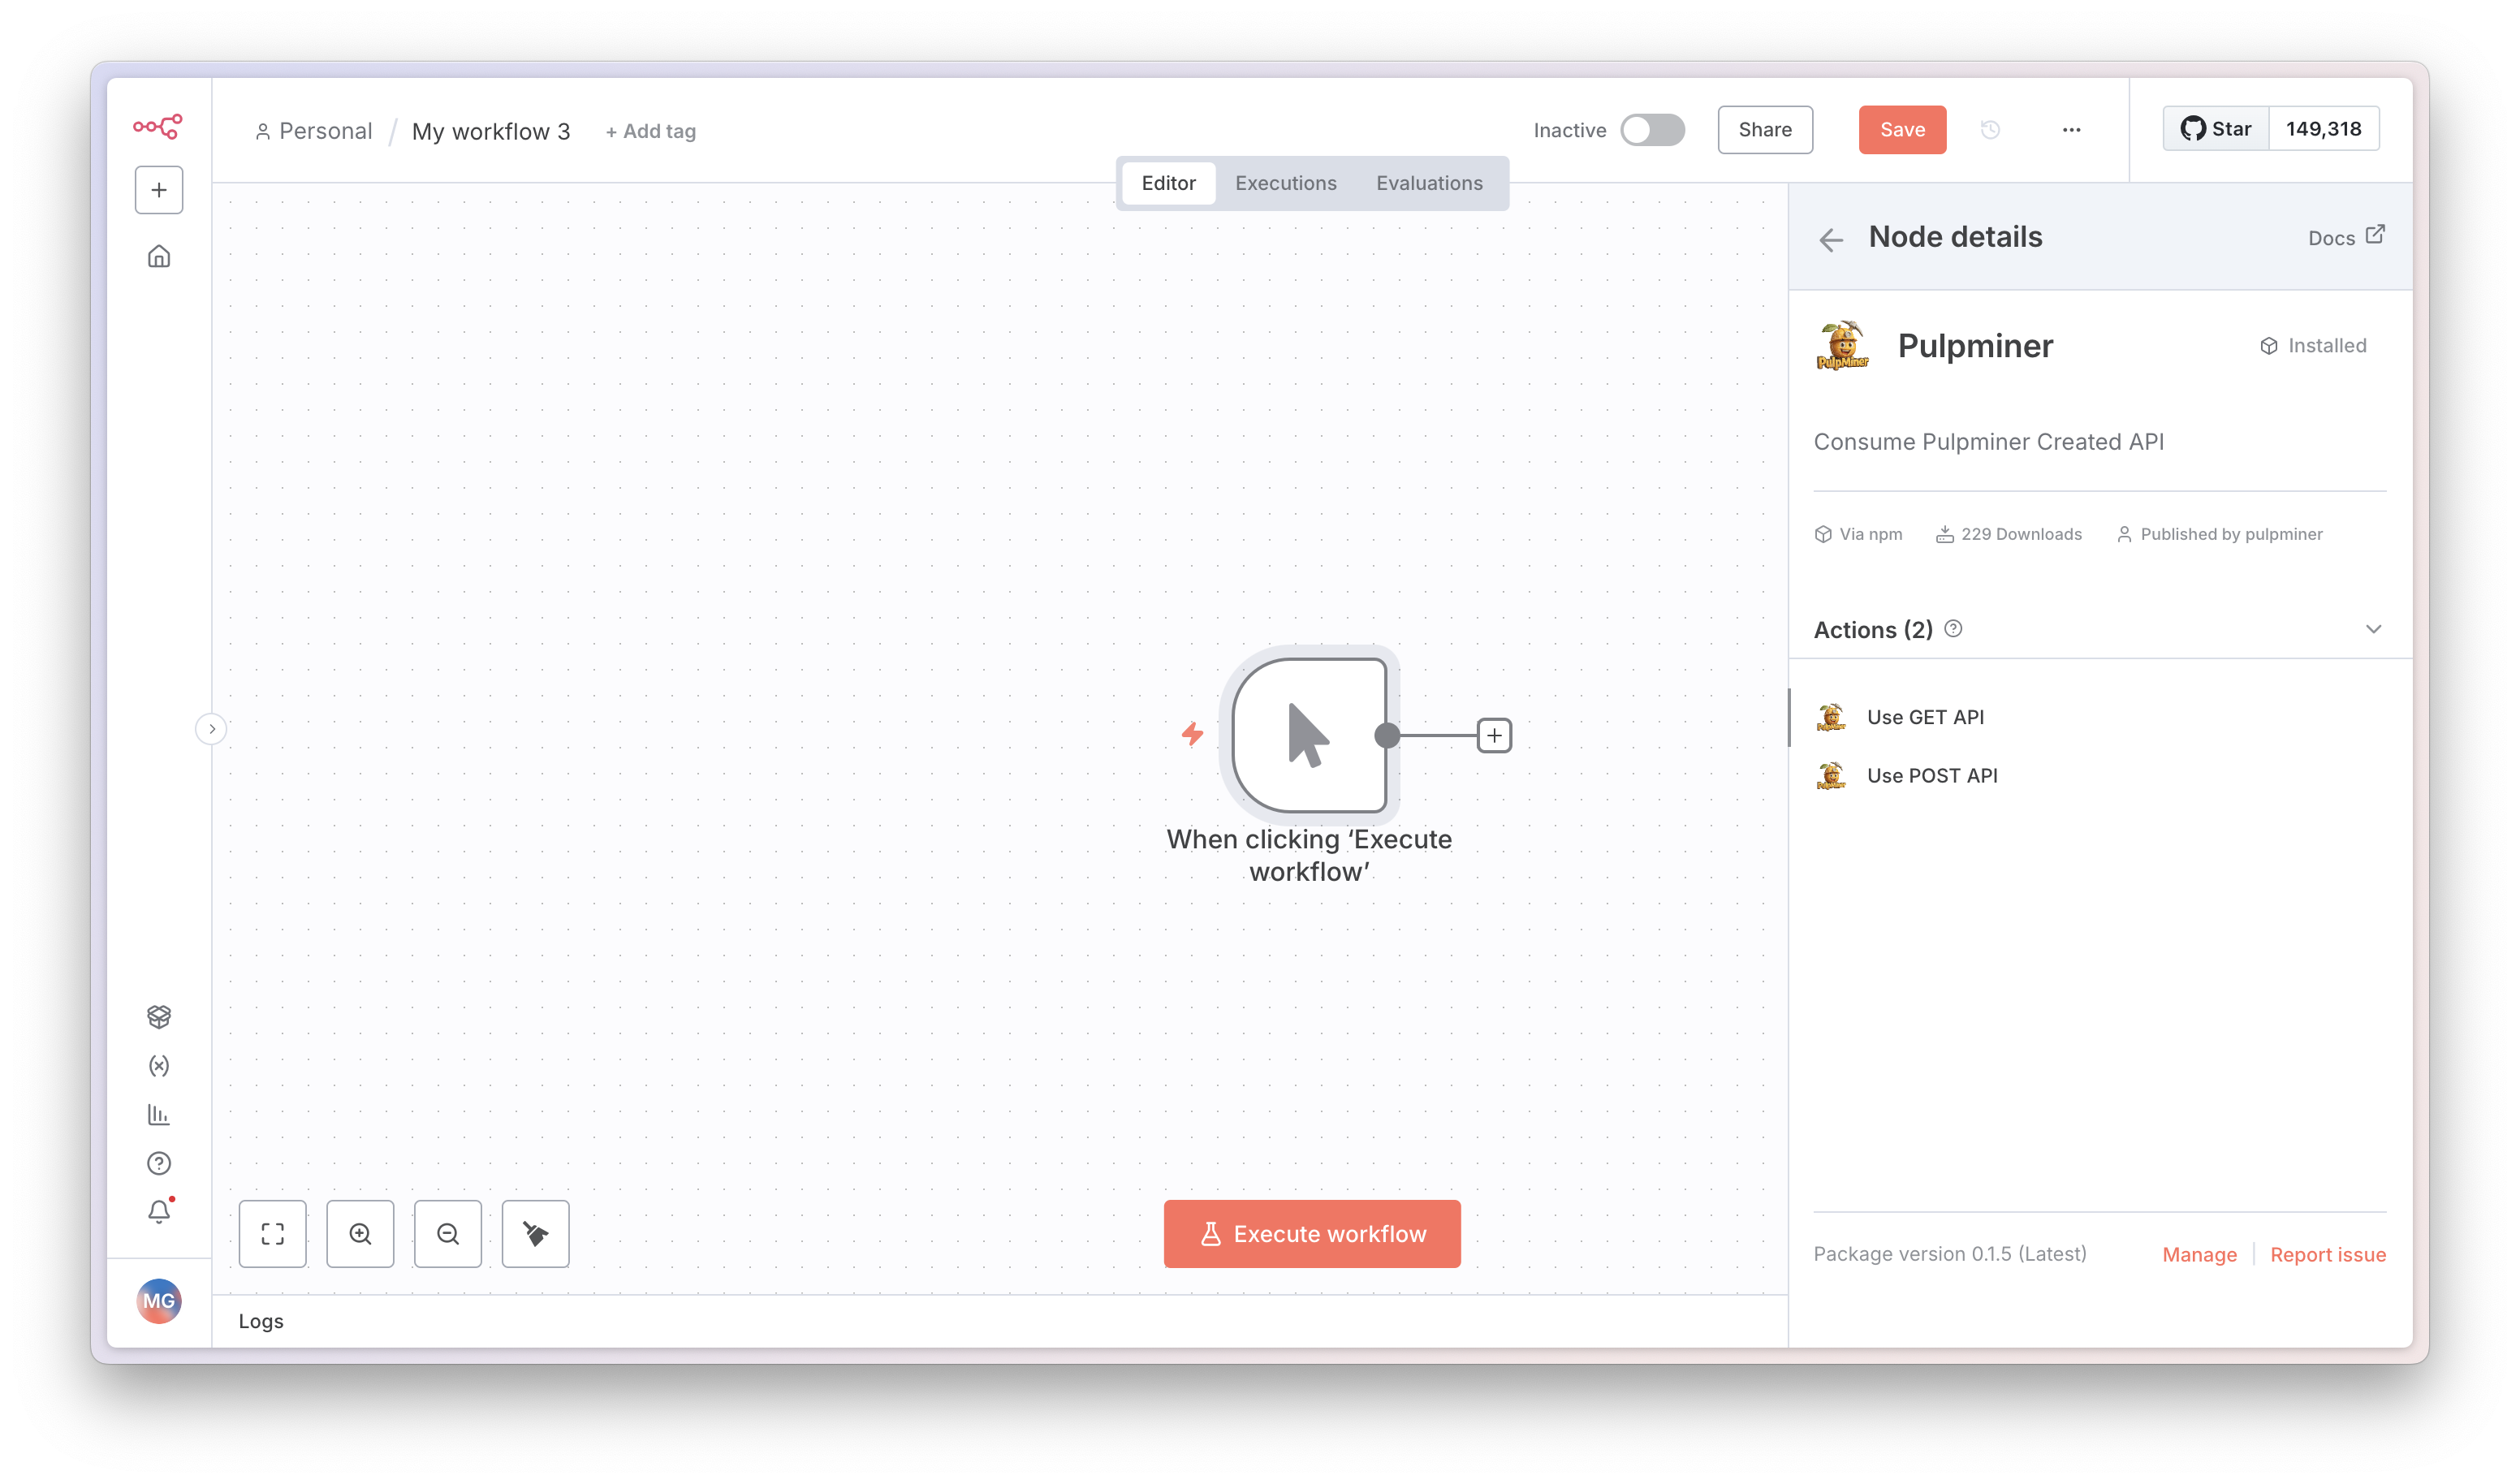
#### Step 4: Choose Operation
Select the operation type:
* **GET**: For static APIs (fixed URLs, no dynamic variables)
* **POST**: For dynamic APIs (requires variables in request body)
For this guide, we'll use GET as an example.
## Authentication
### Getting Your API Key
1. Log in to your [PulpMiner account](https://www.pulpminer.com/api/)
2. Navigate to the **Saved APIs** page
3. Copy your API key from the API Keys section
4. Keep this key secure - you'll need it for authentication
### Setting Up Credentials in n8n
#### Step 5: Create Credentials
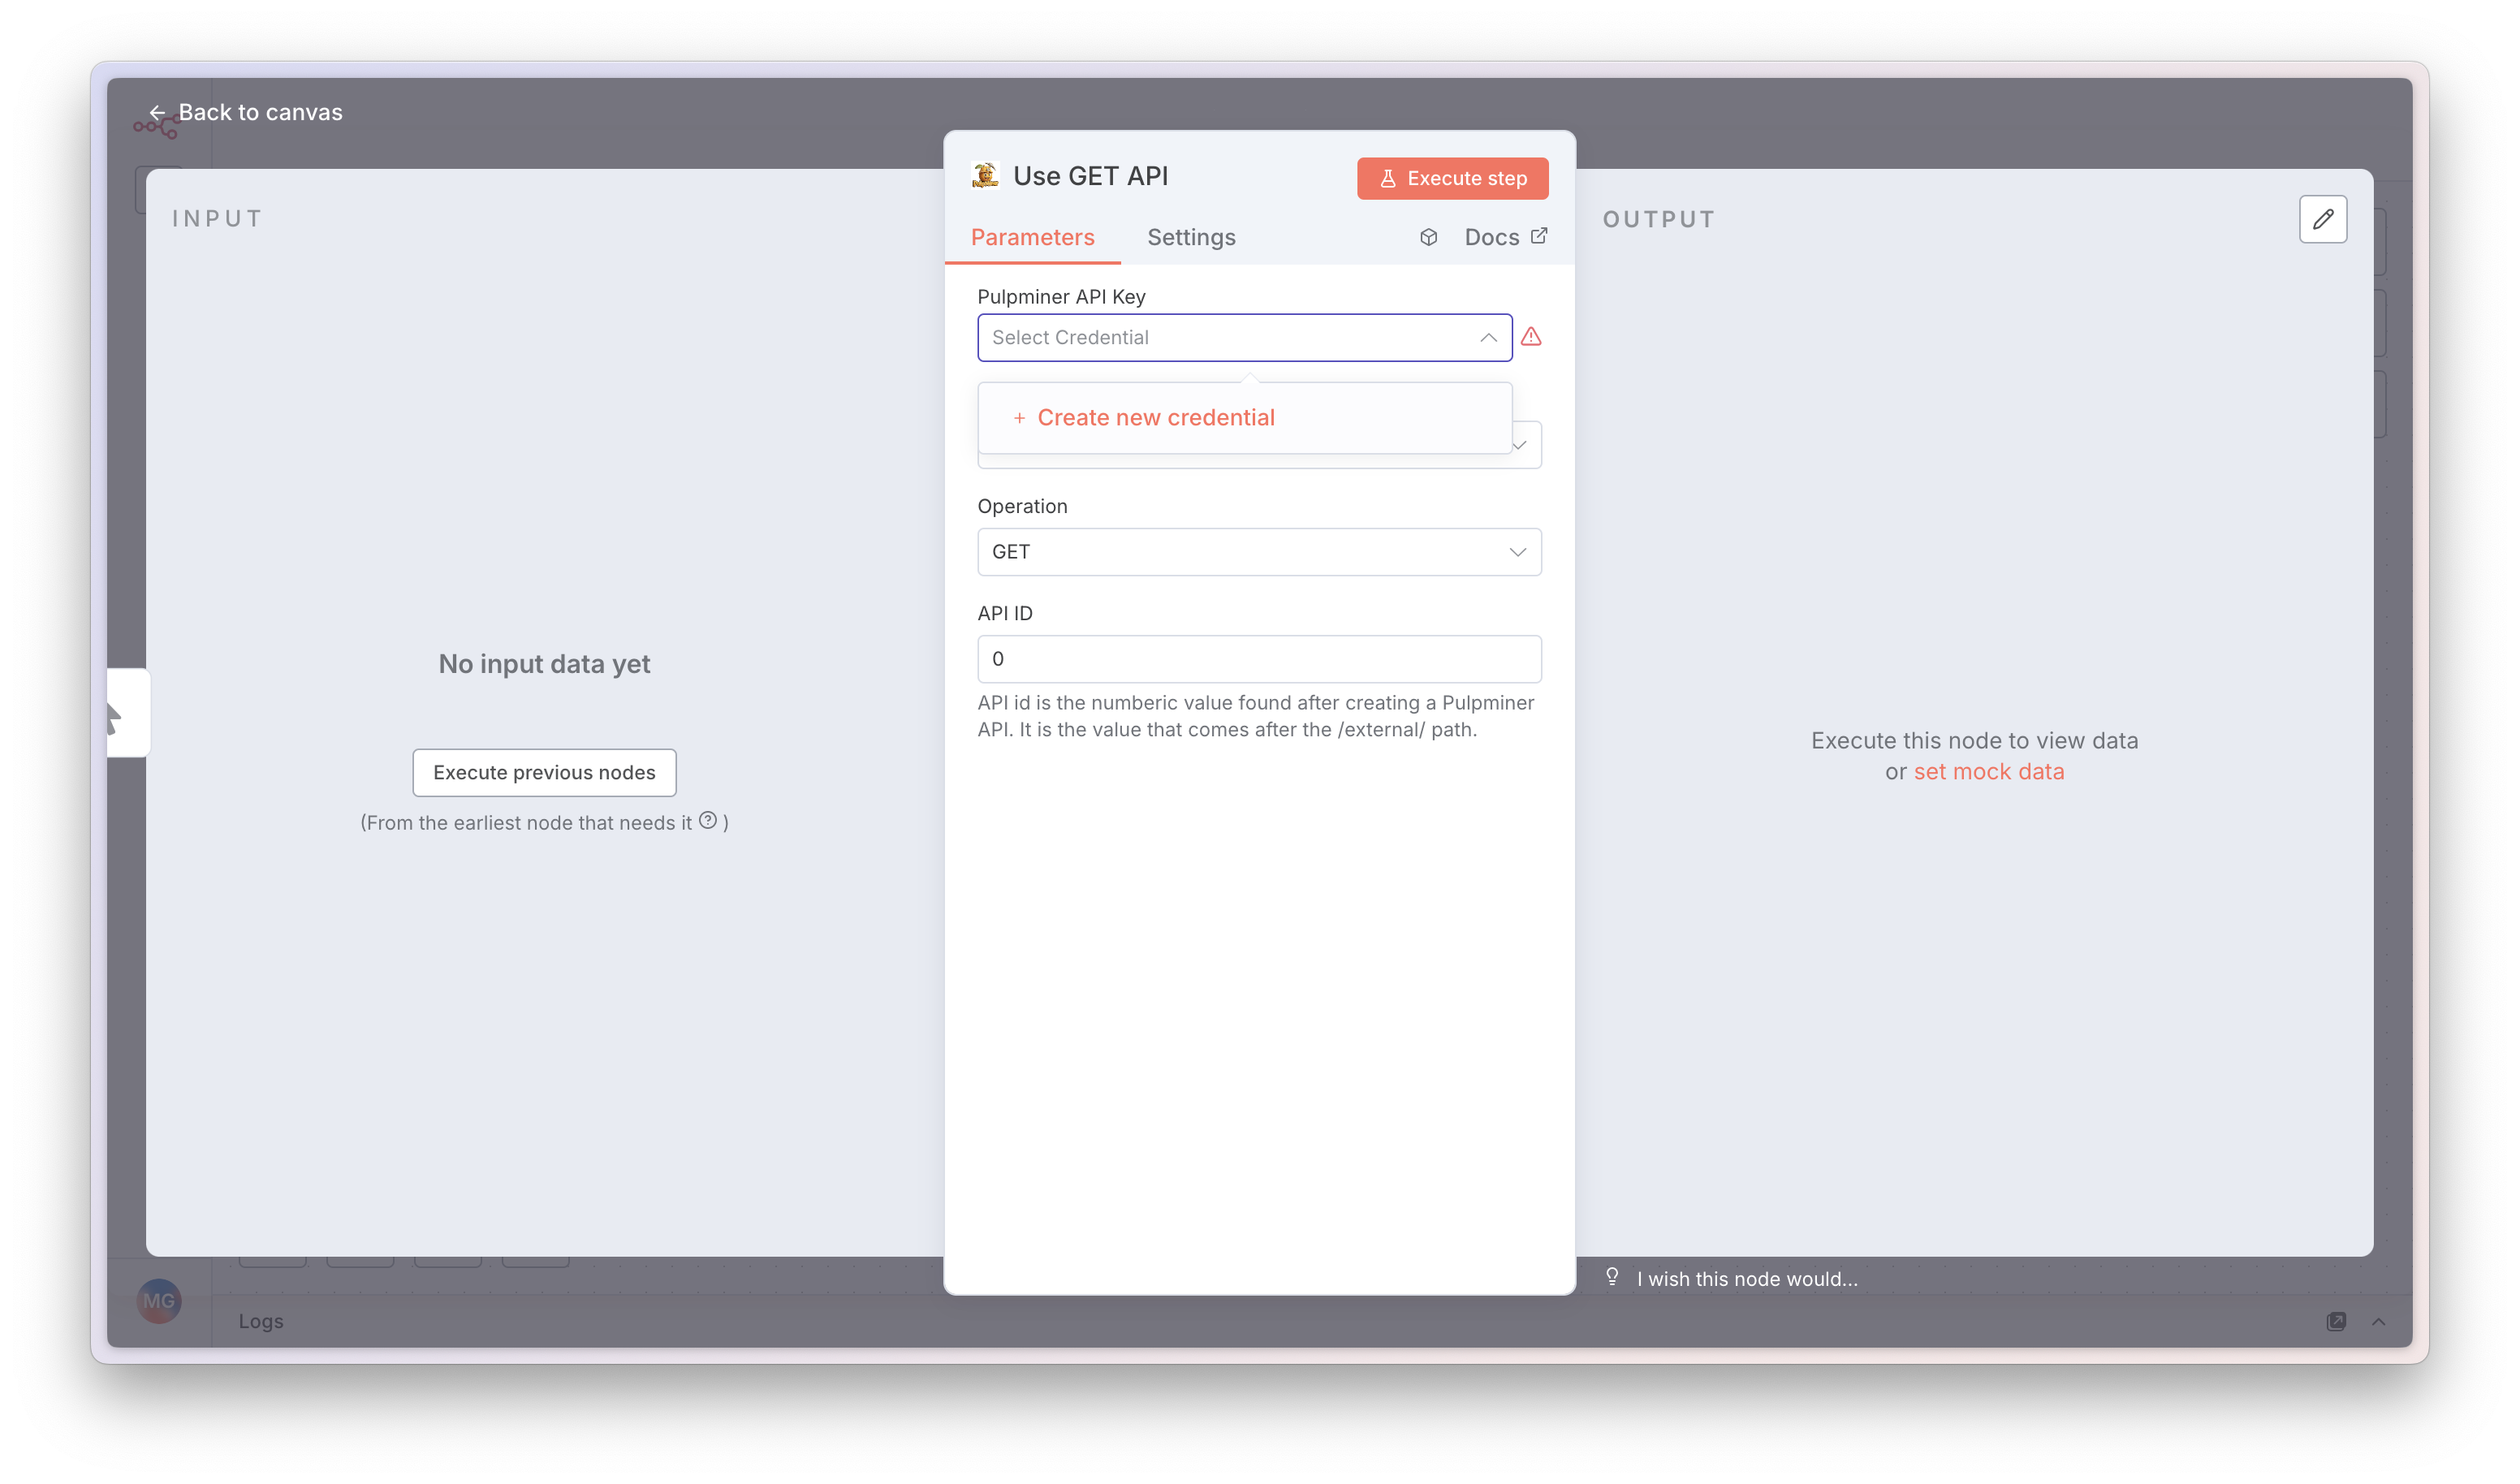
In the PulpMiner node configuration, click on the **Credentials** field and select **Create New**. Use the API key you copied from your PulpMiner Saved APIs page.
#### Step 6: Save and Verify
Enter your API key, save the credentials, and verify they're working correctly.
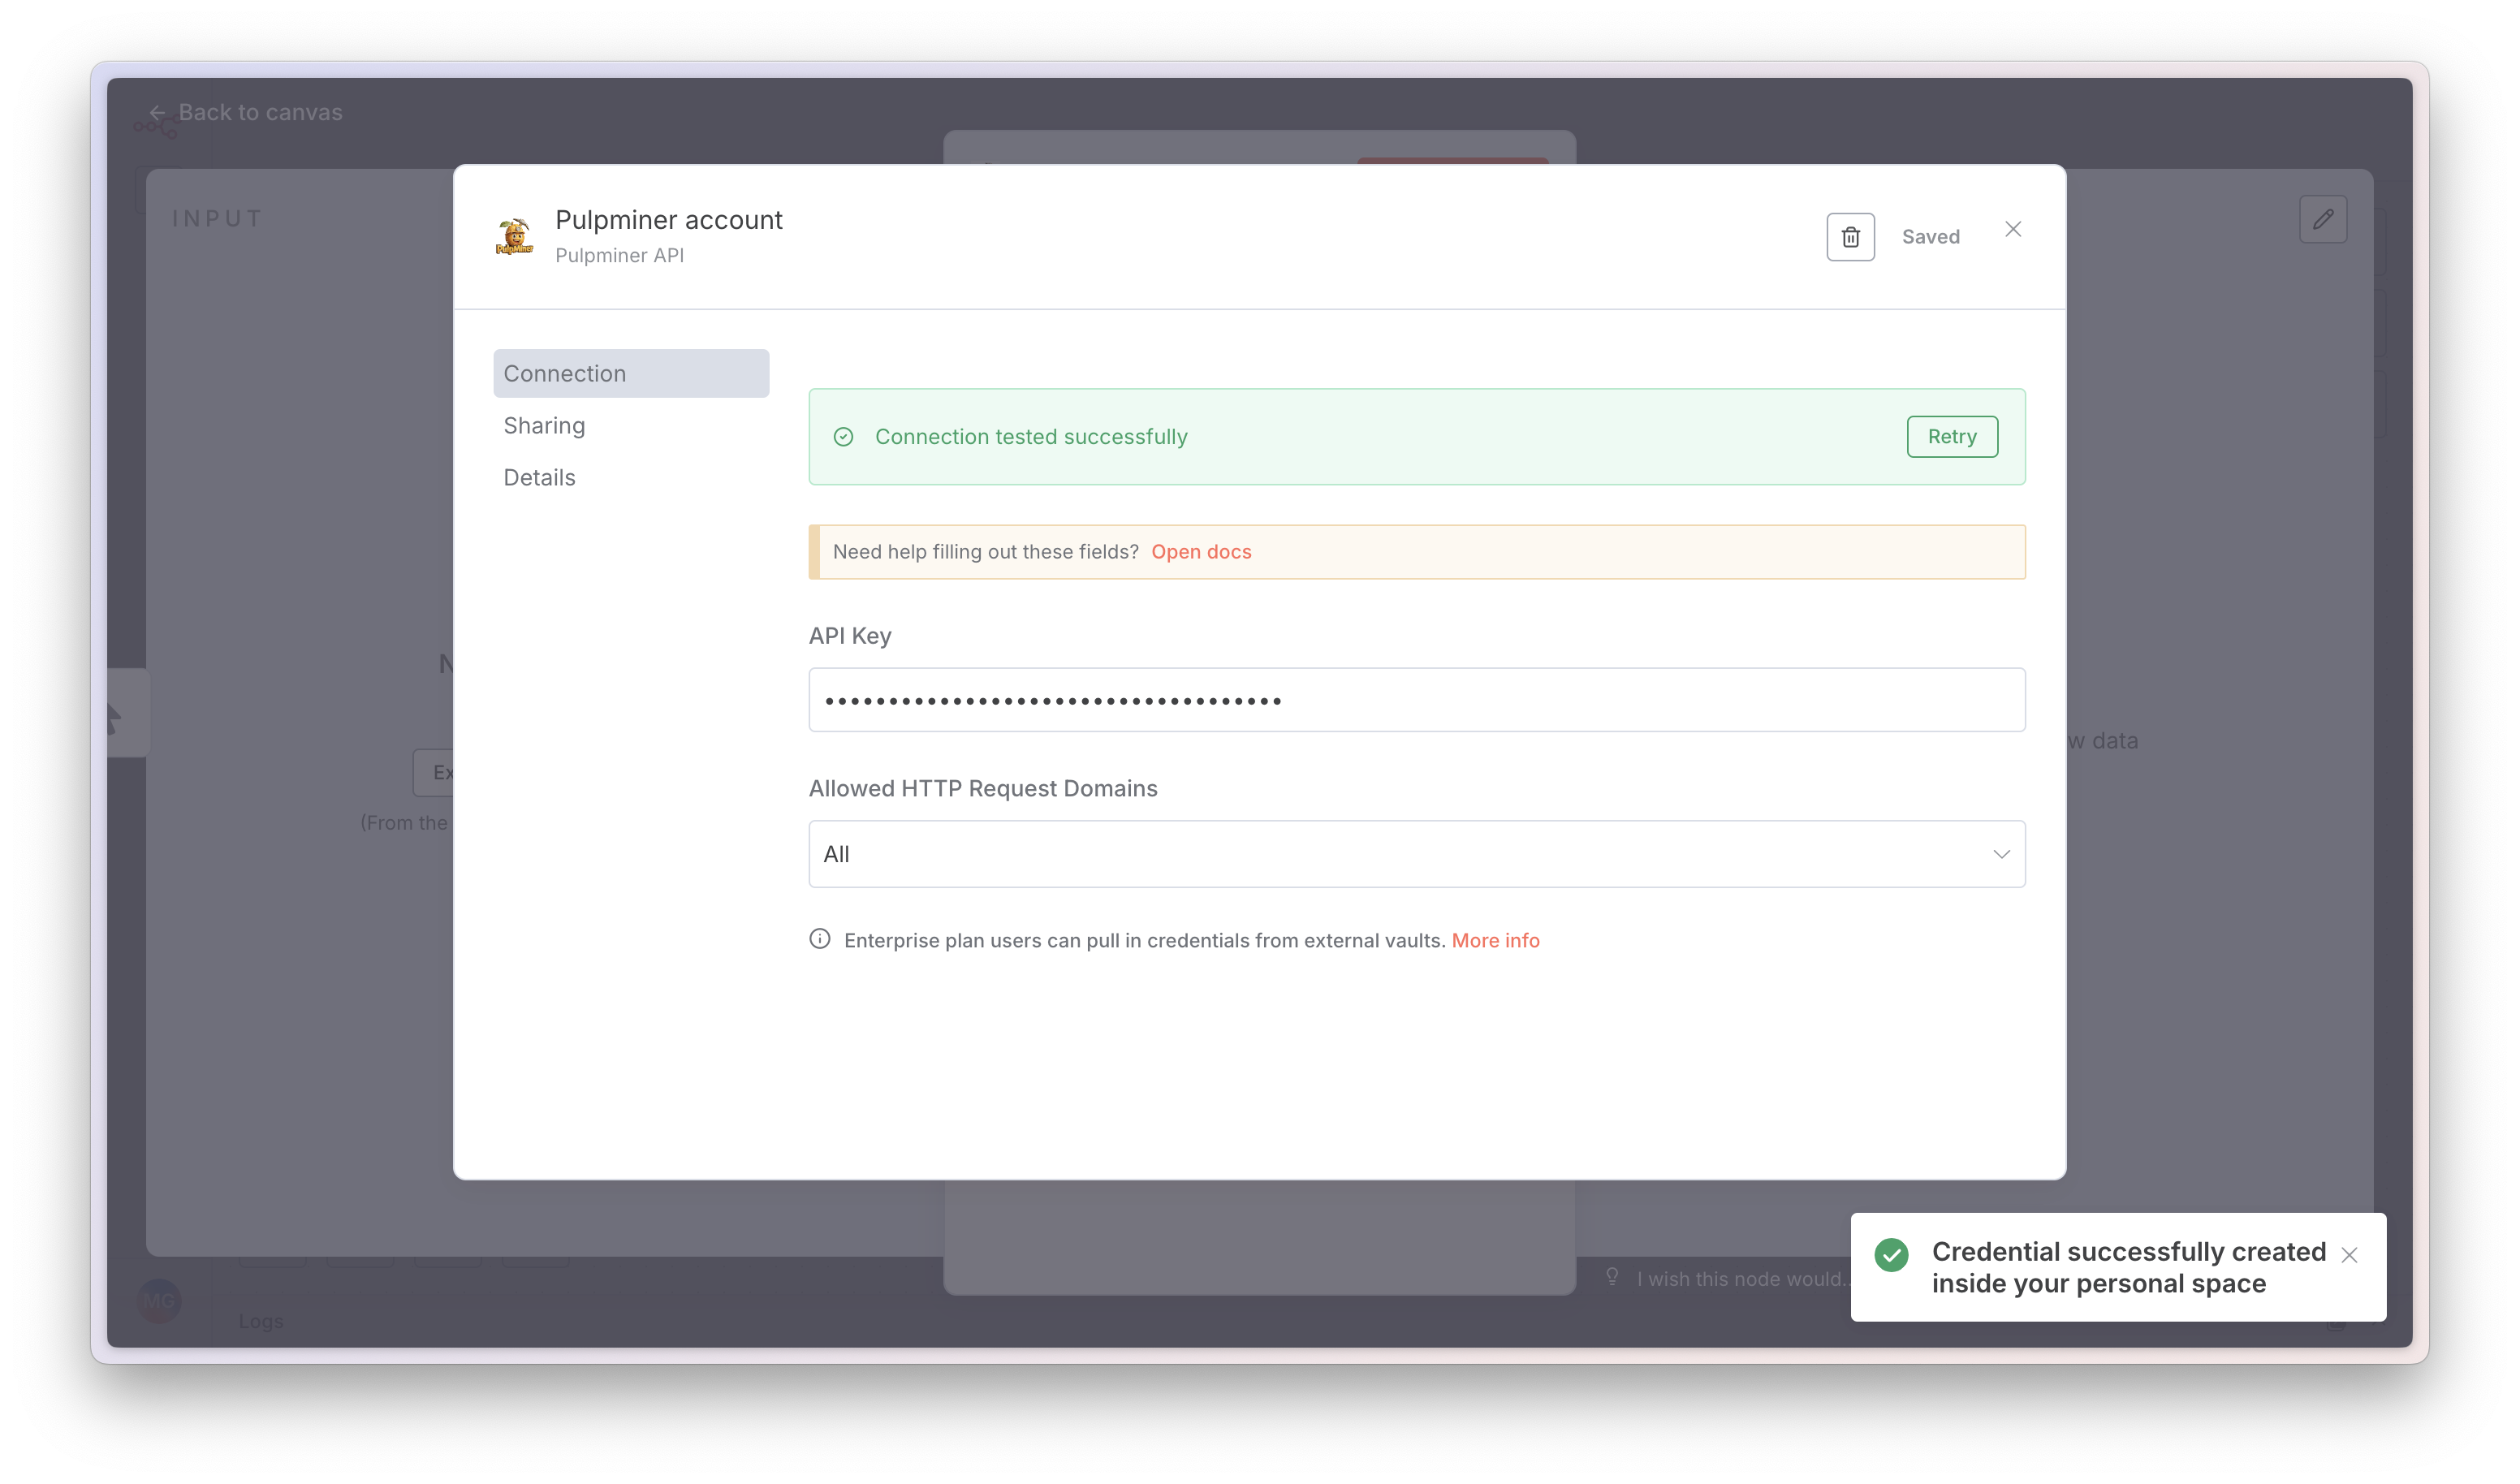
Your API key is sensitive information. Make sure to keep it secure and never share it publicly.
## Node Configuration
### Basic Setup
After installing the node and setting up credentials, configure the node:
1. **Add the Node**: Drag the PulpMiner node from the node palette into your workflow
2. **Configure Credentials**: Select the credentials you created in Step 5
3. **Set Resource**: Choose "API" (currently the only available resource)
4. **Select Operation**: Choose between GET or POST (as shown in Step 4)
5. **Enter API ID**: Input the numeric ID of your saved PulpMiner API
### Finding Your API ID
The API ID is the numeric identifier assigned to each API endpoint you create in PulpMiner. You can find it:
* In your PulpMiner dashboard after saving an API
* In the API endpoint URL: `https://api.pulpminer.com/external/{api_id}`
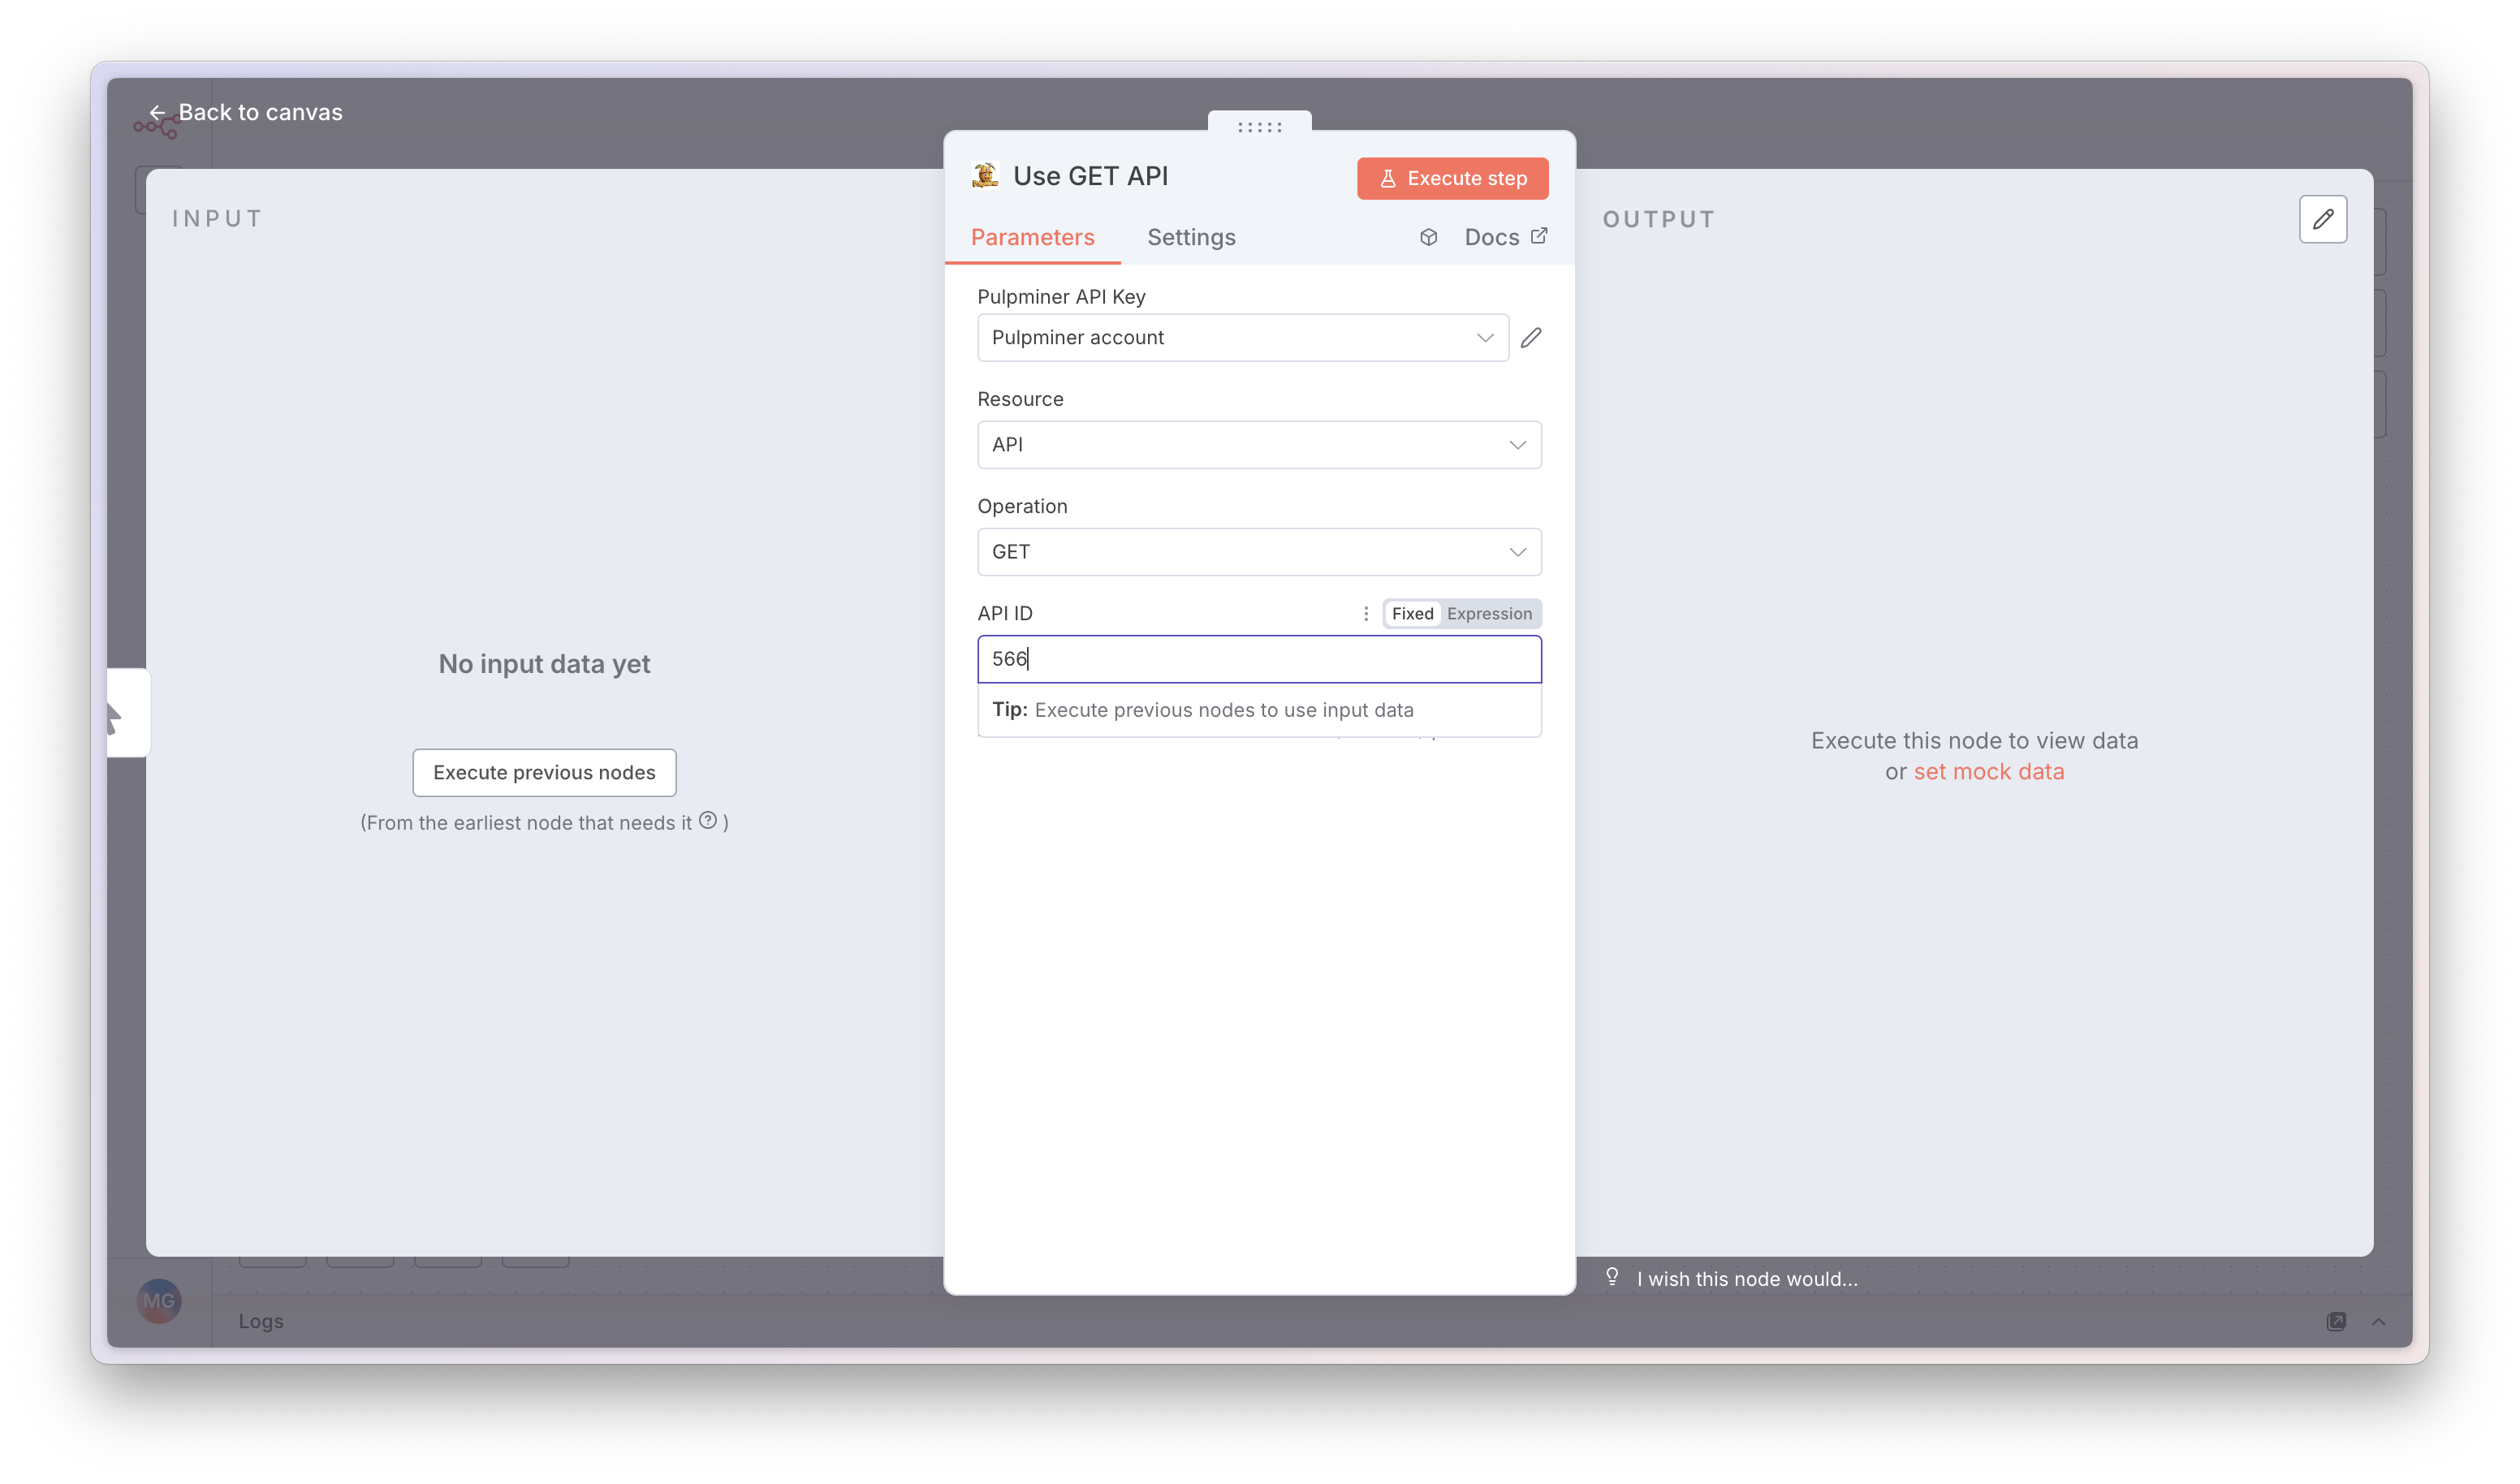
* For example, if your endpoint is `https://api.pulpminer.com/external/566`, your API ID is `566`
#### Step 7: Enter API ID
Enter the numeric API ID from your endpoint URL. For example, if your endpoint is `api.pulpminer.com/external/566`, enter `566` in the API ID field.
#### Step 8: Execute and View Results
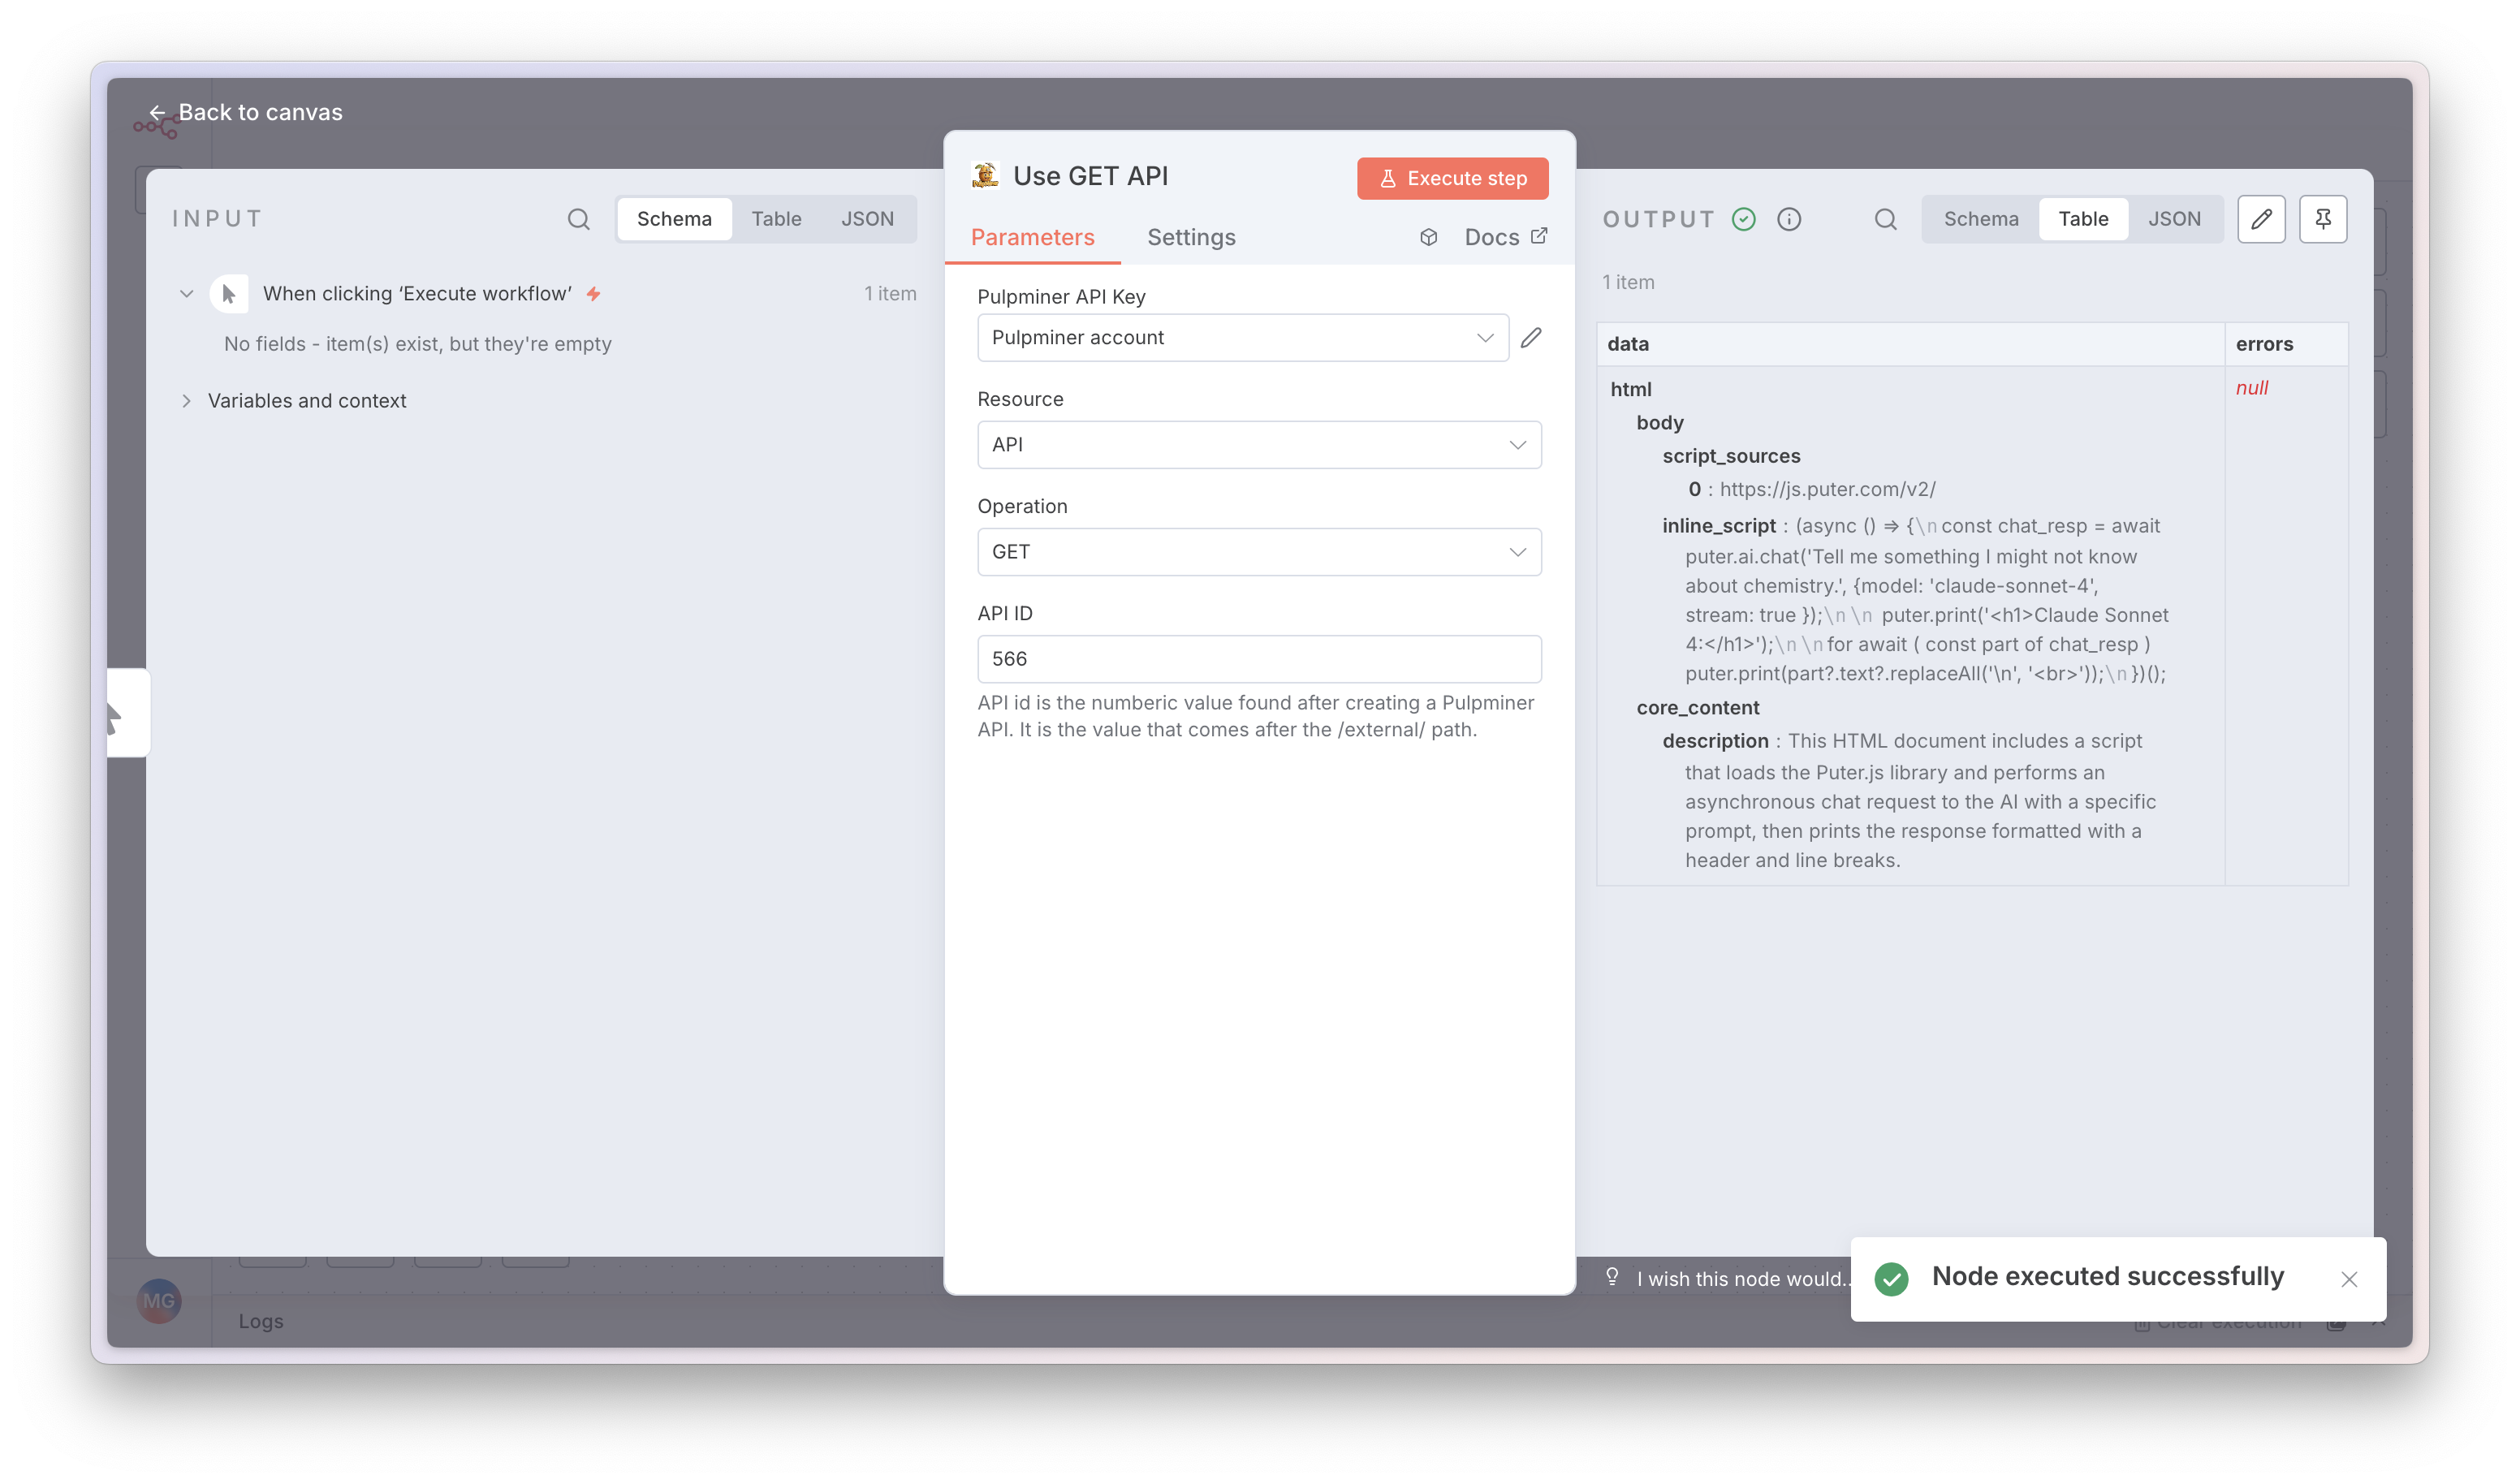
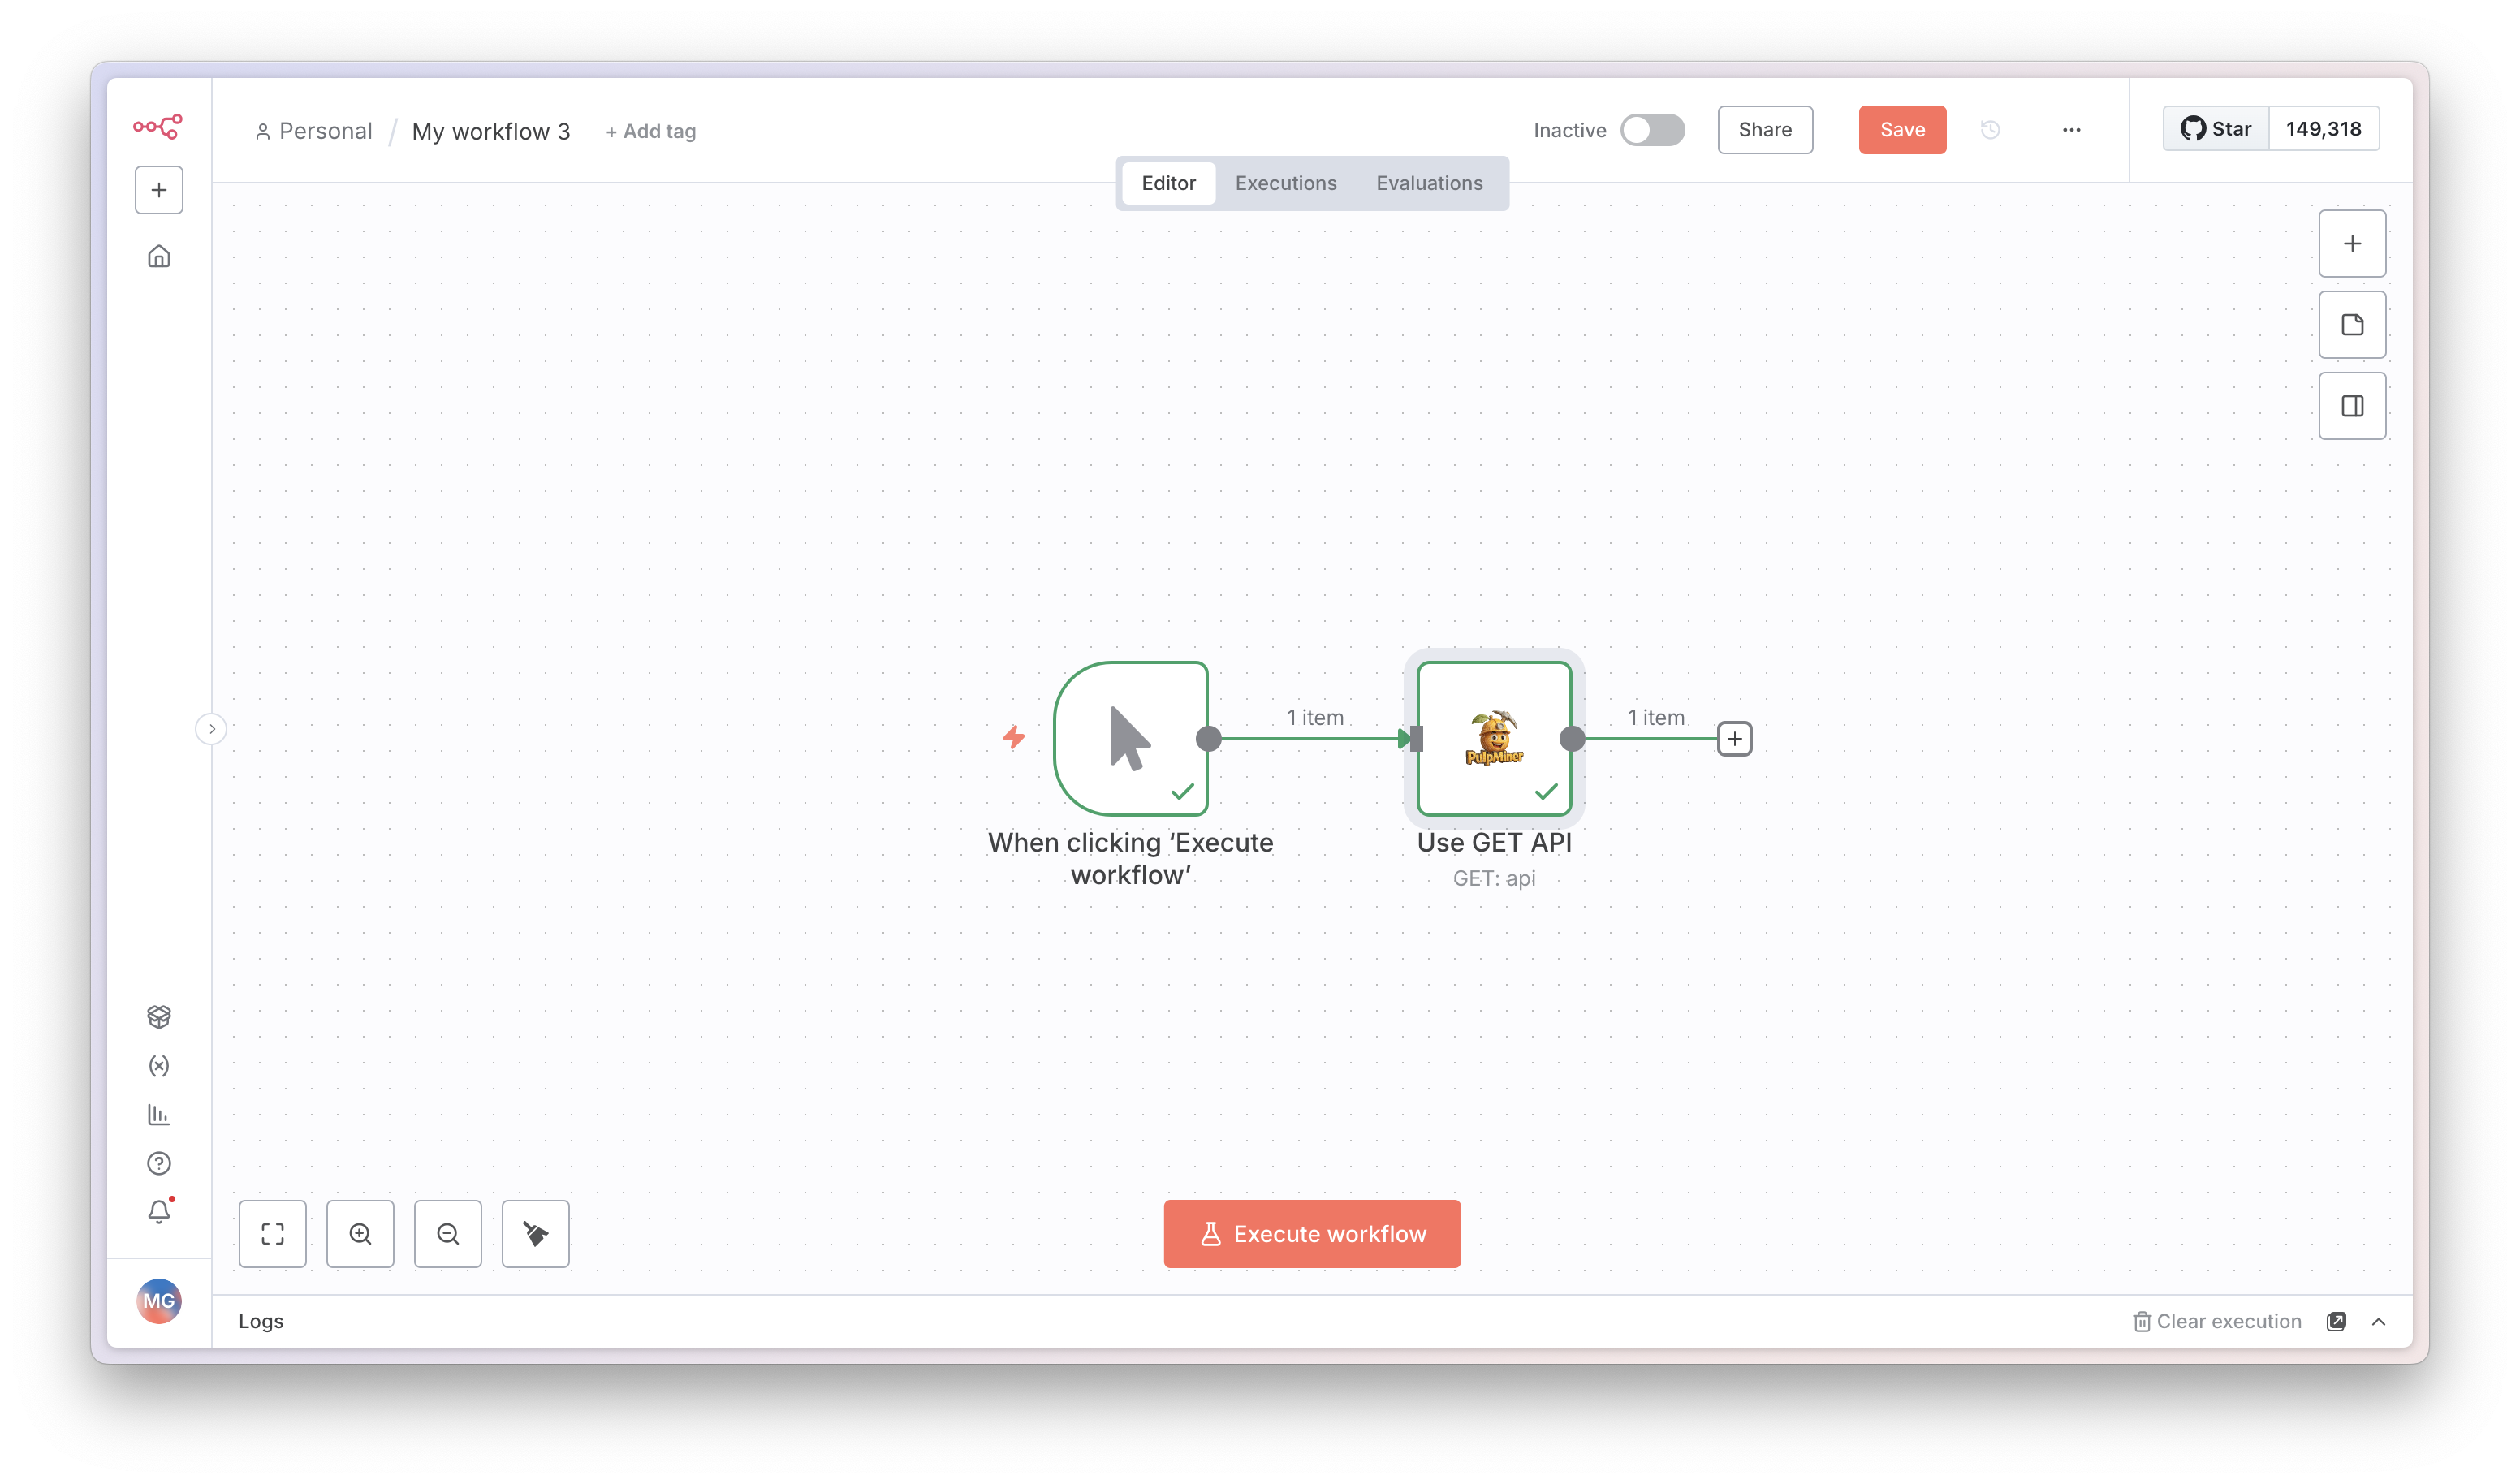
Click **Execute** to test your configuration. The JSON data will appear in the right pane, showing the structured data extracted from your webpage.
#### Step 9: Use in Workflow
Your PulpMiner node is now configured and ready to use in your workflow! You can connect it to other nodes to process the extracted data.
### Operations
#### GET Operation
Use GET for **static websites** that don't require dynamic variables:
1. Select **GET** as the operation
2. Enter your **API ID**
3. The node will make a GET request to your PulpMiner endpoint
4. Returns structured JSON data from the webpage
**Use Cases:**
* Extracting data from fixed URLs
* Scraping static content pages
* Fetching data that doesn't change based on parameters
#### POST Operation
Use POST for **dynamic websites** that require variables in the request body:
1. Select **POST** as the operation
2. Enter your **API ID**
3. Provide the **POST Request Body** in JSON format
4. Include all required dynamic variables as defined in your PulpMiner API configuration
**Example POST Request Body:**
```json theme={null}
{
"productId": "12345",
"category": "electronics",
"page": "1"
}
```
**Use Cases:**
* Product pages with variable IDs
* Search results with dynamic parameters
* Category listings with filters
* User profiles with different usernames
## Use Cases
PulpMiner with n8n is perfect for automating various data collection tasks:
Track competitor prices and get alerts in Slack when prices drop. Perfect for procurement automation.
**Example**: Monitor 100+ products automatically every hour
Collect news articles, blog posts, and updates from multiple sources into your content database.
**Example**: Build your own news feed from preferred sources
Extract contact info from directory sites, company listings, and social profiles for your CRM.
**Example**: Qualify leads from LinkedIn, industry directories
Track product launches, feature updates, and market trends from competitor websites.
**Example**: Stay ahead of competitor product releases
Monitor property listings, prices, and availability. Send new listings to buyers automatically.
**Example**: Get instant Slack notifications for new properties
Watch for new courses, enrollment dates, and price changes on learning platforms.
**Example**: Never miss enrollment deadlines
## Workflow Examples
### Example 1: Daily News Aggregation
**Scenario**: Extract news headlines from a website every day and send them via email.
**Workflow:**
1. **Schedule Trigger**: Set to run daily at 9 AM
2. **PulpMiner Node**:
* Operation: GET
* API ID: Your news website API ID
3. **Code Node**: Process the JSON data to extract headlines
4. **Email Node**: Send formatted news summary
### Example 2: Product Price Monitoring
**Scenario**: Monitor product prices from an e-commerce site and alert when prices drop.
**Workflow:**
1. **Schedule Trigger**: Run every hour
2. **PulpMiner Node**:
* Operation: POST
* API ID: Your product API ID
* Request Body: `{"productId": "12345"}`
3. **IF Node**: Check if price is below threshold
4. **Slack/Email Node**: Send alert if condition is met
### Example 3: Multi-Source Data Aggregation
**Scenario**: Collect data from multiple websites and combine into a single dataset.
**Workflow:**
1. **Manual Trigger** or **Webhook**
2. **Multiple PulpMiner Nodes**: Each fetching from different sources
3. **Merge Node**: Combine all data
4. **Database Node**: Store aggregated results
### Example 4: Dynamic Content Extraction
**Scenario**: Extract user-specific content based on input from a webhook.
**Workflow:**
1. **Webhook Trigger**: Receives user ID
2. **PulpMiner Node**:
* Operation: POST
* API ID: Your dynamic API ID
* Request Body: Use expression `{{ $json.userId }}` to pass webhook data
3. **Process Data**: Transform extracted data
4. **Return Response**: Send data back to webhook caller
## Using Expressions
n8n expressions allow you to dynamically pass data between nodes. Here are some useful patterns:
### Passing Data from Previous Nodes
**In POST Request Body:**
```json theme={null}
{
"productId": "{{ $json.productId }}",
"category": "{{ $json.category }}"
}
```
**Using Item Index:**
```json theme={null}
{
"searchTerm": "{{ $json.items[0].searchTerm }}"
}
```
### Using Variables
You can use n8n variables in your API ID or request body:
```json theme={null}
{
"userId": "{{ $vars.userId }}"
}
```
## Error Handling
### Common Errors
1. **Authentication Error**
* **Cause**: Invalid or missing API key
* **Solution**: Verify your API key in credentials and ensure it's active
2. **Invalid API ID**
* **Cause**: API ID doesn't exist or is incorrect
* **Solution**: Check your PulpMiner dashboard for the correct API ID
3. **Missing Variables**
* **Cause**: POST request missing required dynamic variables
* **Solution**: Ensure all variables defined in your PulpMiner API are included in the request body
4. **Rate Limiting**
* **Cause**: Exceeding credit limits or request rate
* **Solution**: Check your credit balance and implement delays between requests
### Implementing Error Handling
Use n8n's **IF** node to check for errors:
1. After the PulpMiner node, add an **IF** node
2. Check if `{{ $json.errors }}` exists
3. Route errors to a notification node
4. Route successful responses to processing nodes
## Best Practices
### 1. Credential Management
* Rotate API keys periodically
* Never commit API keys to version control
### 2. Rate Limiting
* Implement delays between requests when processing multiple items
* Monitor your PulpMiner credit usage
* Use n8n's rate limiting features for high-volume workflows
### 3. Data Processing
* Always validate the structure of returned JSON data
* Use n8n's **Code** node for complex data transformations
* Store raw data before processing for debugging
### 4. Caching
* Enable caching in your PulpMiner API when appropriate
* Use n8n's caching features for frequently accessed data
* Balance between data freshness and performance
### 5. Monitoring
* Set up error notifications for failed workflows
* Monitor credit usage in your PulpMiner dashboard
* Log important workflow executions
## Advanced Usage
### Batch Processing
Process multiple items in a single workflow:
1. **Trigger** that provides multiple items (e.g., CSV import, database query)
2. **PulpMiner Node** processes each item automatically
3. **Process Results** for all items
### Conditional API Calls
Use different APIs based on conditions:
1. **IF Node**: Check condition
2. **Multiple PulpMiner Nodes**: Different APIs for different branches
3. **Merge Node**: Combine results
### Looping Through Data
Extract data for multiple items:
1. **Loop Over Items** node
2. **PulpMiner Node** with dynamic POST body
3. **Aggregate Results**
## Troubleshooting
### Node Not Appearing
* Ensure the node is installed correctly
* Restart n8n after installation
* Check n8n version compatibility (1.113.3+)
### Authentication Issues
* Verify API key is correct
* Check if API key is active in PulpMiner dashboard
* Ensure credentials are saved properly in n8n
### Data Not Returning
* Verify API ID is correct
* Check if the source webpage is accessible
* Review PulpMiner API status in dashboard
* Test the API directly with curl first
### Dynamic Variables Not Working
* Ensure variable names match exactly (case-sensitive)
* Verify all required variables are provided
* Check JSON format in POST request body
* Review your PulpMiner API configuration
## Quick Reference
### Package Name
```
@pulpminercom/n8n-nodes-pulpminer
```
### Installation Command
In n8n Settings → Community Nodes, enter:
```
@pulpminercom/n8n-nodes-pulpminer
```
### Minimum Requirements
* n8n version: 1.113.3 or higher
* Node.js version: 23.11+ (for n8n)
* PulpMiner account with API key
## Resources
* [n8n Documentation](https://docs.n8n.io/)
* [n8n Community Nodes Guide](https://docs.n8n.io/integrations/#community-nodes)
* [PulpMiner API Documentation](/api-reference/endpoints/external-api)
* [PulpMiner API Keys Guide](/essentials/api-keys)
* [PulpMiner Website](https://pulpminer.com)
* [GitHub Repository](https://github.com/pulpminercom/n8n-nodes-pulpminer)
## Support
If you encounter issues with the n8n integration:
1. Check the [PulpMiner API documentation](/api-reference/endpoints/external-api)
2. Review n8n workflow execution logs
3. Test your PulpMiner API directly with curl
4. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
## Next Steps
* Learn more about [PulpMiner API endpoints](/essentials/api-endpoints)
* Explore [dynamic variables](/essentials/api-endpoints#dynamic-variables)
* Check out [caching strategies](/essentials/caching)
* Review [credit management](/essentials/credits)
# Zapier Integration
Source: https://docs.pulpminer.com/integrations/zapier
Use PulpMiner APIs in your Zapier workflows for automated web scraping and data extraction
# Zapier Integration
Integrate PulpMiner with Zapier to automate web scraping and data extraction workflows. The PulpMiner Zapier app allows you to consume your saved PulpMiner APIs directly within Zapier workflows, enabling powerful automation capabilities.
## Overview
The PulpMiner Zapier integration enables you to:
* Fetch structured JSON data from websites using your saved PulpMiner APIs
* Automate data extraction workflows
* Integrate web scraping into larger automation processes
* Use both static (GET) and dynamic (POST) API endpoints
* Skip complex scraping code - let AI handle the extraction
* Get real-time or cached data based on your needs
## Why Use PulpMiner with Zapier?
Connect PulpMiner to Zapier in seconds. No custom scripts or code needed.
Automatically structure web data into clean JSON. Our AI handles complex websites with dynamic content.
Fetch fresh data from websites on every Zap execution, or use cached data for speed.
Built on Cloudflare infrastructure with 99.99% uptime. Enterprise-grade security and compliance.
Only pay for what you use. Credits never expire. No monthly subscriptions.
Extract data from e-commerce sites, news pages, directories, or any public webpage.
## Prerequisites
1. **Zapier Account**: Sign up at [zapier.com](https://zapier.com) if you haven't already
2. **PulpMiner Account**: Sign up at [pulpminer.com](https://pulpminer.com) if you haven't already
3. **PulpMiner API**: Create and save at least one API endpoint in your [PulpMiner dashboard](https://www.pulpminer.com/api/)
4. **API Key**: Get your API key from the PulpMiner "Saved APIs" page
## Getting Started
### Step 1: Create Your API in PulpMiner
Before connecting to Zapier, you need to create a PulpMiner API:
1. Go to [PulpMiner API Generation](https://www.pulpminer.com/api/generate)
2. Enter the webpage URL you want to scrape
3. Select a scraper and configure your settings
4. Generate and customize the JSON structure
5. Save your API and note the API ID
The API ID is the numeric value found after creating a PulpMiner API. It's the value that comes after the `/external/` path in your API URL.
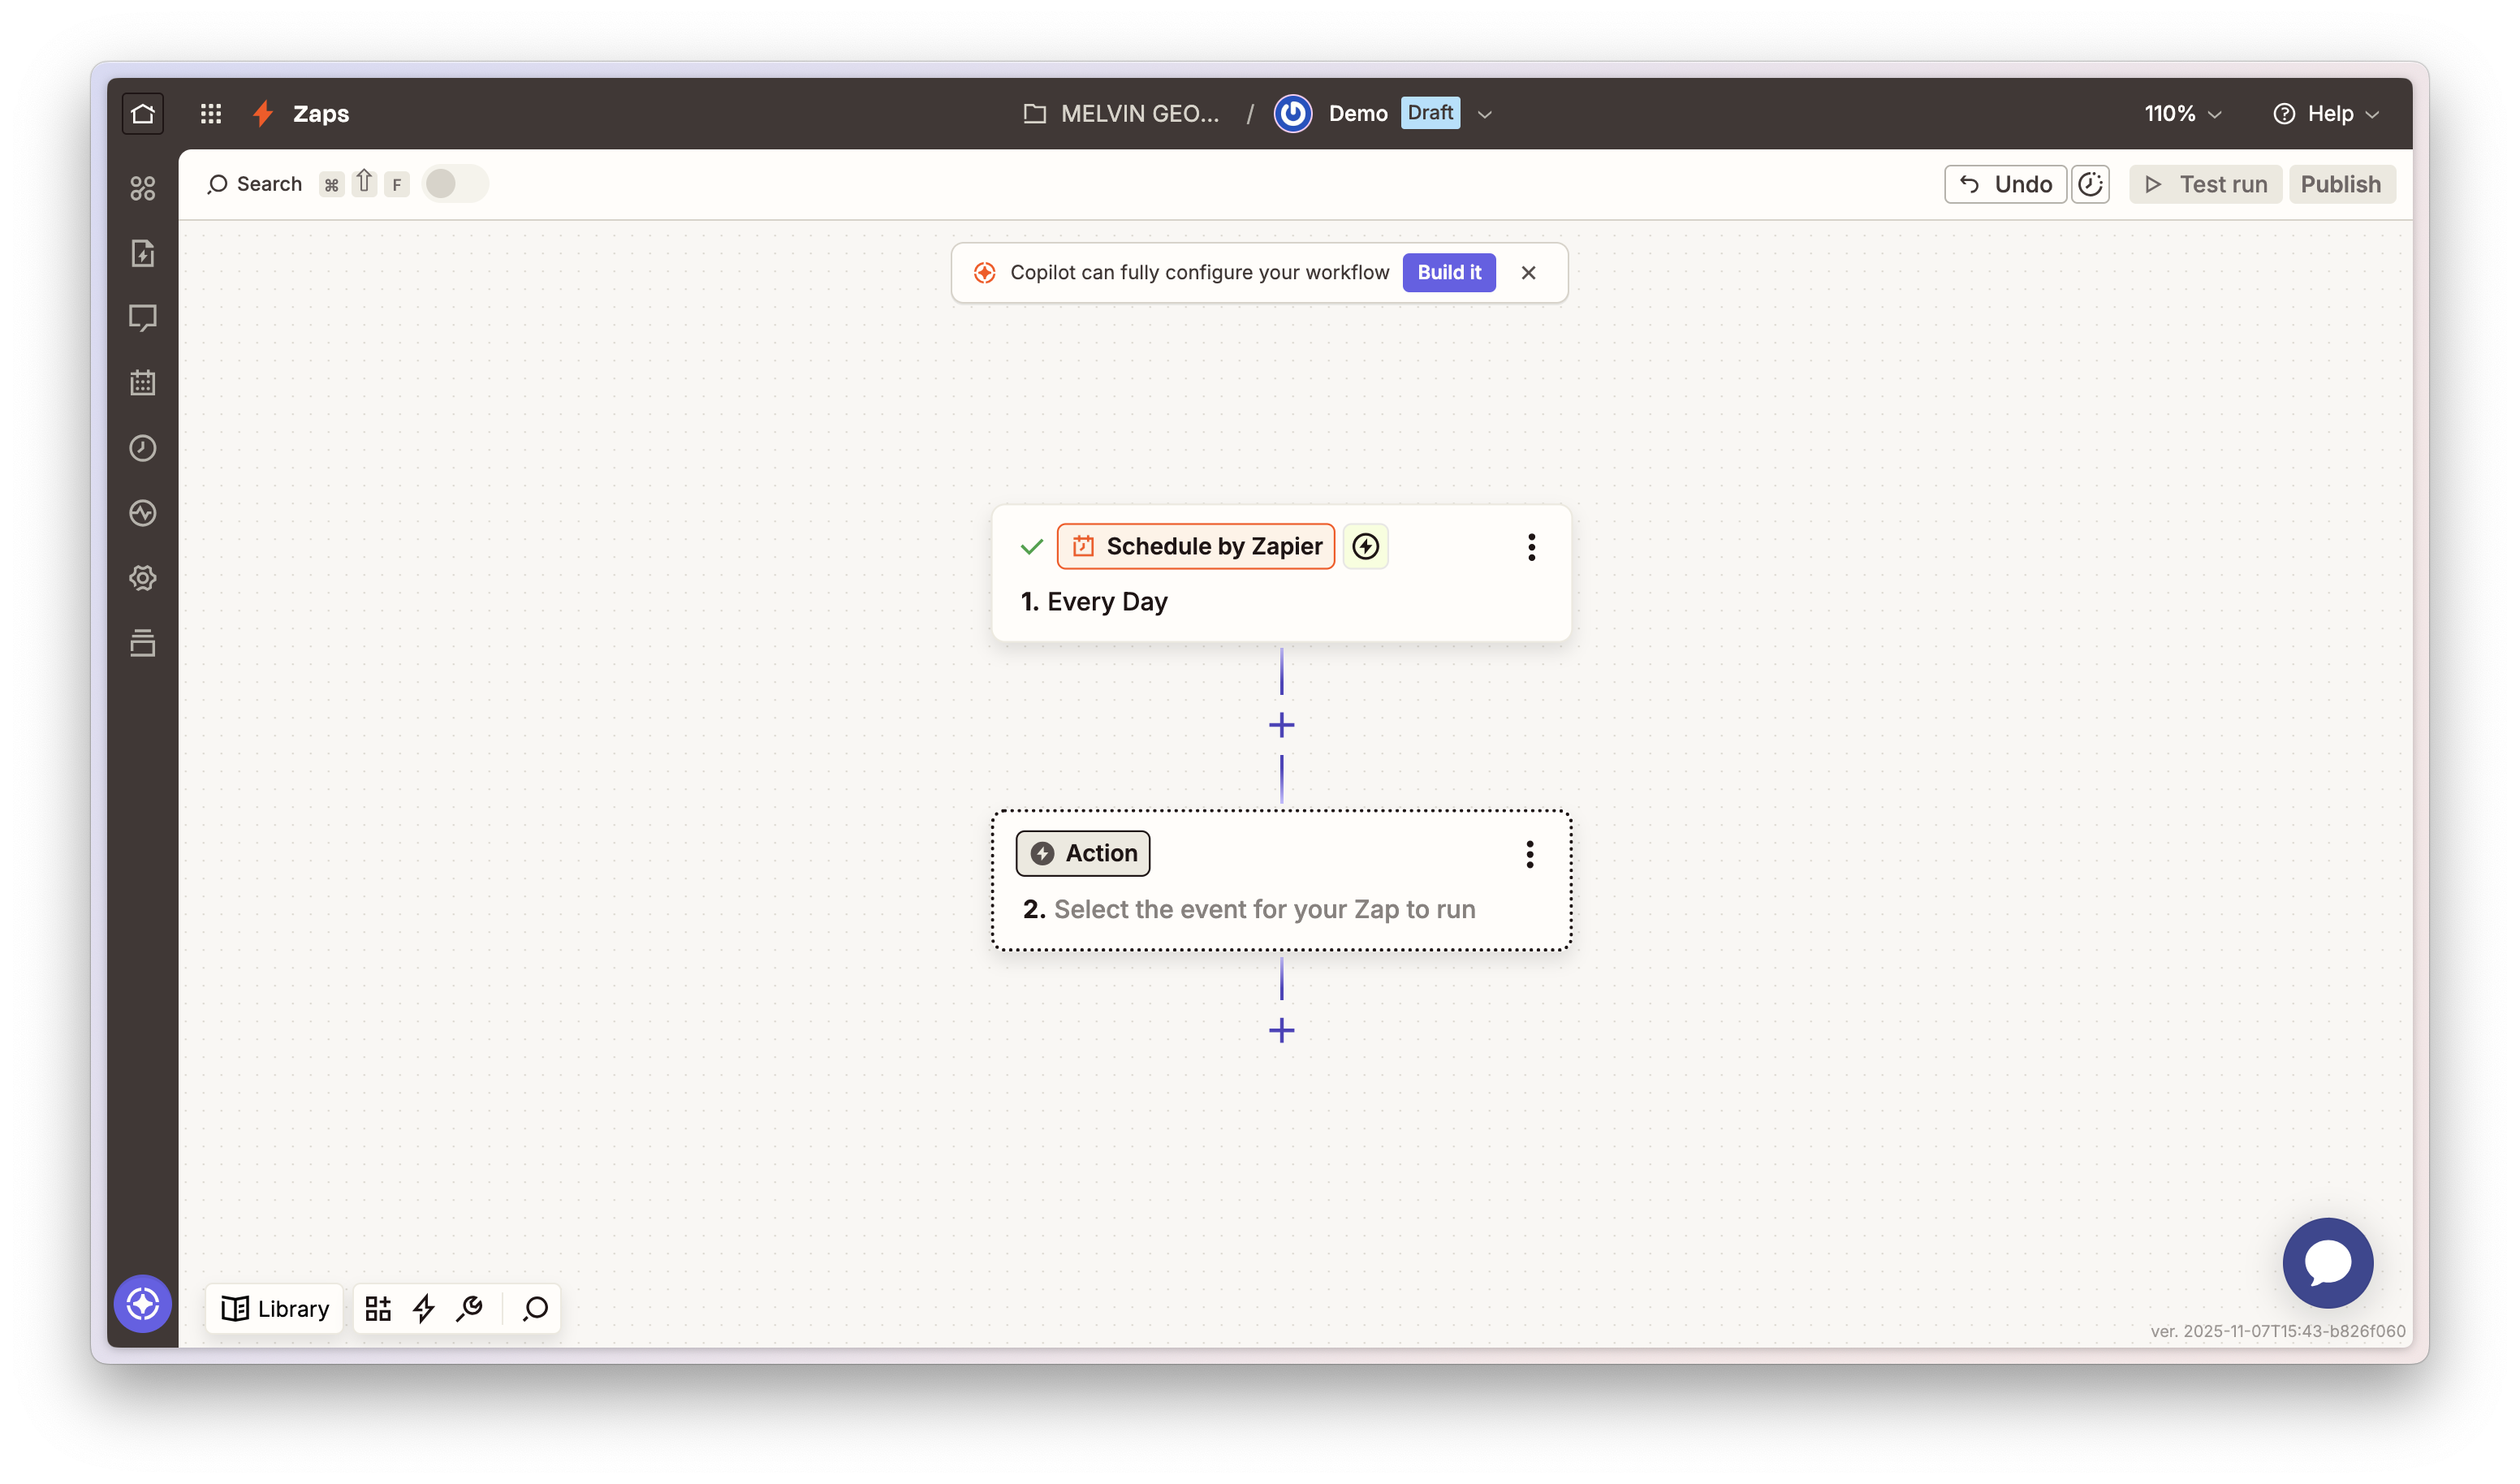
### Step 2: Create a Zap
1. Log in to your [Zapier account](https://zapier.com)
2. Click **Create Zap** to start a new workflow
3. Choose a trigger (e.g., Schedule by Zapier, Webhook, etc.)
4. Configure your trigger settings
### Step 3: Add PulpMiner Action
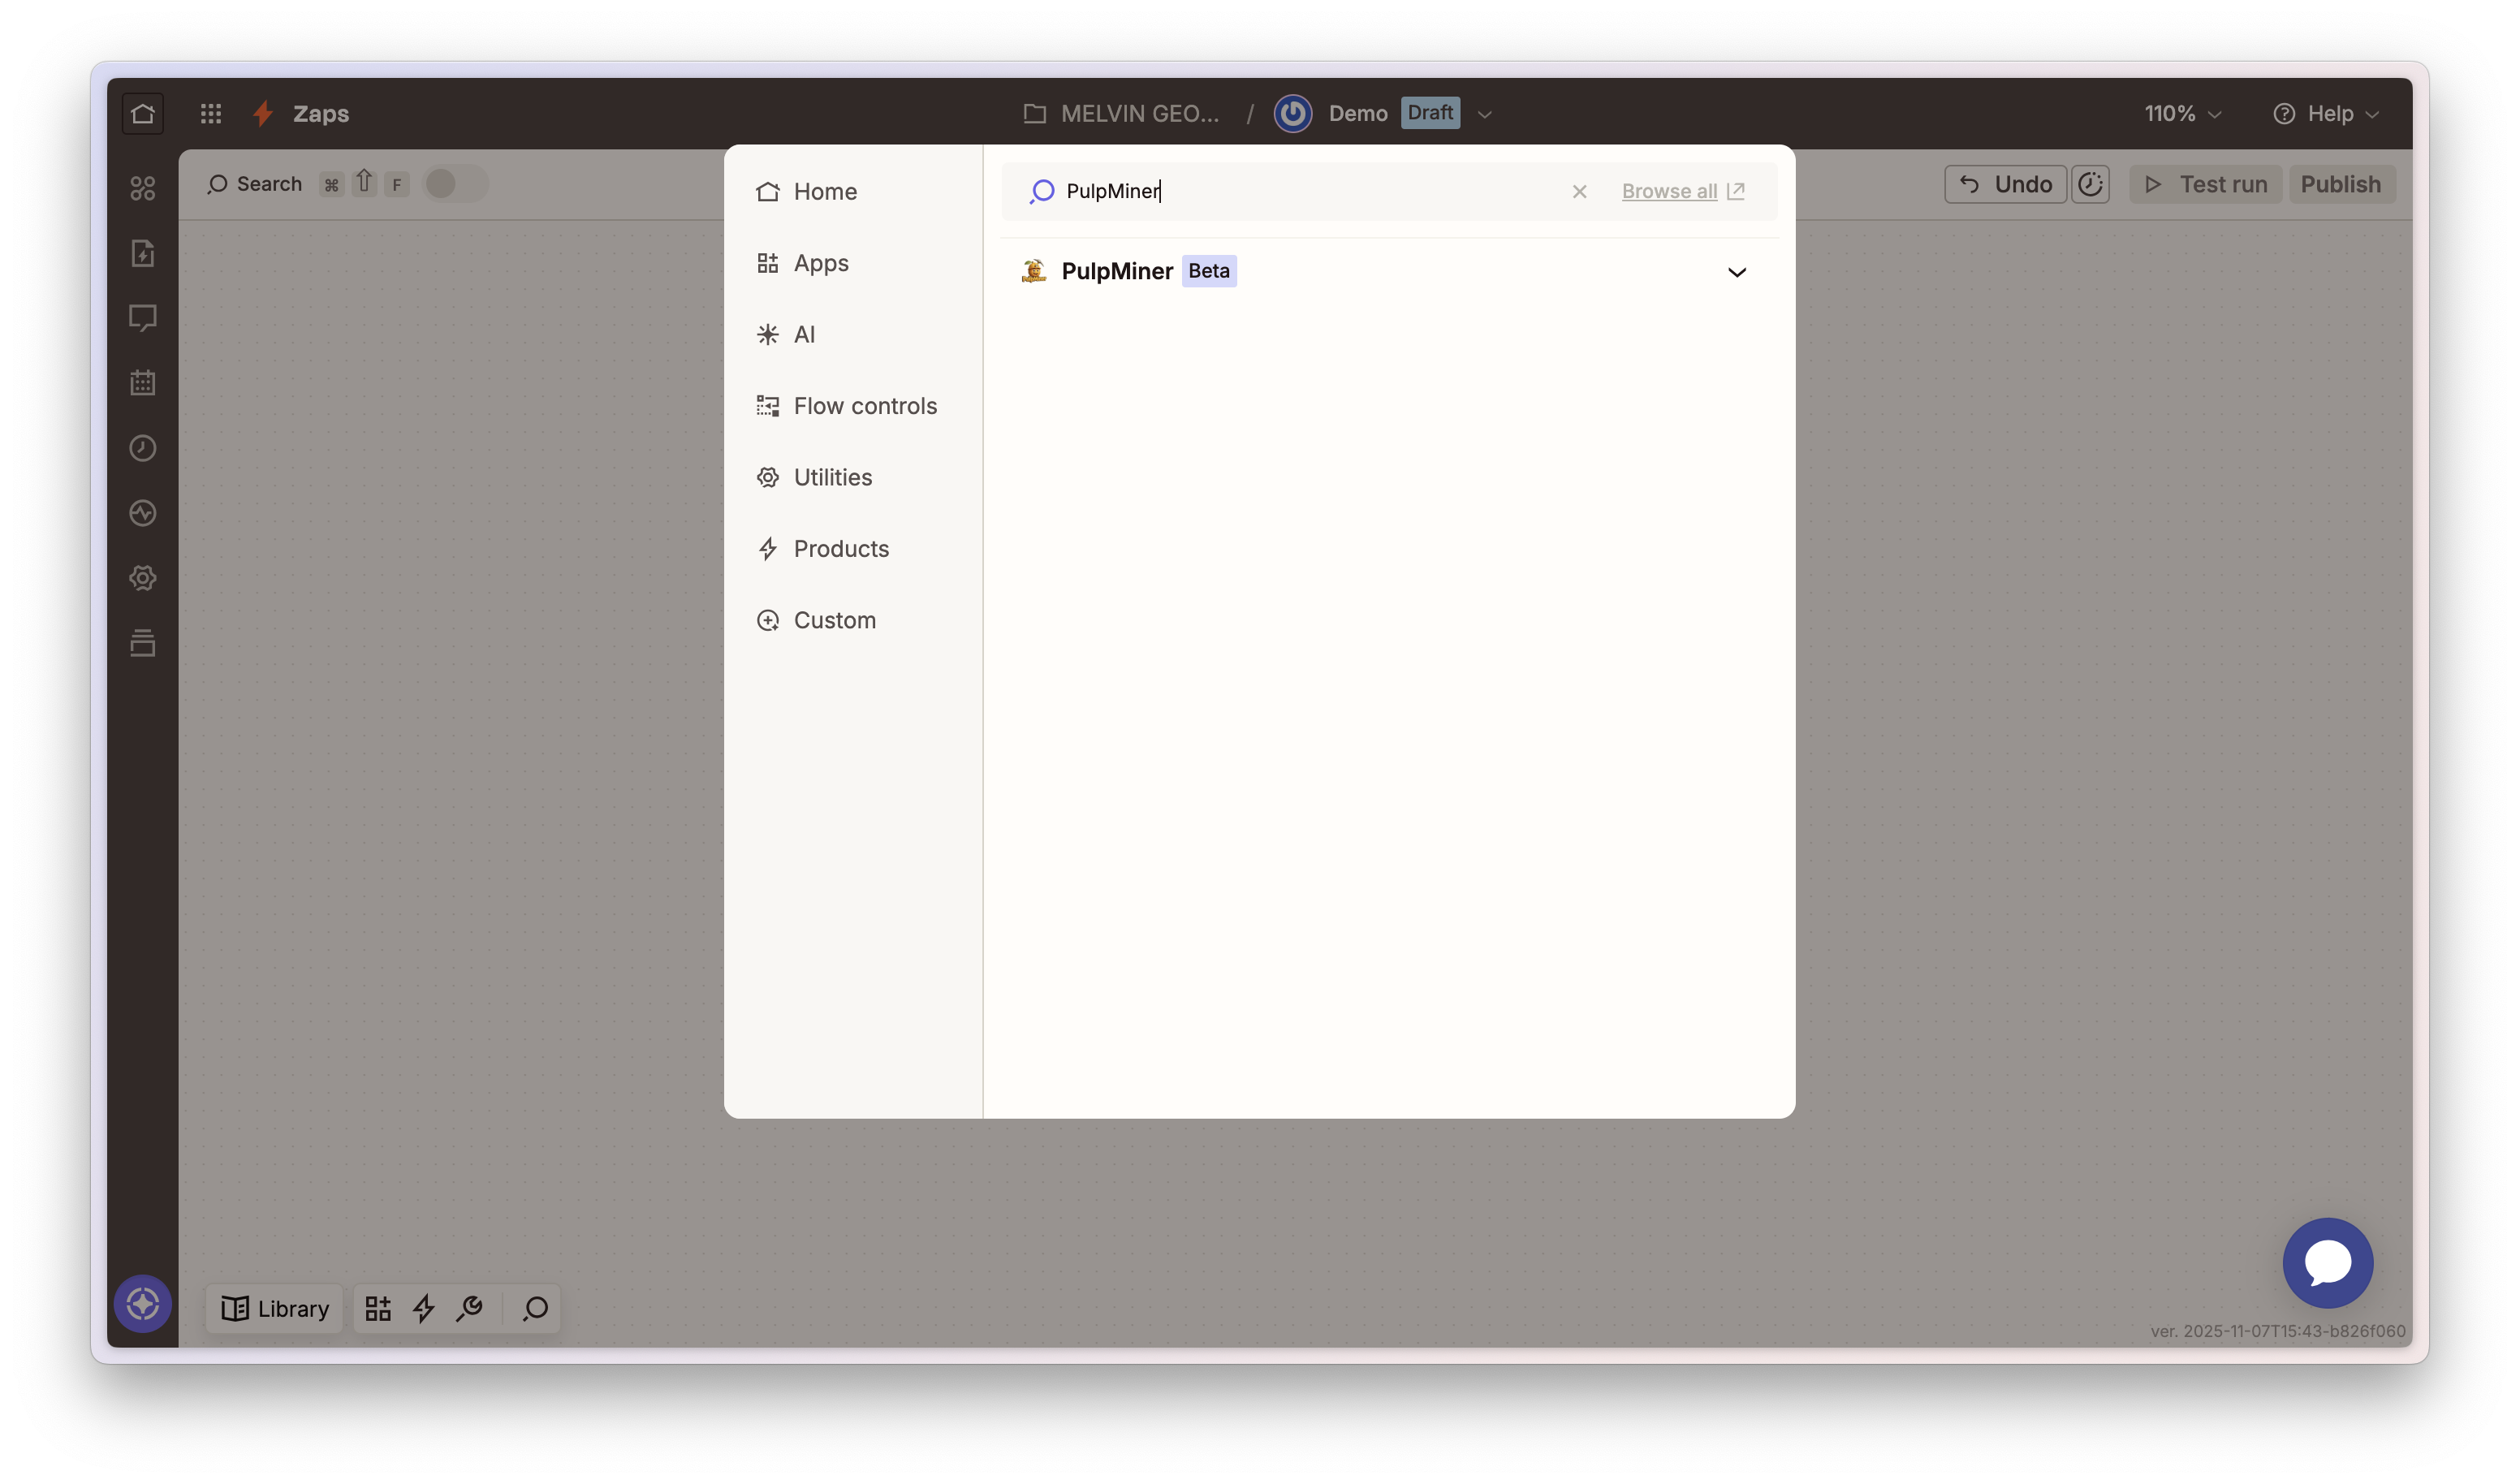
1. Click on the action step in your Zap
2. Search for "PulpMiner" in the app search dialog
3. Select **PulpMiner** from the results
### Step 4: Choose Action Event
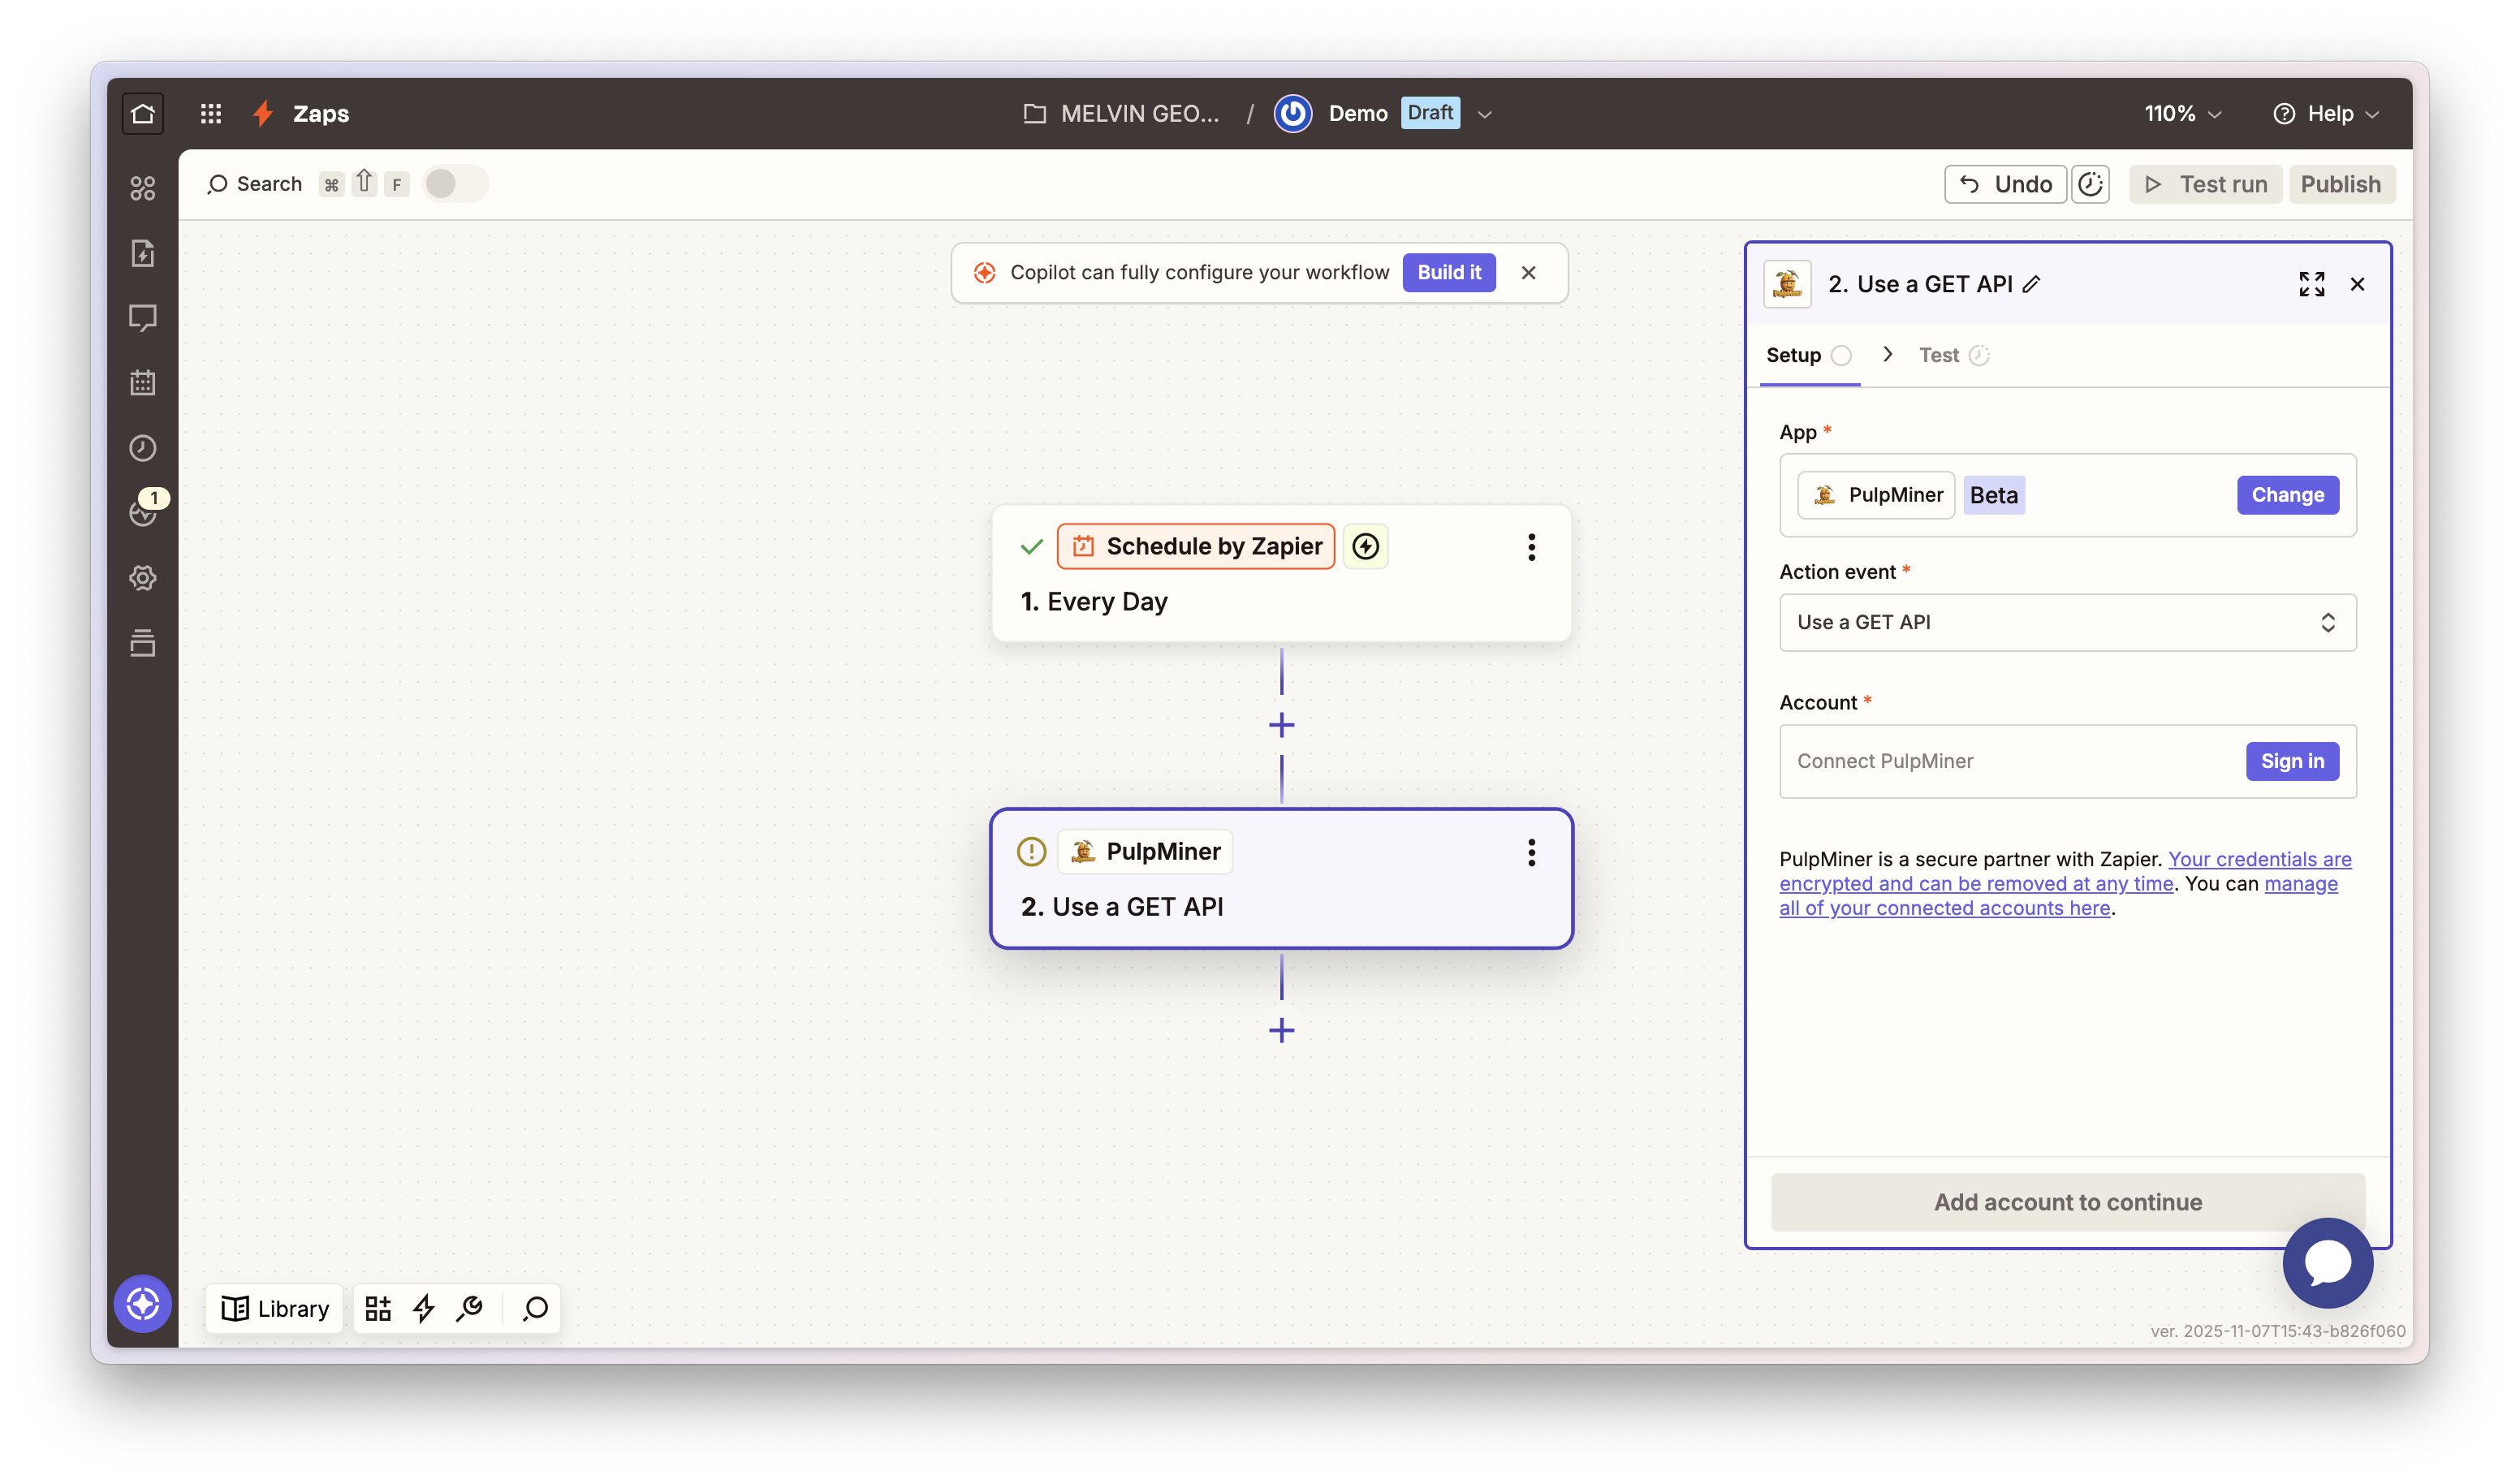
Select the action event you want to use:
* **Use a GET API**: For static APIs (fixed URLs, no dynamic variables)
* **Use a POST API**: For dynamic APIs (requires variables in request body)
Click the **Account** button to connect your PulpMiner account.
### Step 5: Connect Your Account
1. Click **Account** in the action configuration
2. Enter your PulpMiner API key
3. You can find your API key in your PulpMiner dashboard under "Saved APIs"
4. Click **Yes, Continue** to save the connection
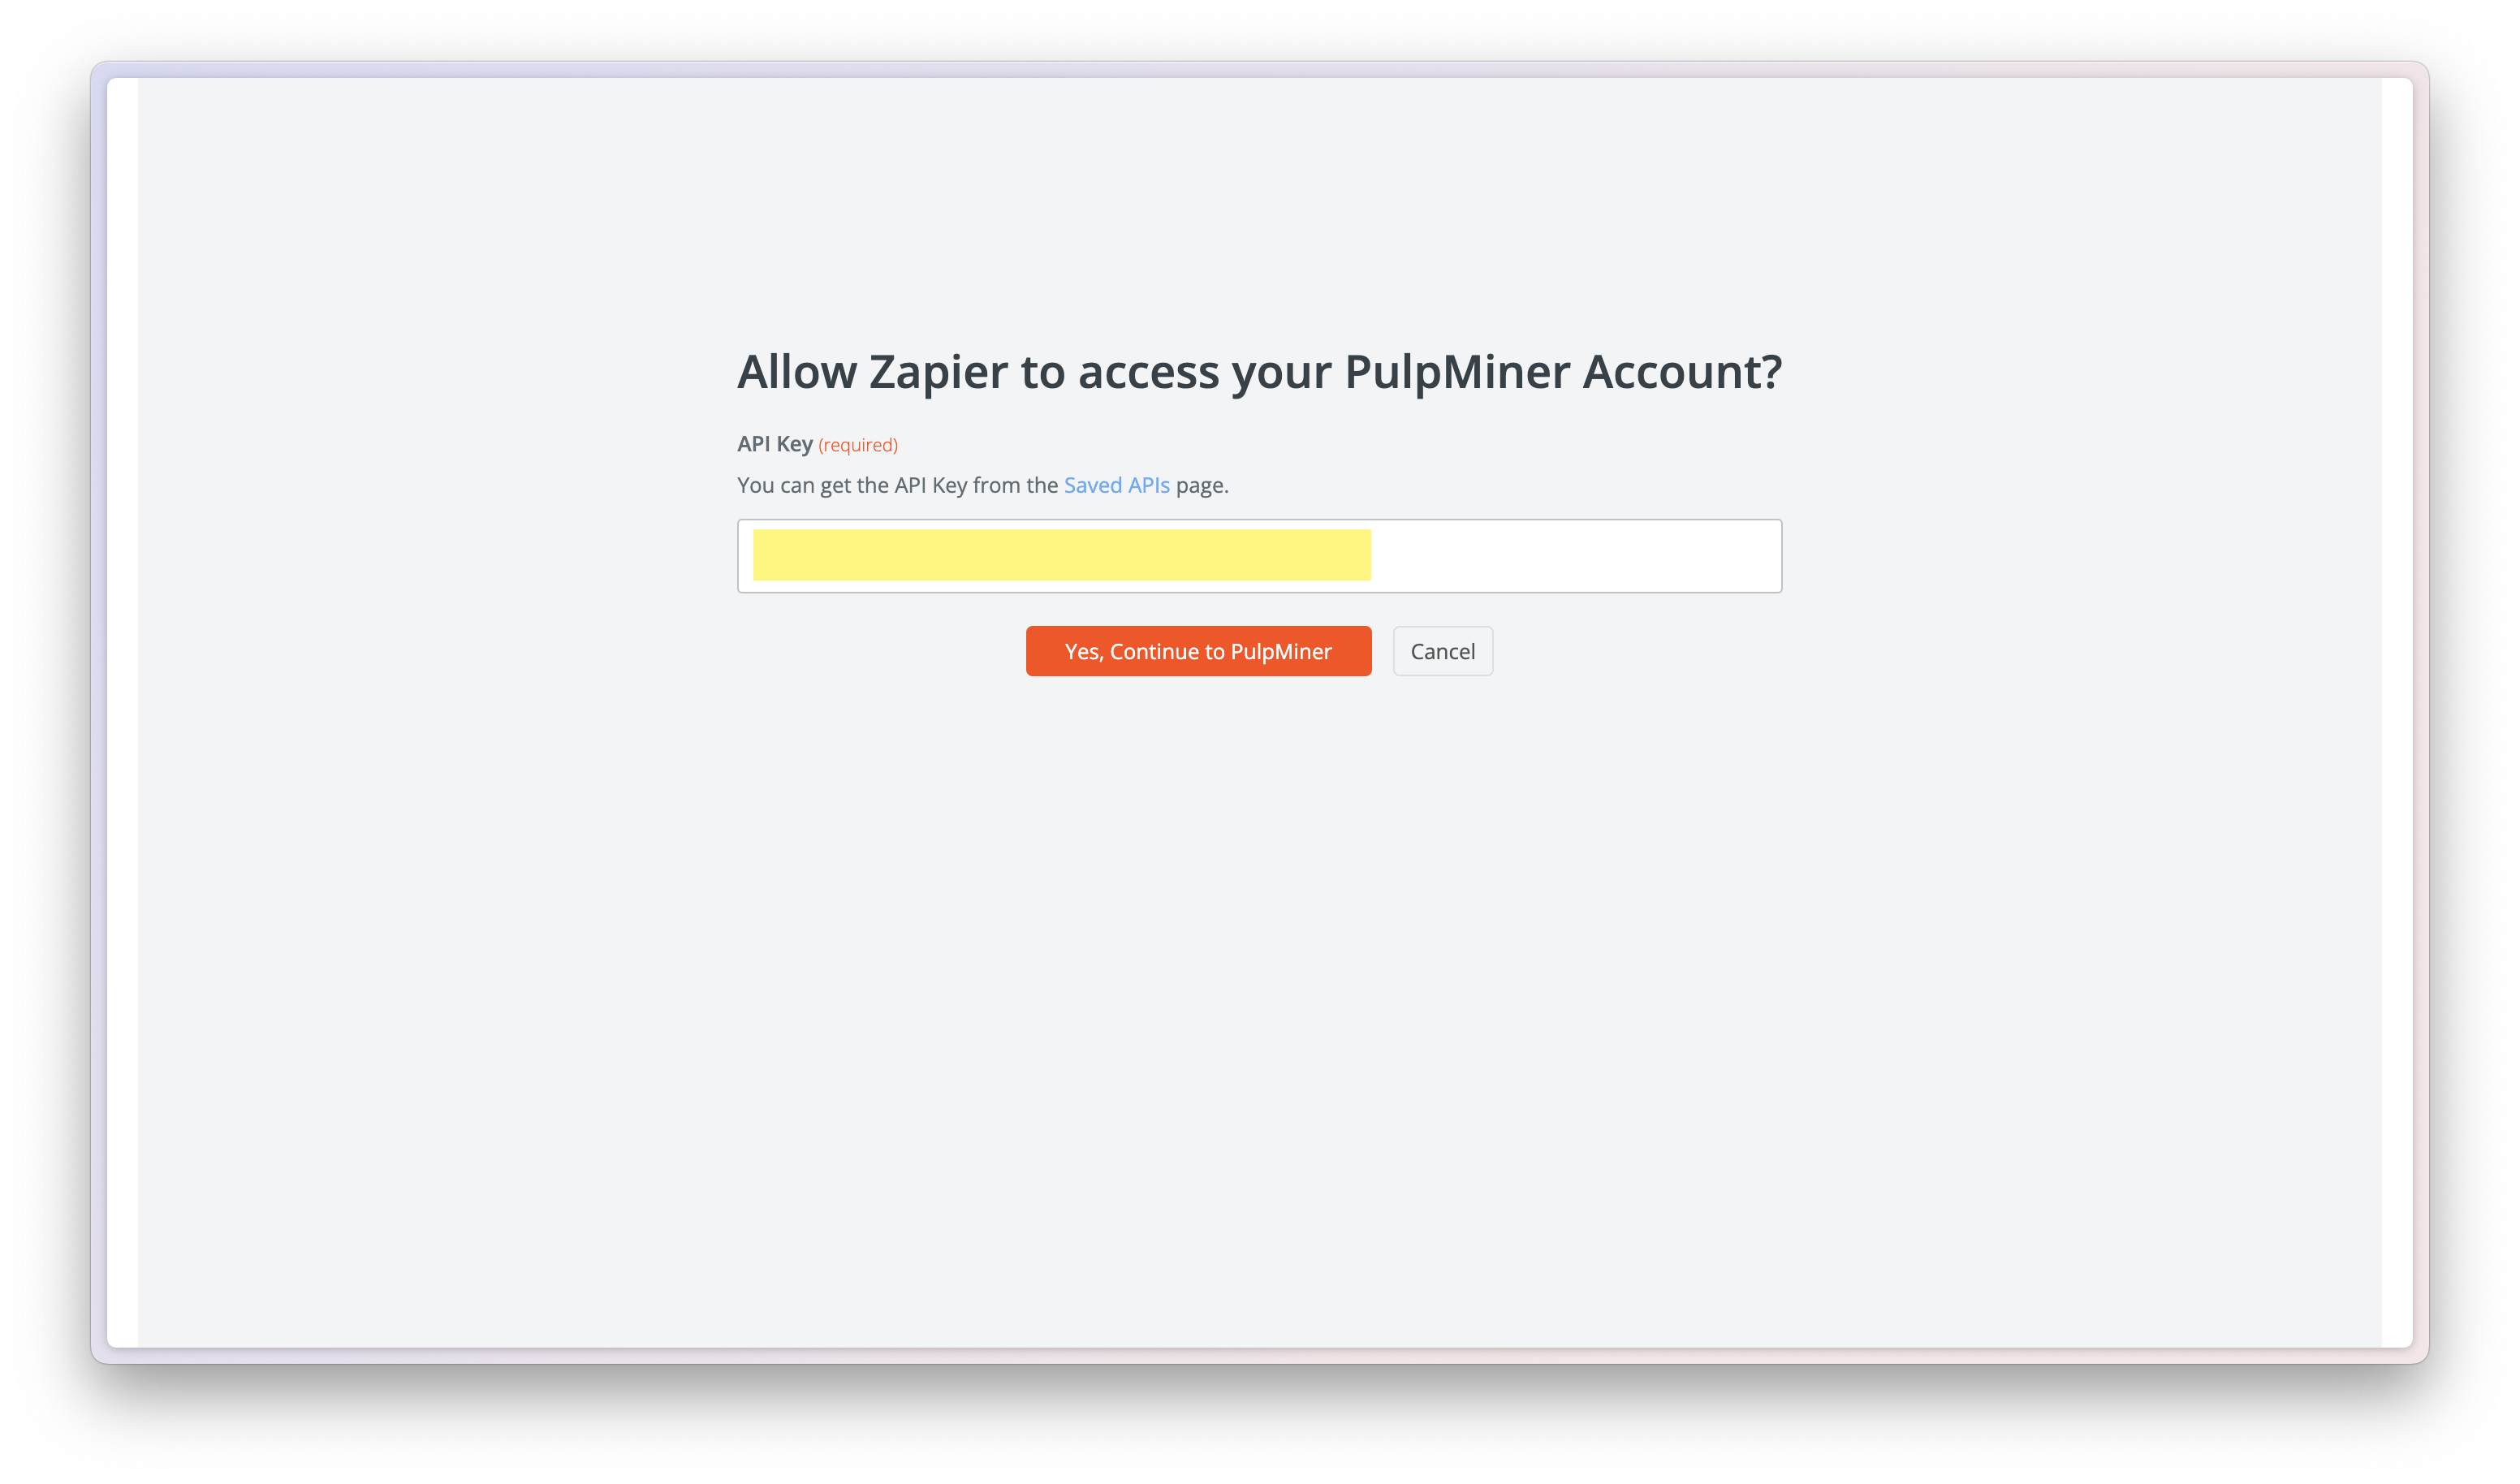
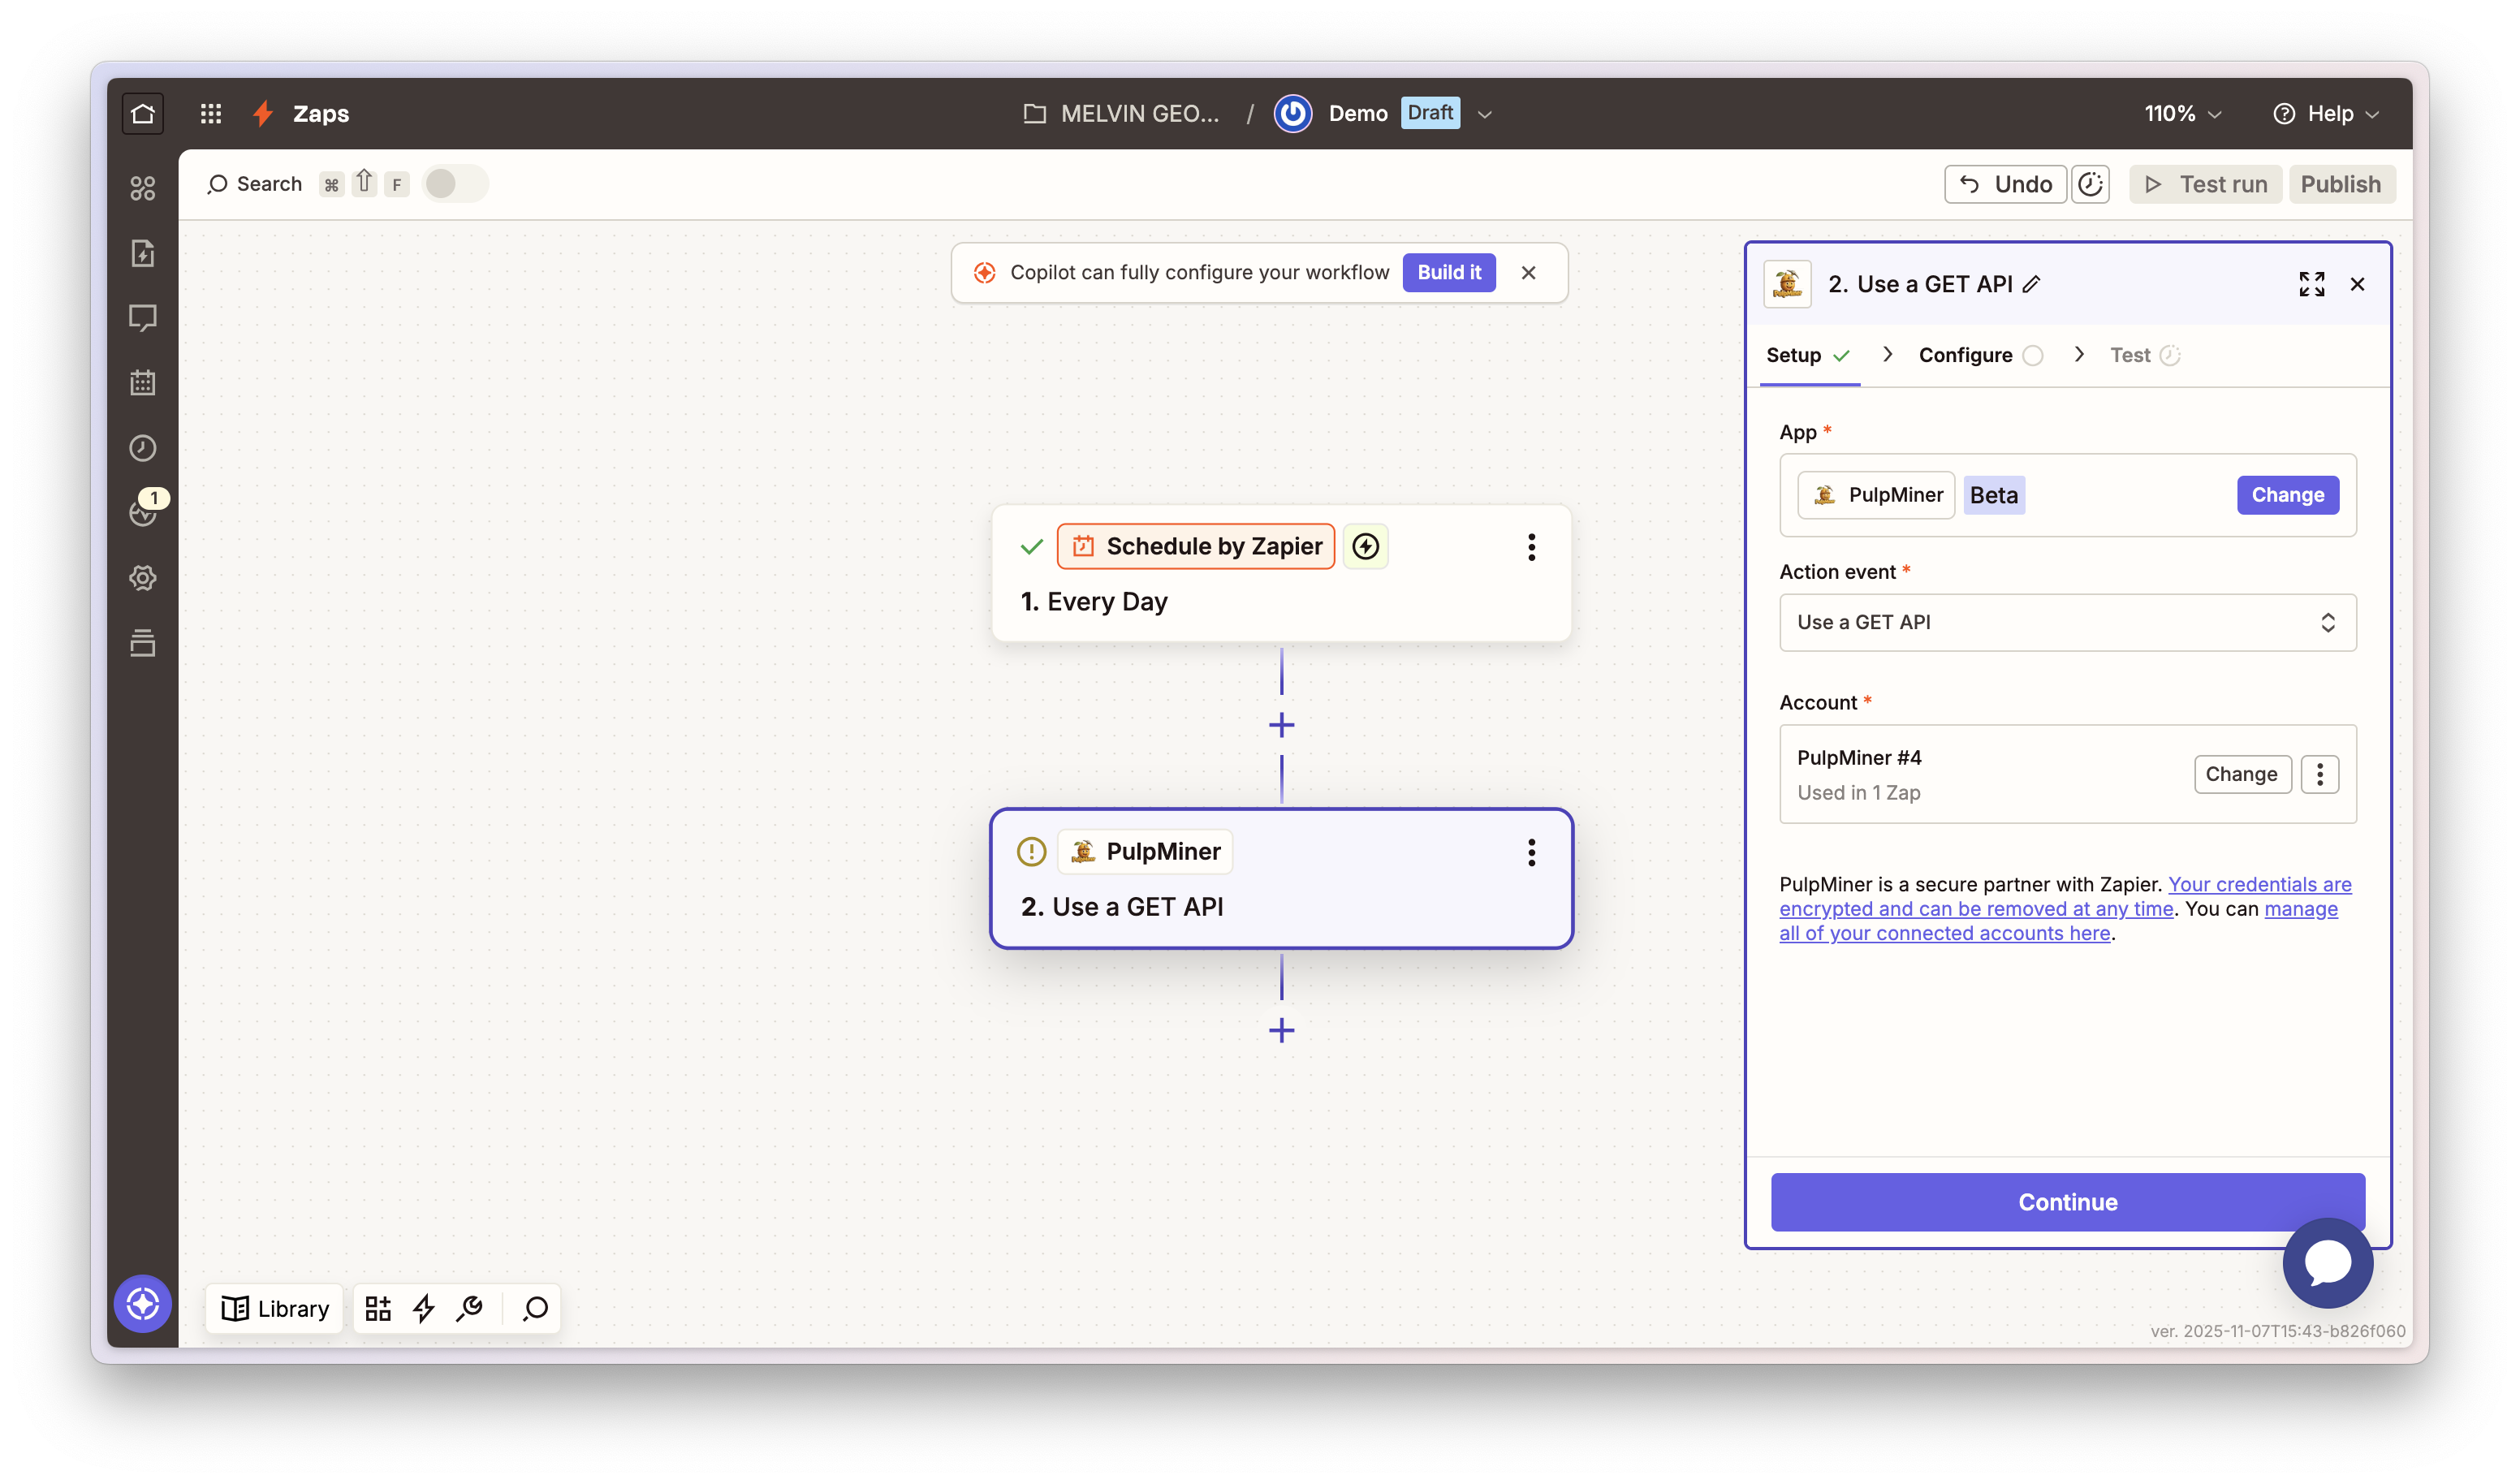
Your API key is sensitive information. Make sure to keep it secure and never share it publicly.
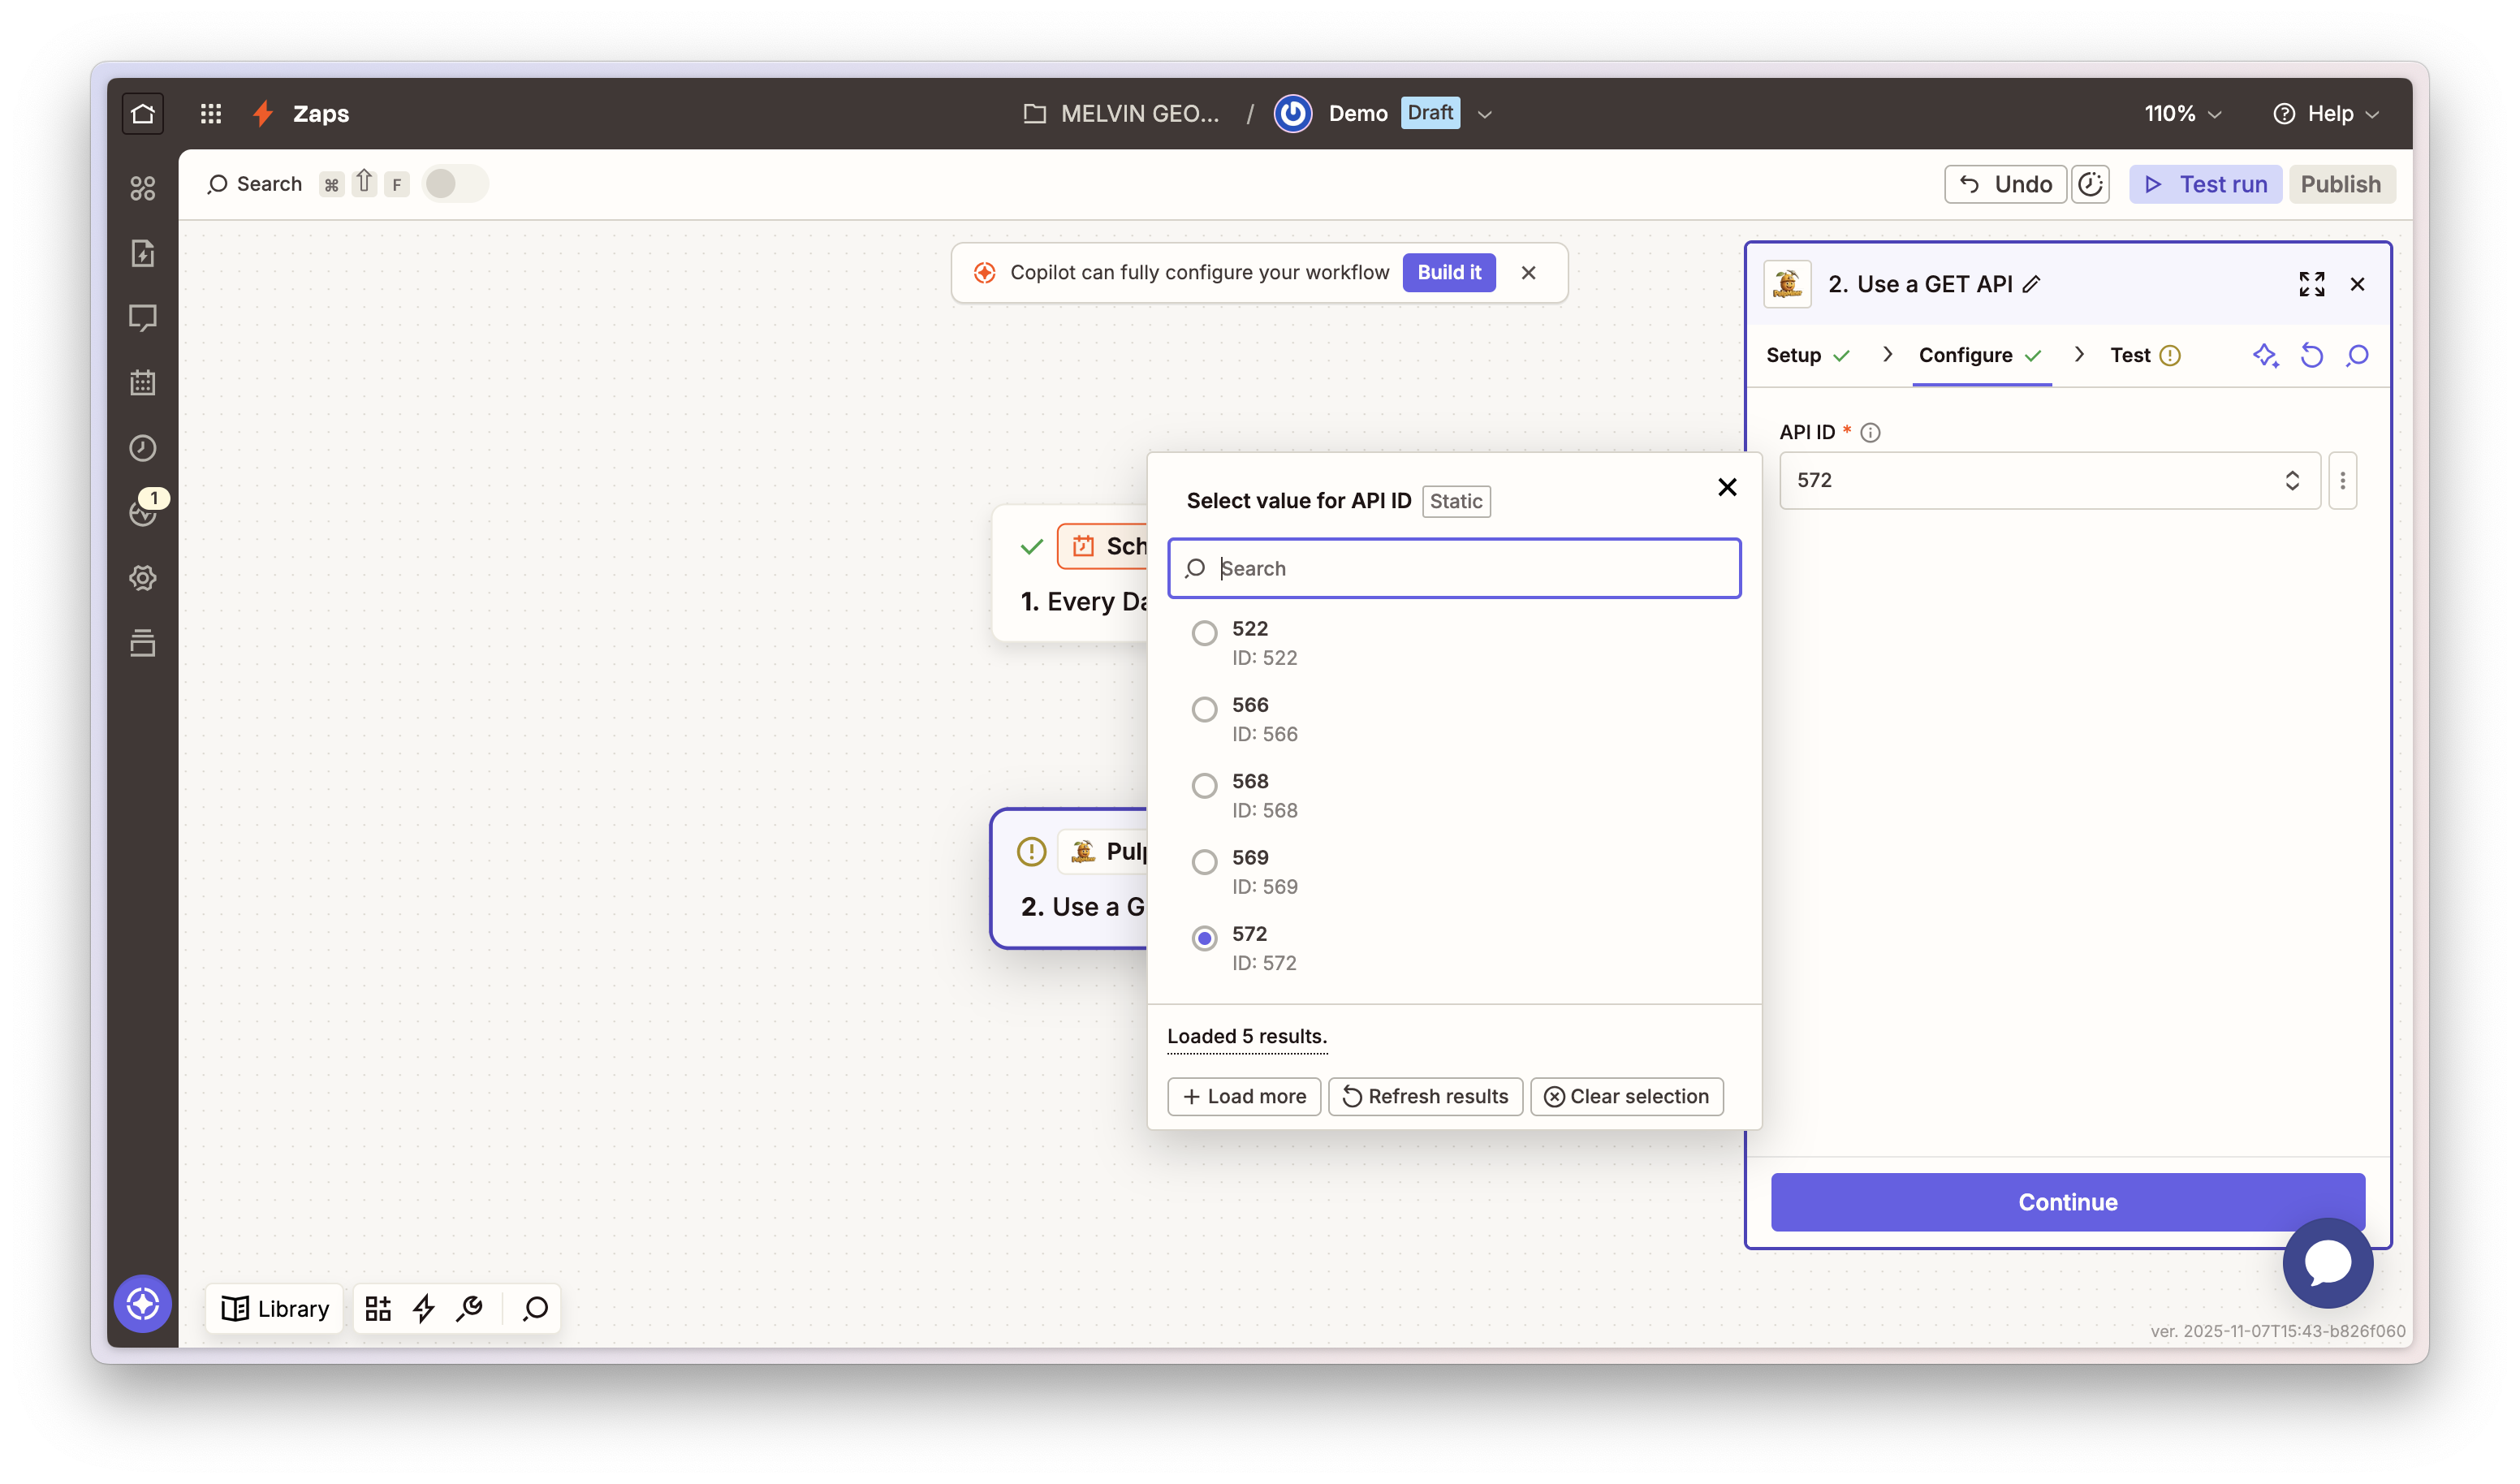
### Step 6: Configure the Action
1. Select your **API ID** from the dropdown menu, or enter it manually
2. The API ID is the numeric value found after creating a PulpMiner API (the value after `/external/` in the API URL)
3. For POST APIs, you'll also need to provide the **POST Body** in JSON format
### Step 7: Test Your Action
1. Click **Test action** to see the JSON response
2. Review the sample data structure returned from your API
3. This sample data shows the structure you can use in subsequent Zap steps
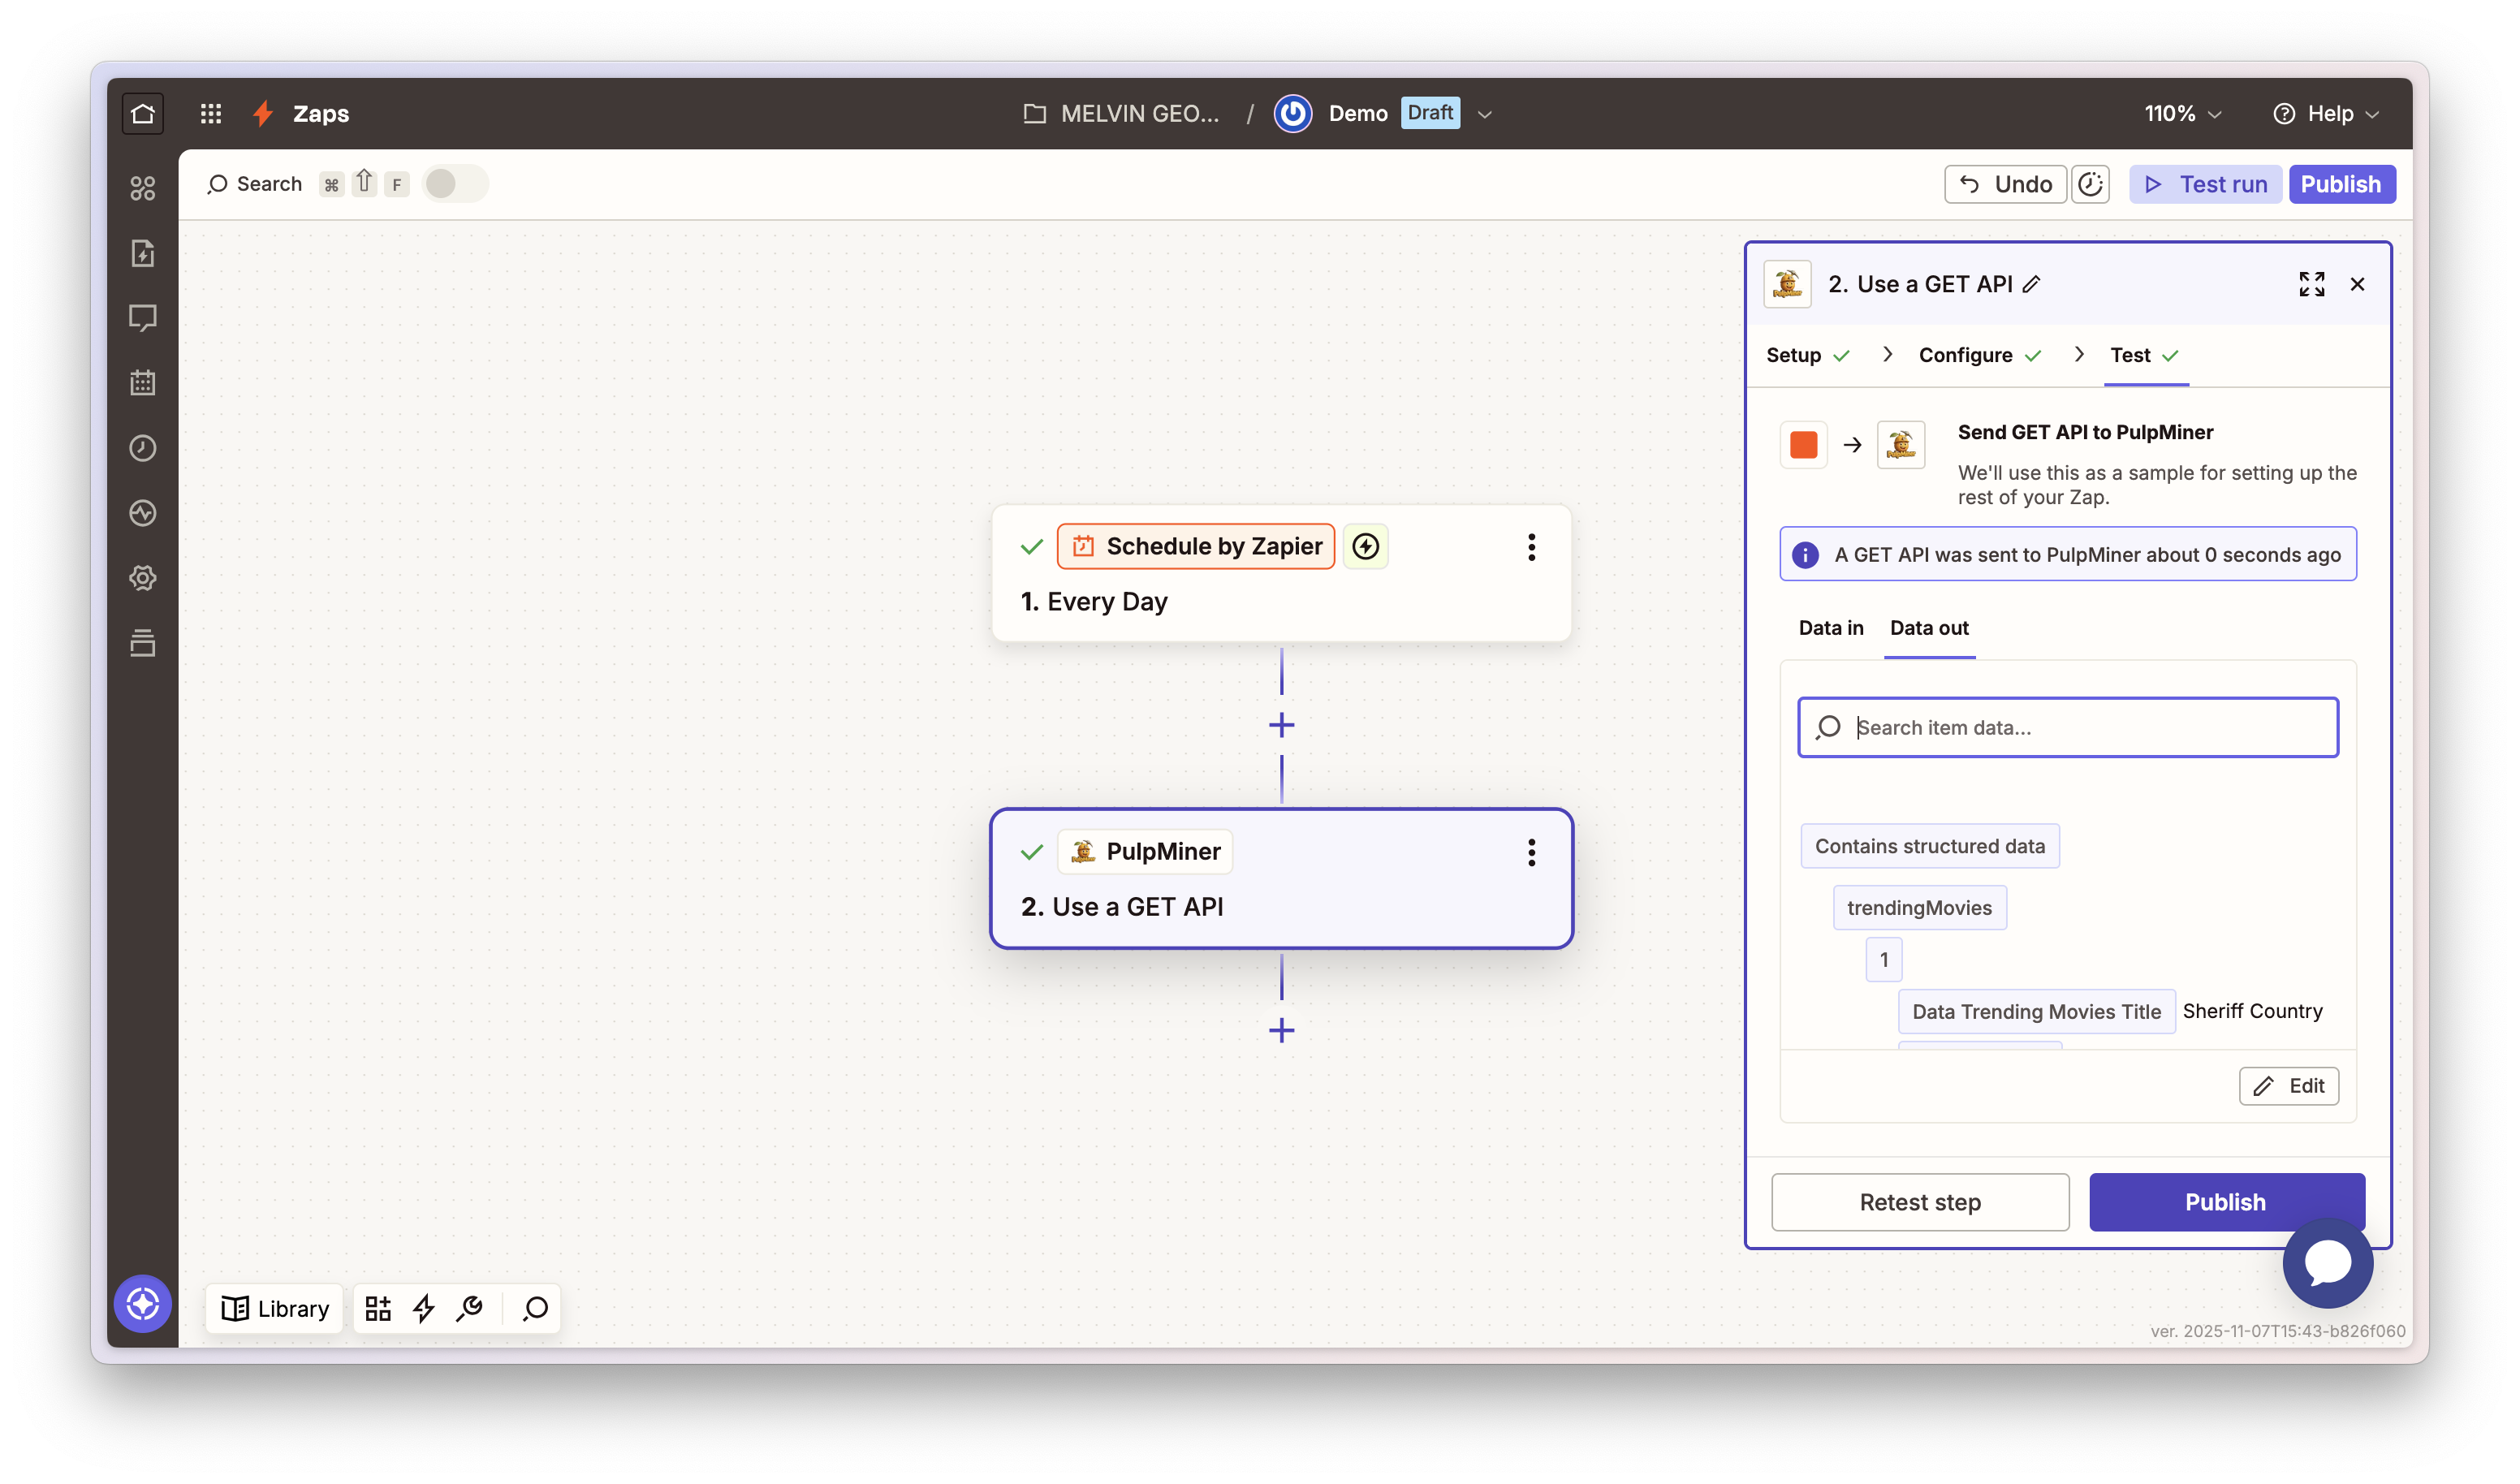
The sample data shown during testing is representative of the structure. When your Zap runs live, the API syncs data in the background and returns the actual current data.
## Available Actions
### Use a GET API
**What it does**: Consumes a GET-type PulpMiner API and returns the parsed result to your Zap.
**Inputs**:
* **API ID** (integer, required): Numeric ID of your PulpMiner API. It's the value after the `/external/` path in the API URL.
**Output**:
* `data`: Contains the structured response from your API
* `errors`: Contains errors if any occurred
**Use Cases**:
* Extracting data from fixed URLs
* Scraping static content pages
* Fetching data that doesn't change based on parameters
### Use a POST API
**What it does**: Use a POST-type PulpMiner API with a JSON body and returns the parsed result to your Zap.
**Inputs**:
* **API ID** (integer, required): Numeric ID of your PulpMiner API
* **POST Body** (text, required): The JSON body for the API call. You can copy the sample from the specific API in PulpMiner ("Saved API").
**Output**:
* `data`: Contains the structured response from your API
* `errors`: Contains errors if any occurred
**Use Cases**:
* Product pages with variable IDs
* Search results with dynamic parameters
* Category listings with filters
* User profiles with different usernames
## Use Cases
PulpMiner with Zapier is perfect for automating various data collection tasks:
Track competitor prices and get alerts in Slack when prices drop. Perfect for procurement automation.
**Example**: Monitor 100+ products automatically every hour
Collect news articles, blog posts, and updates from multiple sources into your content database.
**Example**: Build your own news feed from preferred sources
Extract contact info from directory sites, company listings, and social profiles for your CRM.
**Example**: Qualify leads from LinkedIn, industry directories
Track product launches, feature updates, and market trends from competitor websites.
**Example**: Stay ahead of competitor product releases
Monitor property listings, prices, and availability. Send new listings to buyers automatically.
**Example**: Get instant Slack notifications for new properties
Watch for new courses, enrollment dates, and price changes on learning platforms.
**Example**: Never miss enrollment deadlines
## Workflow Examples
### Example 1: Daily News Aggregation
**Scenario**: Extract news headlines from a website every day and send them via email.
**Zap Setup:**
1. **Trigger**: Schedule by Zapier (daily at 9 AM)
2. **Action**: PulpMiner - Use a GET API
* API ID: Your news website API ID
3. **Action**: Code by Zapier or Formatter - Process the JSON data to extract headlines
4. **Action**: Email by Zapier - Send formatted news summary
### Example 2: Product Price Monitoring
**Scenario**: Monitor product prices from an e-commerce site and alert when prices drop.
**Zap Setup:**
1. **Trigger**: Schedule by Zapier (run every hour)
2. **Action**: PulpMiner - Use a POST API
* API ID: Your product API ID
* POST Body: `{"productId": "12345"}`
3. **Action**: Filter by Zapier - Check if price is below threshold
4. **Action**: Slack or Email - Send alert if condition is met
### Example 3: Multi-Source Data Aggregation
**Scenario**: Collect data from multiple websites and combine into a single dataset.
**Zap Setup:**
1. **Trigger**: Manual Trigger or Webhook
2. **Multiple PulpMiner Actions**: Each fetching from different sources
3. **Action**: Airtable or Google Sheets - Store aggregated results
### Example 4: Dynamic Content Extraction
**Scenario**: Extract user-specific content based on input from a webhook.
**Zap Setup:**
1. **Trigger**: Webhook by Zapier - Receives user ID
2. **Action**: PulpMiner - Use a POST API
* API ID: Your dynamic API ID
* POST Body: Use Zapier's data mapping to pass webhook data
3. **Action**: Process Data - Transform extracted data
4. **Action**: Return Response - Send data back to webhook caller
## Using Data Mapping
Zapier allows you to map data from previous steps to your PulpMiner action:
### Mapping Data to POST Body
When using "Use a POST API", you can map data from previous steps:
1. Click in the **POST Body** field
2. Use Zapier's data mapping feature to select fields from previous steps
3. The data will be automatically formatted as JSON
**Example POST Body with mapped data:**
```json theme={null}
{
"productId": "{{123__product_id}}",
"category": "{{123__category}}"
}
```
Where `{{123__product_id}}` references a field from step 123.
## Error Handling
### Common Errors
1. **Authentication Error**
* **Cause**: Invalid or missing API key
* **Solution**: Verify your API key in the account connection and ensure it's active
2. **Invalid API ID**
* **Cause**: API ID doesn't exist or is incorrect
* **Solution**: Check your PulpMiner dashboard for the correct API ID
3. **Missing Variables**
* **Cause**: POST request missing required dynamic variables
* **Solution**: Ensure all variables defined in your PulpMiner API are included in the POST Body
4. **Rate Limiting**
* **Cause**: Exceeding credit limits or request rate
* **Solution**: Check your credit balance and implement delays between Zap executions
### Response Format
PulpMiner actions return data in a uniform format:
**Success Response:**
```json theme={null}
{
"data": {
"title": "Example Page",
"content": "Page content...",
"metadata": {
"author": "John Doe",
"date": "2024-03-20"
}
},
"errors": null
}
```
**Error Response:**
```json theme={null}
{
"data": null,
"errors": [
{
"message": "error message here"
}
]
}
```
## Best Practices
### 1. Account Management
* Rotate API keys periodically
* Never share API keys publicly
### 2. Rate Limiting
* Be mindful of Zap execution frequency
* Monitor your PulpMiner credit usage
* Use Zapier's built-in rate limiting features for high-volume Zaps
### 3. Data Processing
* Always validate the structure of returned JSON data
* Use Zapier's Formatter or Code by Zapier for complex data transformations
* Test your Zaps thoroughly before turning them on
### 4. Caching
* Enable caching in your PulpMiner API when appropriate
* Balance between data freshness and performance
* Consider using Zapier's built-in caching for frequently accessed data
### 5. Monitoring
* Set up Zapier notifications for failed Zaps
* Monitor credit usage in your PulpMiner dashboard
* Review Zap execution history regularly
## Troubleshooting
### Action Not Appearing
* Ensure PulpMiner is properly connected in your Zapier account
* Try disconnecting and reconnecting your account
* Check if the action is available in your Zapier plan
### Authentication Issues
* Verify API key is correct
* Check if API key is active in PulpMiner dashboard
* Try disconnecting and reconnecting your account in Zapier
### Data Not Returning
* Verify API ID is correct
* Check if the source webpage is accessible
* Review PulpMiner API status in dashboard
* Test the API directly with curl first
### Dynamic Variables Not Working
* Ensure variable names match exactly (case-sensitive)
* Verify all required variables are provided in POST Body
* Check JSON format in POST Body field
* Review your PulpMiner API configuration
### Sample Data vs Live Data
* Sample data shown during testing is representative
* Live Zap executions return actual current data
* The API syncs data in the background when the Zap runs
## Resources
* [Zapier Documentation](https://zapier.com/help)
* [PulpMiner on Zapier](https://zapier.com/apps/pulpminer/integrations)
* [PulpMiner API Documentation](/api-reference/endpoints/external-api)
* [PulpMiner API Keys Guide](/essentials/api-keys)
* [PulpMiner Website](https://pulpminer.com)
## Support
If you encounter issues with the Zapier integration:
1. Check the [PulpMiner API documentation](/api-reference/endpoints/external-api)
2. Review Zapier workflow execution logs
3. Test your PulpMiner API directly with curl
4. Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
## Next Steps
* Learn more about [PulpMiner API endpoints](/essentials/api-endpoints)
* Explore [dynamic variables](/essentials/api-endpoints#dynamic-variables)
* Check out [caching strategies](/essentials/caching)
* Review [credit management](/essentials/credits)
# Introduction
Source: https://docs.pulpminer.com/introduction
Welcome to Pulpminer - Transform Any Webpage Into a JSON API
# Welcome to Pulpminer
Pulpminer is a powerful tool that lets you transform any webpage into a structured JSON API with just a few clicks. Whether you need to extract data from a single webpage or create multiple API endpoints for different sources, Pulpminer makes it easy with its AI-powered data extraction and formatting capabilities.
## What is Pulpminer?
Pulpminer is a web-based service that:
* Converts webpage content into structured JSON data
* Creates instant API endpoints for your data
* Uses AI to intelligently extract and format data
* Provides flexible caching options for better performance
* Secures your endpoints with API keys
## Key Features
### 1. AI-Powered JSON Generation
* Input any webpage URL
* Optionally specify your desired JSON structure
* Let our AI extract and format the data automatically
### 2. Multiple Scrapers
* Select from different numbered scrapers (scraper 1, scraper 2, etc.)
* Each scraper optimized for specific webpage types and content structures
* Try different scrapers to find the best fit for your needs
### 3. Custom JSON Structure
* Define exactly how you want your data formatted
* Edit and preview the JSON structure before saving
* Ensure data consistency across API calls
### 4. Instant API Endpoints
* Get a unique API endpoint for each saved configuration
* Access your data via simple GET requests
* Secure access with your API key
### 5. Flexible Caching
* Enable caching for better performance
* Choose between real-time and cached data
* Automatic cache updates for fresh content
### 6. Secure Access
* Every endpoint protected by API keys
* Manage your API keys easily
* Monitor usage and access
## Getting Started
Ready to create your first JSON API? Check out our [Quickstart Guide](/quickstart) to begin transforming webpages into structured data endpoints in minutes.
## Use Cases
Pulpminer is perfect for:
* Converting unstructured webpage data into JSON APIs
* Creating consistent data feeds from multiple sources
* Building data aggregation services
* Automating data extraction workflows
* Integrating web data into your applications
## System Architecture
Pulpminer is built on a robust infrastructure:
* Frontend: Modern React application for intuitive user interface
* Backend: Cloudflare Workers for global distribution and high availability
* AI: Advanced models for intelligent data extraction and formatting
* Storage: Fast and reliable data storage with automatic caching
* Security: Industry-standard authentication and API key management
## Credits System
Pulpminer uses a simple credit system:
* 0.25 credits per JSON generation (Without JS Render & Use Session)
* 0.4 credits per API endpoint request (Without JS Render & Use Session)
* Pay only for what you use
* No monthly subscription required
* Credits never expire
Ready to get started? Head over to our [Quickstart Guide](/quickstart) to create your first JSON API endpoint.
# Quickstart Guide
Source: https://docs.pulpminer.com/quickstart
Learn how to create your first JSON API endpoint with Pulpminer
# Quickstart Guide
This guide will walk you through creating your first JSON API endpoint with Pulpminer. In just a few minutes, you'll be able to transform any webpage into a structured JSON API.
## Prerequisites
Before you begin, make sure you have:
* A Pulpminer account (sign up at pulpminer.com)
* The URL of a webpage you want to convert to an API
* Some credits in your account (new accounts start with free credits)
## Step 1: Access the Dashboard
1. Sign in to your Pulpminer account
2. Navigate to the API Generation page
3. You'll see the main interface with a URL input field
## Step 2: Generate JSON from a Webpage
1. Enter your target webpage URL in the input field
2. Select a scraper (scraper 1, scraper 2, etc.) from the dropdown menu
* Each scraper is optimized for different types of webpages
* Try different scrapers to find the one that works best for your page
3. **Select an LLM (AI Model) for JSON generation**
* Choose from available models (e.g., Gemini 2, GPT-4)
* The LLM determines how the JSON is generated from the webpage
4. **Enter a valid CSS selector**
* Specify a CSS selector to target a specific section of the webpage (e.g., 'body', '.main-content', '#products')
* This helps extract only the relevant part of the page
5. **Provide a Data Extraction Rule for AI**
* Optionally describe what you want the AI to extract (e.g., "Fetch all 20 products", "Extract all blog post titles")
* This guides the LLM for more accurate results
6. Click "Generate JSON from webpage content"
7. Wait a few seconds while our AI analyzes the page
8. Review the generated JSON structure in the editor
The AI will automatically identify and extract key information from the webpage using your selected scraper. You can customize this structure in the next step.
## Step 3: Customize the JSON Structure (Optional)
1. Use the interactive JSON editor to modify the structure
2. Add or remove fields as needed
3. Rearrange data to match your requirements
4. Preview the changes in real-time
If you're happy with the AI-generated structure, you can skip this step and proceed to saving your API.
## Step 4: Configure API Settings
1. Under "Saving Options", decide if you want to enable caching:
* **Enabled**: Faster responses, data updated every 15 minutes
* **Disabled**: Real-time data, fresh content on every request
2. Configure session state (only available with Scraper 1):
* **Use Session**: Establishes a session with the origin URL before connecting to the target URL. Useful for .gov websites and domains that require session authentication
* **No Session**: Uses a fresh connection for each request
3. Optionally enable dynamic variables:
* Toggle the "Enable Dynamic Variables" switch
* Define variable names for URL path segments and query parameters
* Preview how your dynamic URL will look with the variables
4. Click "Save as API" to create your endpoint
## Step 5: Get Your API Key
1. Go to the API Keys section
2. Copy your unique API key
3. Keep this key secure - you'll need it for all API requests
## Step 6: Use Your New API
### For Static APIs (without dynamic variables):
Your API endpoint will be in this format:
```bash theme={null}
GET https://api.pulpminer.com/external/{api_id}
```
To make a request:
```bash theme={null}
curl -H "apikey: YOUR_API_KEY" https://api.pulpminer.com/external/{api_id}
```
### For Dynamic APIs (with variables):
Your API endpoint will be in this format:
```bash theme={null}
POST https://api.pulpminer.com/external/{api_id}
```
To make a request with dynamic variables:
```bash theme={null}
curl -X POST -H "apikey: YOUR_API_KEY" -H "Content-Type: application/json" \
-d '{"variableName1": "value1", "variableName2": "value2"}' \
https://api.pulpminer.com/external/{api_id}
```
Replace `YOUR_API_KEY` with your actual API key and `{api_id}` with the ID of your saved API.
## Understanding Credit Usage
Each action uses credits:
* Generating JSON: 0.25 credits (base), 0.35 credits (with JS rendering)
* API endpoint request: 0.4 credits (base), 0.5 credits (with JS rendering)
Monitor your credit usage in the dashboard to ensure uninterrupted service.
## Next Steps
Now that you've created your first API endpoint, you can:
* Create more endpoints for different webpages
* Set up dynamic variables for flexible API usage
* Explore advanced JSON customization options
* Learn about [caching strategies](/essentials/caching)
* Understand [API key management](/essentials/api-keys)
* Check out our [API reference](/api-reference/authentication) for detailed endpoint documentation
## Need Help?
If you run into any issues:
* Check our detailed feature guides in the documentation
* Contact support at [hello@pulpminer.com](mailto:hello@pulpminer.com)
* Visit our GitHub repository for examples and updates